



Apache 2.0 on the poster, a waitlist on the website. That's the state of Beam as we write this. Reflection AI announced the model on 5 October 2026: a 501B mixture of experts with 23B active parameters, aimed at coding and agents. You can't download it yet. The company says weights, a model card and a technical report arrive later in October.
The short answer
Beam is Reflection's first open-weight model, a text-only sparse mixture of experts with 501B total and 23B active parameters. It's promised under Apache 2.0, but only a waitlist is open today. The headline claim is GLM-5.2 level reasoning at 3 to 4 times less inference compute. Every score is Reflection's own, and none can be checked until the weights land.
What Reflection actually announced
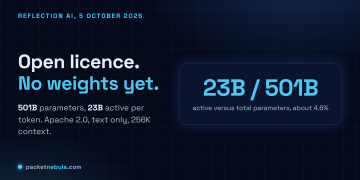
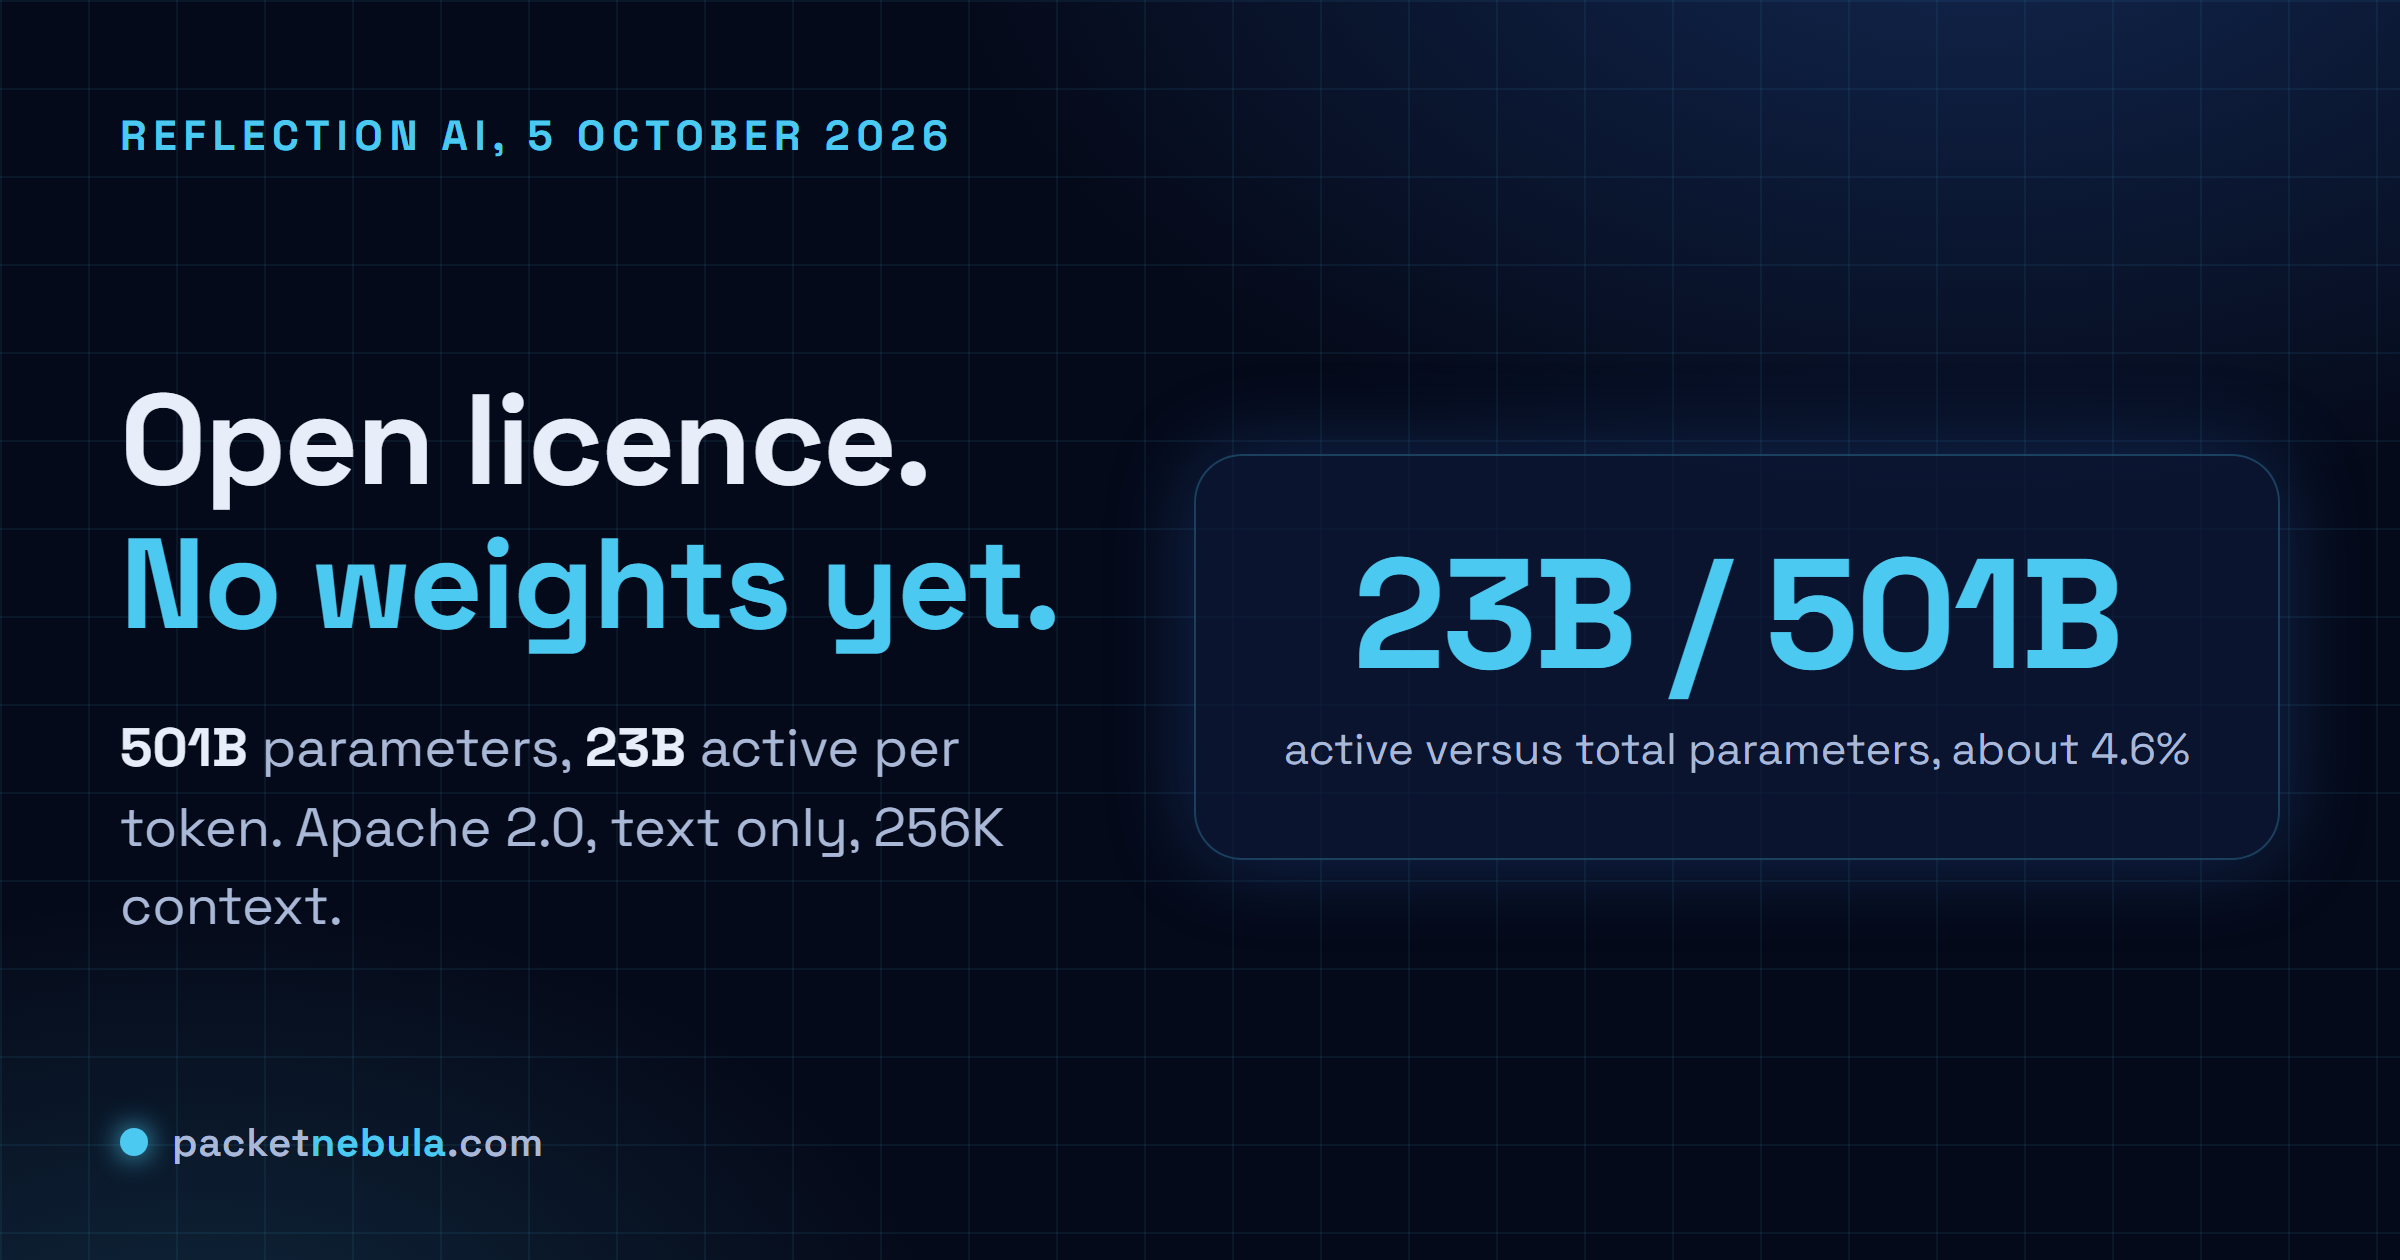
Beam is a sparse mixture of experts model. Of its 501 billion parameters, 23 billion do the work on any given token, so about 4.6% of the network is awake at a time. It's text only. The context window is 256K tokens, and Reflection says midtraining stretched it to 1M.
The training numbers are big. Pretraining ran on 23.8 trillion tokens from the web and licensed data. The reinforcement learning stage used over 100 million rollouts on 10,500 NVIDIA GB300 GPUs across four weeks. One analysis puts model FLOPs utilisation during pretraining at roughly 12% in BF16, which is a polite way of saying the run was far from perfectly efficient.
Pricing isn't disclosed. Access today means joining a waitlist at Reflection's platform. Several outlets describe the company as Nvidia-backed, and it's pitching Beam as an American answer to the open-weight models coming out of China. That framing is marketing, but the licence, if it holds, is real.
The claims, and the catch
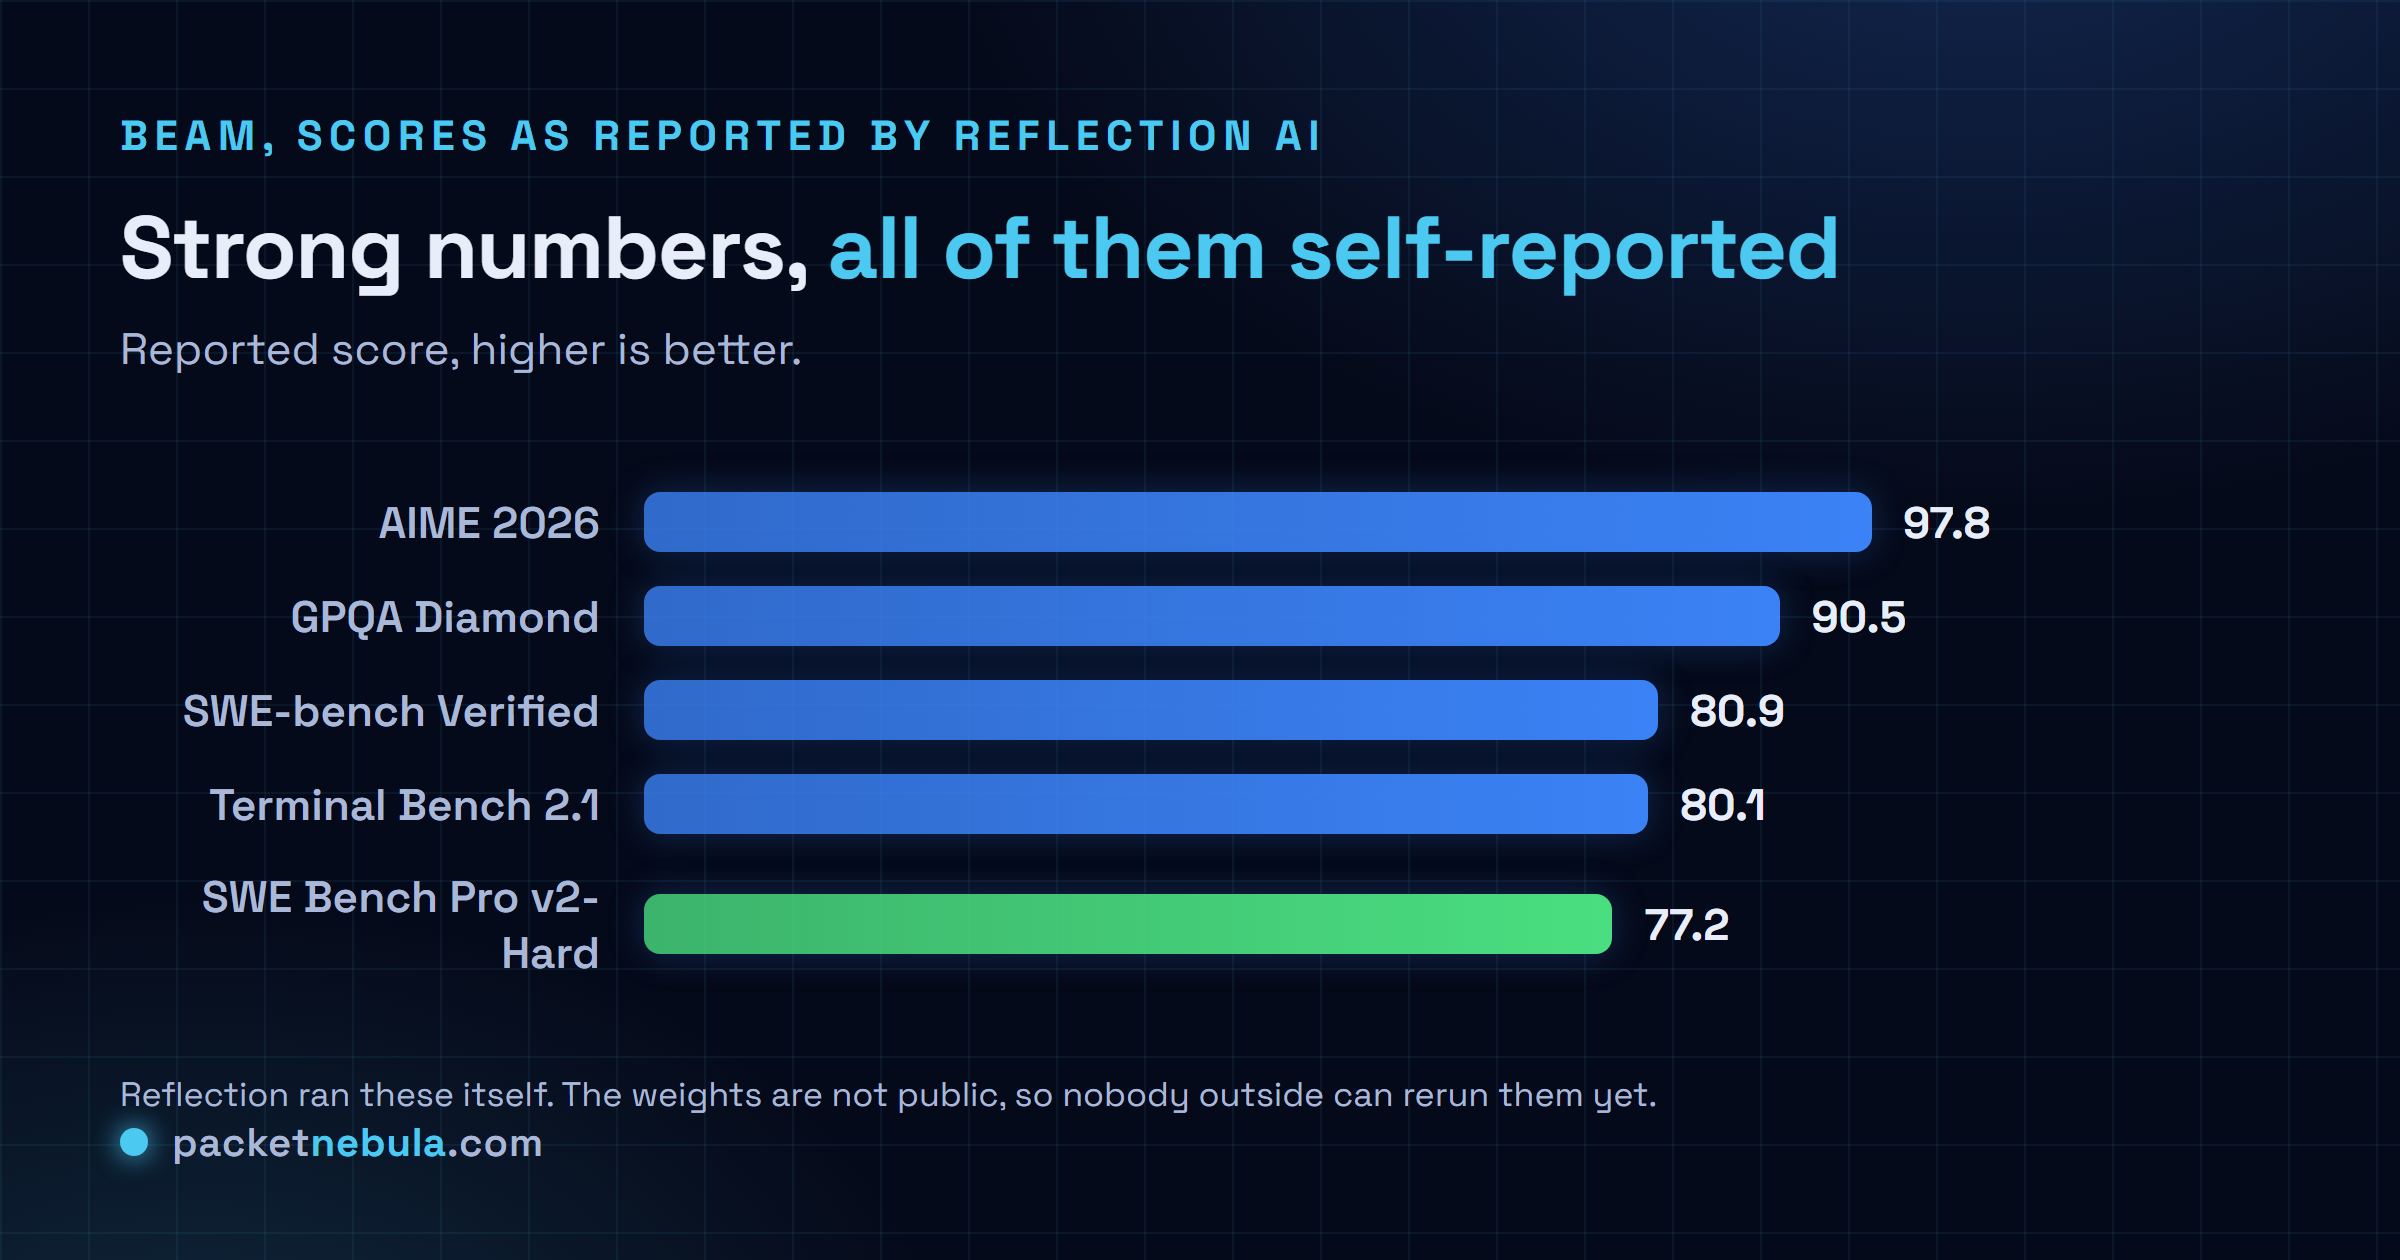
Reflection's own post lists AIME 2026 at 97.8, GPQA Diamond at 90.5, Terminal Bench 2.1 at 80.1 and SWE Bench Pro v2-Hard at 77.2. Coverage of the launch also quotes 80.9 on SWE-bench Verified. We've put them in one chart, and honestly the chart mostly shows how little we can say.
The more interesting claim is efficiency. Reflection says Beam matches Z.ai's GLM-5.2 on reasoning while using three to four times less inference compute. A newsletter analysis calls it among the most token-efficient open models for its level, and also places it around GLM-5.2's tier, behind some Chinese models such as DeepSeek V4 Flash. So the pitch isn't "best". It's "as good as last month's leader, much cheaper to run".
I'd take that seriously, with a caveat. Efficiency per task depends on how many tokens a model spends thinking, and that varies by prompt and harness. A vendor can pick a flattering setup without lying. We'd wait for third-party runs before quoting the 3 to 4 times figure anywhere that matters.
Should you wait for the weights?
If you run open models yourself, yes. At 501B you're looking at multiple high-memory GPUs even with only 23B active, because every expert still has to sit in memory. We don't know the hardware guidance yet, and Reflection hasn't published quantised sizes.
If you're comparing options now, our GLM-5.2 comparison is the baseline Beam is aiming at. For another large open release with its own caveats, see Tencent's Hy3. Our take: a US lab shipping Apache 2.0 weights at this size is worth watching, and worth nothing at all until the download link works.
Image: packetnebula.com, built from Reflection AI's published figures.
Sources
Reflection AI, Introducing Beam: Reflection's 501B open-weight model, 5 October 2026 (specs, licence, release timing, benchmark scores). Latent Space, Reflection Beam, 501B-A23B American Open Model (independent analysis, efficiency and comparison). MarkTechPost, Reflection AI introduces Beam (launch coverage).
Frequently asked questions
Can I download Beam today?
No. Reflection says weights, a model card and a technical report arrive later in October 2026. For now there's a waitlist.
What licence will Beam use?
Apache 2.0, which allows commercial use. That's the announced plan, and it'll only count once the weights are published.
How big is Beam?
501B total parameters with 23B active per token, a sparse mixture of experts. It's text only, with a 256K token context window.
Is Beam better than GLM-5.2?
Reflection says it matches GLM-5.2 on reasoning with 3 to 4 times less inference compute. That's the lab's claim, not an independent result.