
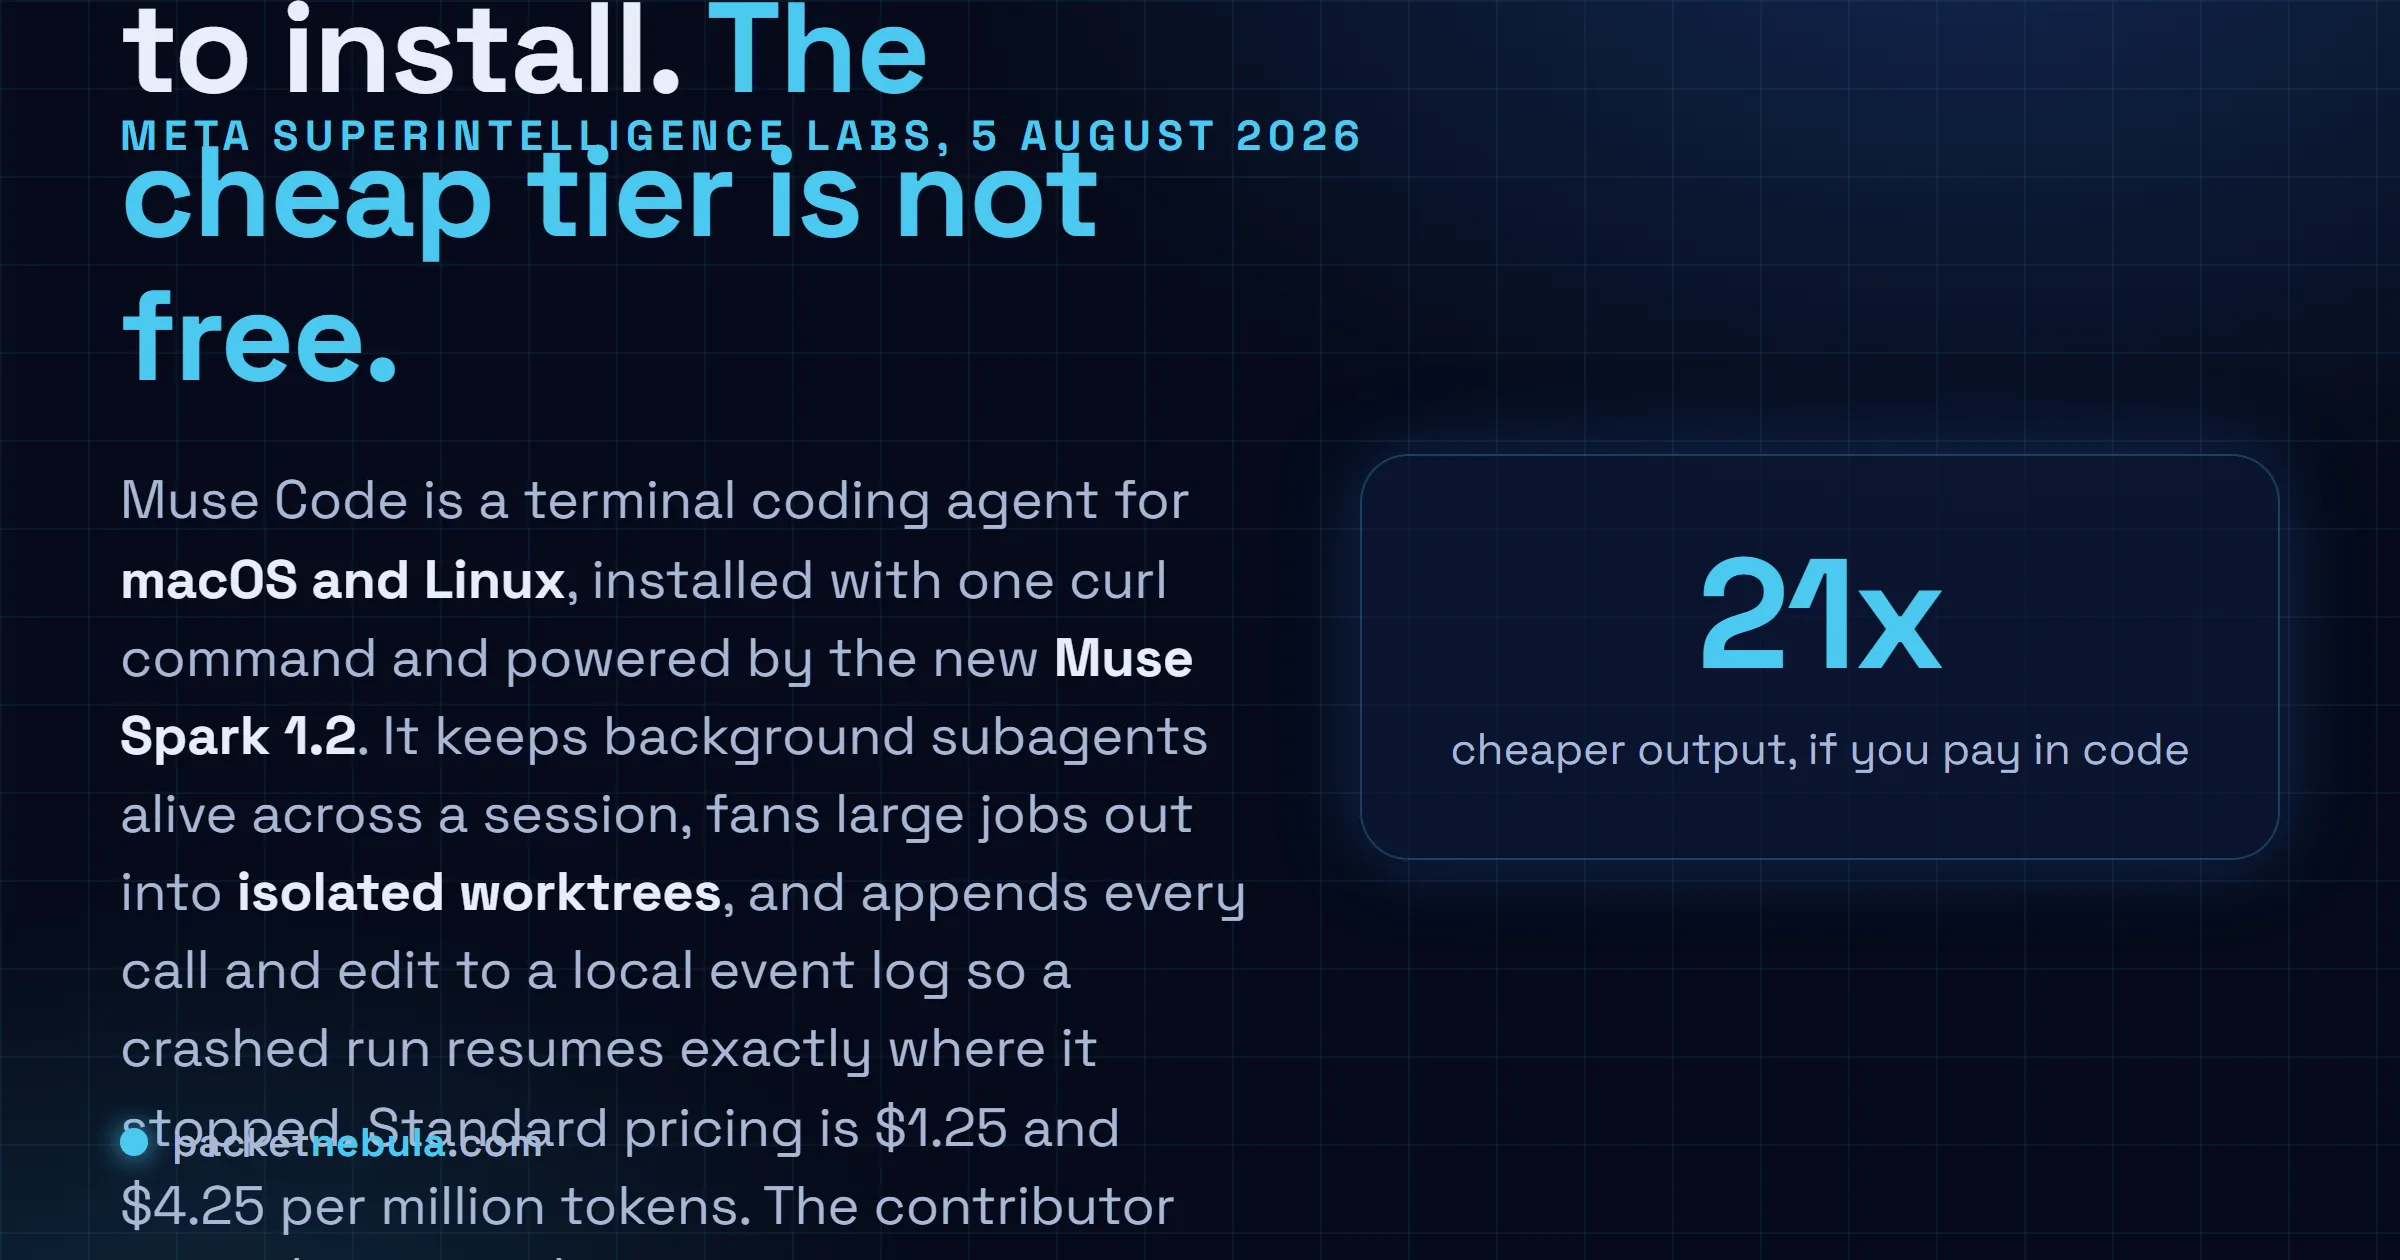
Meta published three coding benchmark charts on Wednesday and finished first on none of them. Odd way to launch, and it tells you what Muse Code is actually selling. It shipped 5 August as a terminal coding agent for macOS and Linux, one curl command to install, running on a new model called Muse Spark 1.2. The closest it gets is Terminal-Bench 2.1, where it takes 82.9 against 86.7 for Claude Opus 5. So the pitch isn't the ceiling. It's the invoice. Meta is offering a contributor tier that drops output tokens from $4.25 per million to $0.20, roughly twenty-one times cheaper, in exchange for permission to train future models on your prompts and completions. Your source code is the currency, and we'd think hard before spending it.
The short answer
Meta released Muse Code in beta on 5 August, a terminal coding agent for macOS and Linux powered by a new Muse Spark 1.2. The engineering is real: persistent background subagents, isolated worktrees, and a crash-safe event log that lets a run resume exactly where it died. The model finishes second or third on every chart Meta published. What it wins is the price, and the cheapest price is paid in your source code.
 Image: Meta, launch artwork from the Muse Code and Muse Spark 1.2 announcement.
Many threads converging into one. The artwork is a better description of the product than the blog post is.
The runtime is the interesting half
Strip the pricing away and there’s genuine engineering here. Muse Code keeps a set of specialised background agents alive for the whole session instead of spawning a fresh one per task, which Meta says cuts the redundant re-reading of the same files that makes long agent runs so slow. Those agents decide for themselves when to report back to the main loop.
Then there’s the event log. Every model call, every tool run, every approval, every edit gets appended to a local log that Meta describes as the single source of truth. The runtime is replay-exact and restart-safe, so a crash three hours into a refactor doesn’t cost you the refactor. The agent picks up precisely where it stopped. If you have ever watched a long agent run die on a network blip and had nothing to show for it, you know why that’s the line in the announcement we’d underline.
Three bundled skills ship by default. /plan turns a task into an approval-gated plan, /grill stress-tests that plan until it holds, and /goal drives toward a stated objective. Approval gating on the plan rather than on each edit is a sensible default, and it’s roughly where the rest of the field has landed too.
The fan-out is the demo everyone quoted. Mark Zuckerberg put it this way on X: “When a job is big enough, it fans out to separate sub-agents working in parallel in isolated worktrees.” Meta says it built six features for a game simultaneously with no collisions in testing. Worth noting that Cursor was swarming agents at a whole SQLite reimplementation back in July, so parallel-agents-in-worktrees is now a pattern rather than a differentiator.
The case study we’d actually chase down is the kernel one. Meta ran the model on GPU kernel optimisation for KDA and MLA on NVIDIA Hopper, over 1,000 tool calls and up to 24 hours per run, writing Triton by hand with third-party kernel libraries explicitly banned so it couldn’t just wrap an existing implementation. Whatever you think of the benchmarks, a 24-hour agent loop that survives to the end is a different class of claim from a 20-minute one.
Meta published charts it loses
This part is unusual, and I’d rather credit it than mock it. Meta put its own coding numbers next to four named rivals and came second or third on all three.
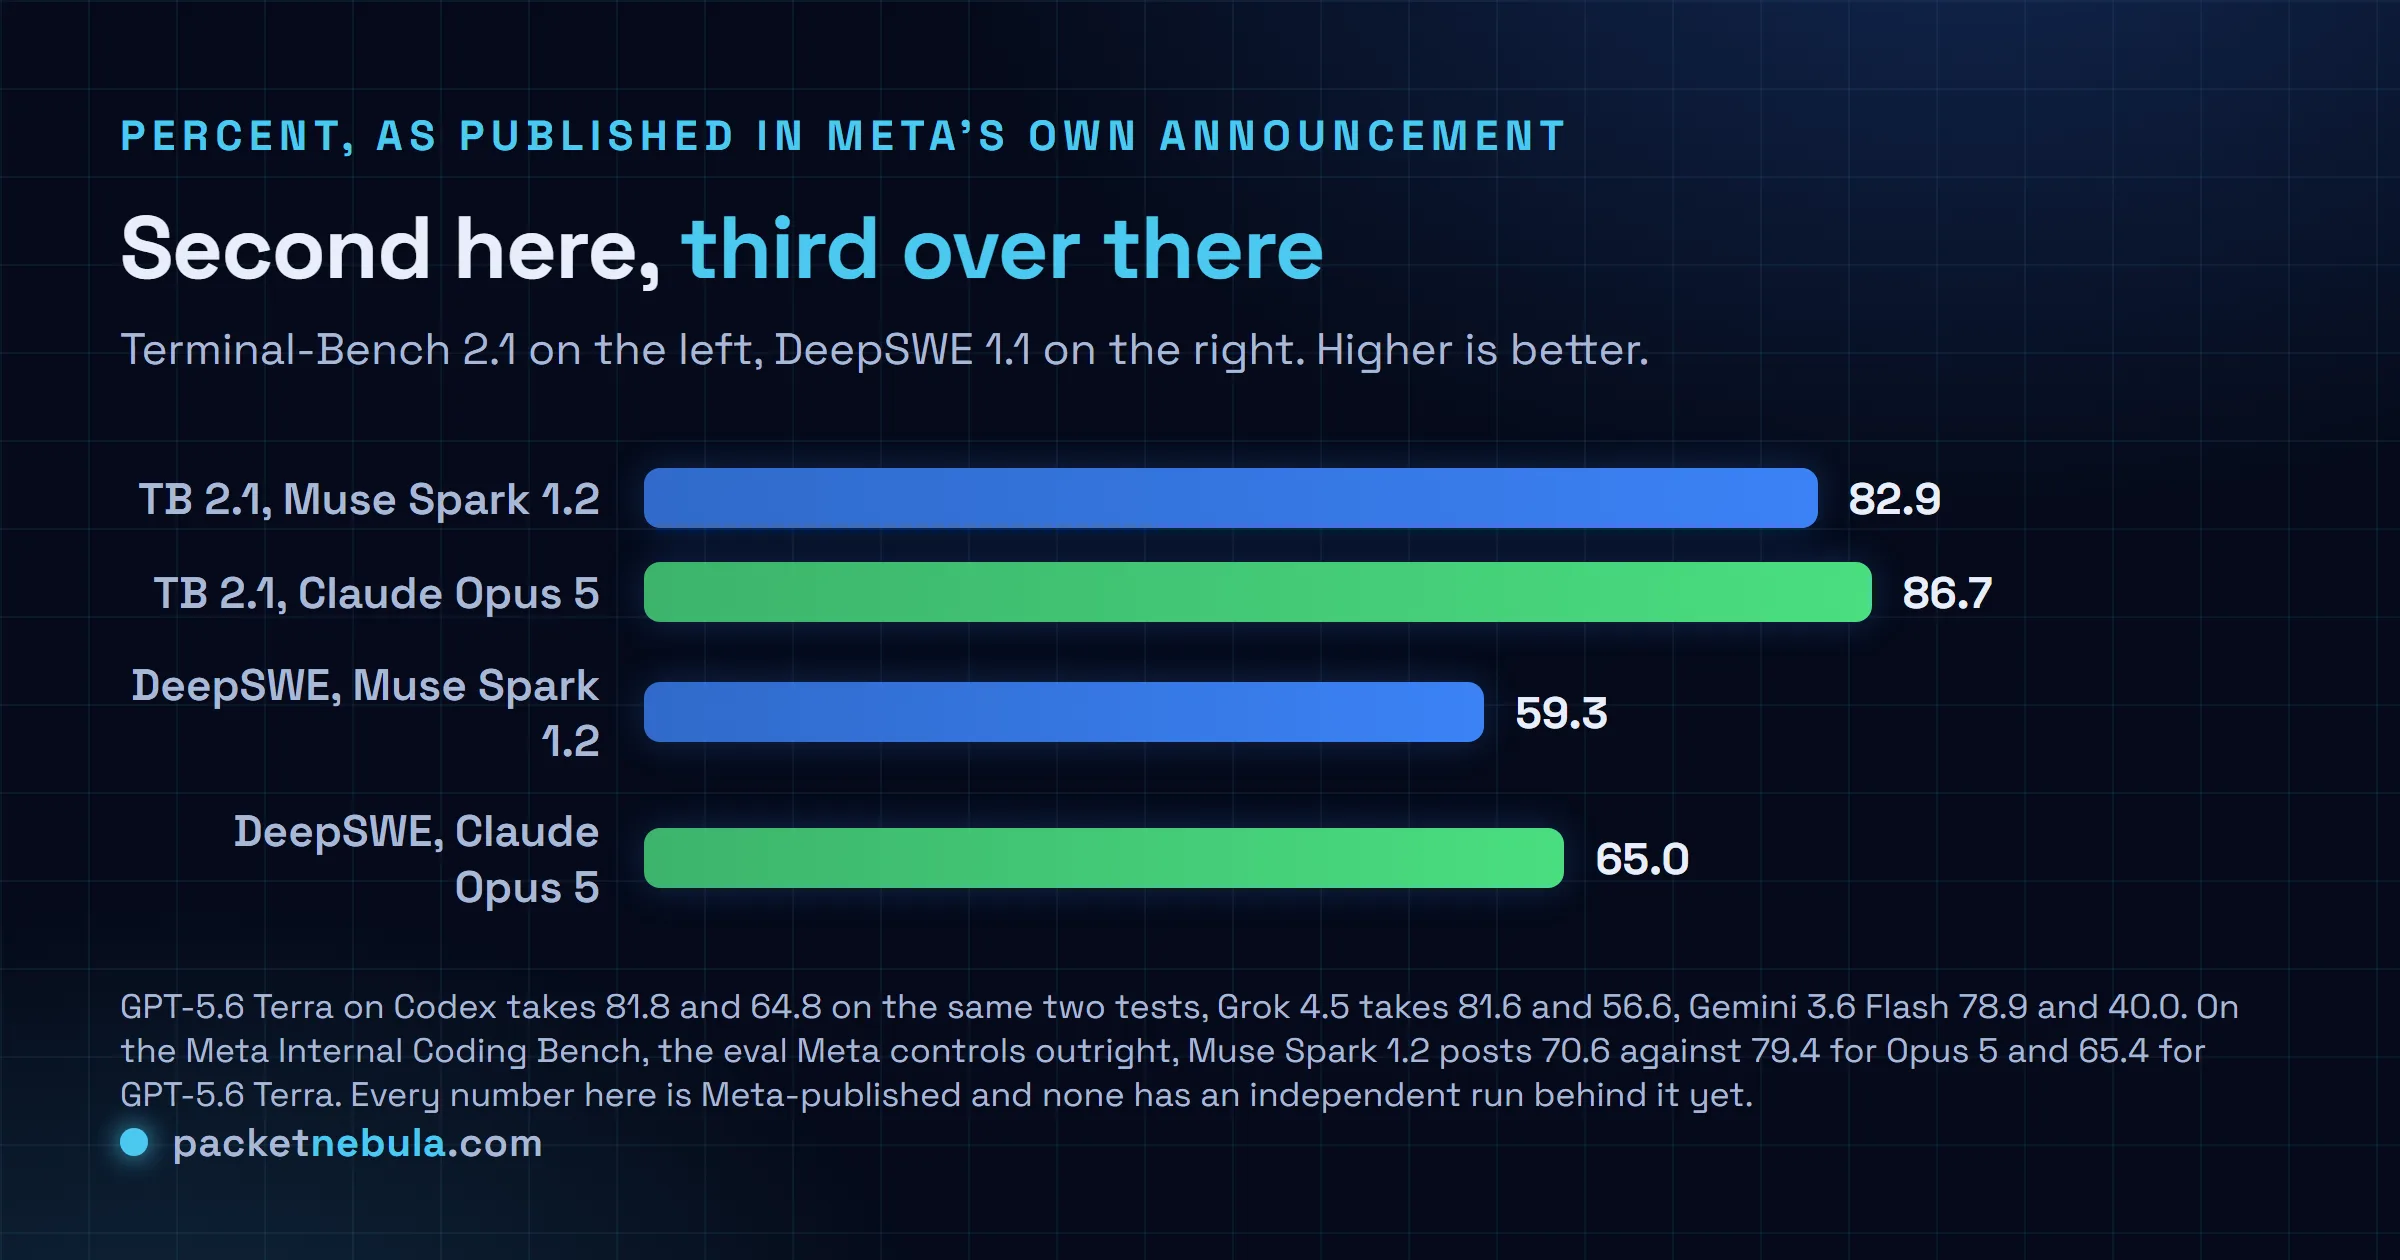
Terminal-Bench 2.1 has Muse Spark 1.2 at 82.9, behind Claude Opus 5 on Claude Code at 86.7, ahead of GPT-5.6 Terra on Codex at 81.8, Grok 4.5 at 81.6 and Gemini 3.6 Flash at 78.9. DeepSWE 1.1 is worse for Meta: 59.3 against 65.0 and 64.8 for the two leaders. And on Meta’s internal coding bench, the one it controls entirely, it posts 70.6 against 79.4 for Opus 5. Losing on your own private eval is a strange thing to publish and a slightly reassuring one.
One caveat that has been raised and that we can’t resolve: some of the gain from Muse Spark 1.1 to 1.2 reflects the new harness rather than the model. Meta co-trained the two together, which is good product engineering and makes the model number nearly meaningless in isolation. You aren’t buying Muse Spark 1.2. You’re buying Muse Spark 1.2 inside Muse Code.
The discount is a licence, and the cap is the catch
Standard tier runs $1.25 per million input tokens, $4.25 output, $0.15 for cached input, with a no-training commitment attached. That’s the same headline rate as Muse Spark 1.1 in July, so the model got better and the price didn’t move.
The contributor tier is where it gets interesting. $0.10 input, $0.20 output, $0.002 cached. Output is about twenty-one times cheaper and input around twelve. The condition, stated plainly, is that you permit Meta to use your prompts and completions to train future models.
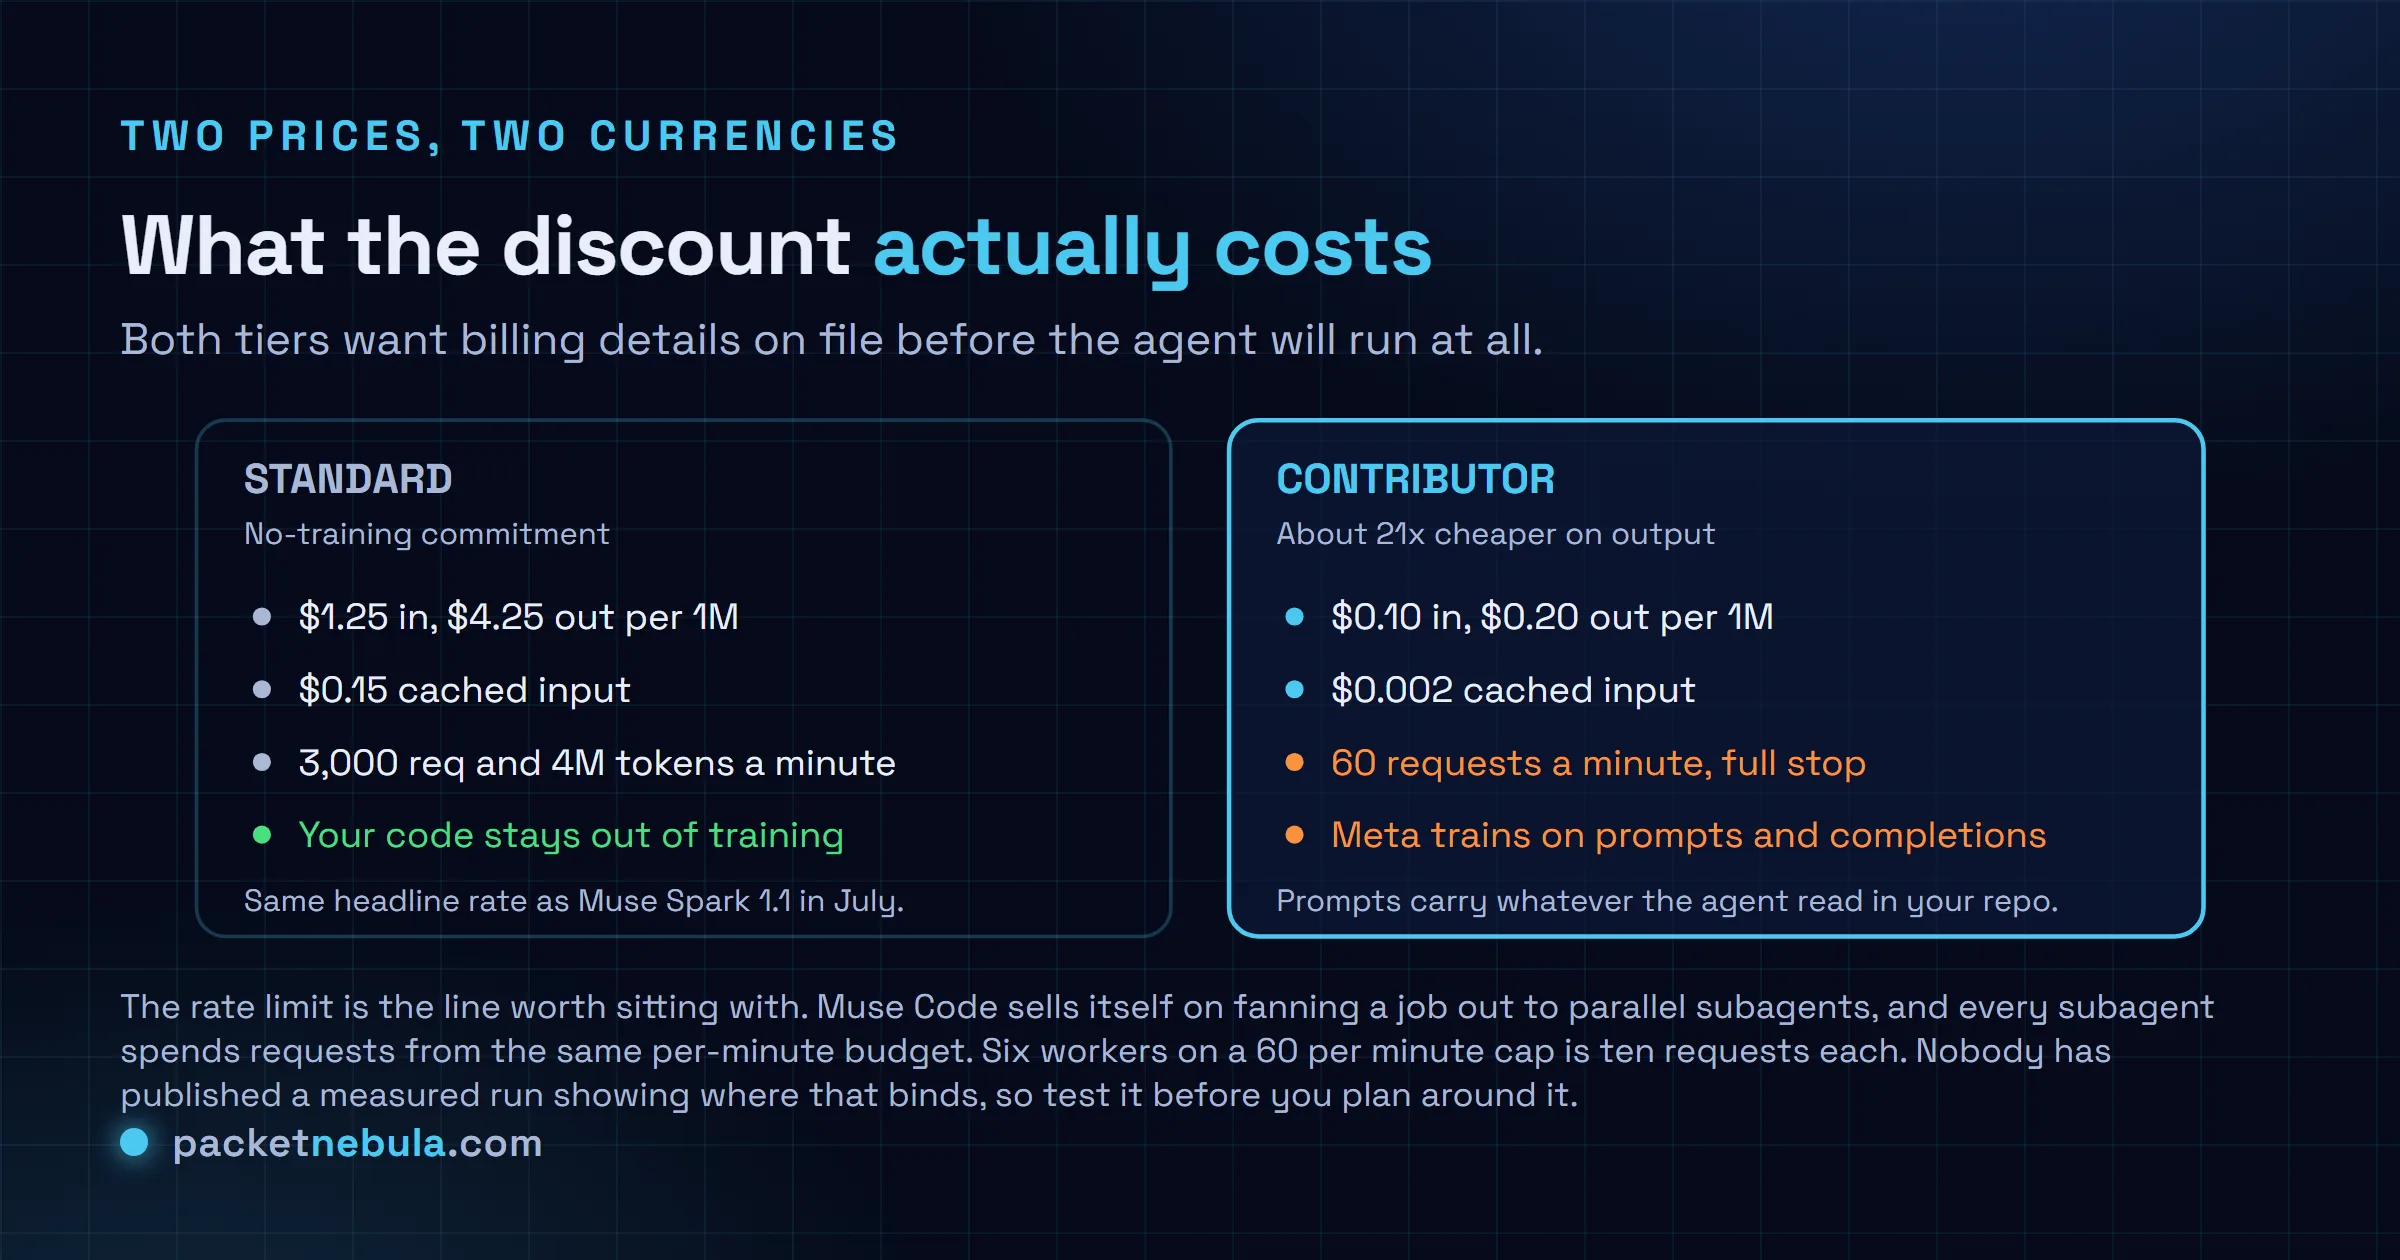
Read that through a coding agent’s lens. A prompt here isn’t a question you typed. It’s the file contents the agent pulled in, the diffs it drafted, the stack traces, the config it read on the way past. Whatever your repo contains is what goes into the prompt, which makes this a licensing question for your legal team rather than a line item for your finance team. Meta is accepting zero-data-retention requests separately, and Alexandr Wang described that as “a big enterprise feature that is important for folks”, which reads to us like it is not the default and not free.
Then the rate limits, which nobody seems to be putting next to the feature list. Contributor is capped at 60 requests per minute. Standard gets 3,000 requests and 4 million tokens per minute. Now recall that the marquee capability is fanning a job out to parallel subagents, and every subagent draws requests from that same bucket. Six parallel workers on a 60-per-minute budget is ten requests each per minute. I might be wrong about where that actually binds, since nobody has published a measured run, but the cheap tier and the parallel fan-out look like they’re pulling against each other.
One more practical snag from early testers: the agent refuses to start until billing details are on file, even on the discounted tier. Free trial, this is not.
So who’s it for. If you’re writing open source, or throwaway prototypes, or anything you’d have published anyway, the contributor tier is close to free money and you should try it. If you’re inside a company with a code confidentiality clause, the interesting price is the one you can’t take, and standard tier at $1.25 and $4.25 is a fine rate for a mid-pack model that happens to be wrapped in a crash-safe runtime. Availability got better too, incidentally: Muse Spark 1.1’s API launched as a US-only preview, while Meta says 1.2 ships with expanded global access, though it hasn’t spelled out which regions that covers.
Sources
Product details, the install command, the runtime design and the kernel case study come from Meta Superintelligence Labs, Introducing Muse Code and Muse Spark 1.2, published 5 August 2026. Benchmark scores for all five models are from that announcement as reported by explainX. Tier pricing, rate limits and the training terms are reported by Implicator and BigGo Finance, including the billing-required snag. The Zuckerberg and Wang quotes are via TechCrunch and Engadget.
Update, 7 October 2026. Meta's pricing and rate limits page now lists 100 requests a minute for the contributor tier, not 60, and Muse Spark 1.3 shipped on 2 September at the same price.
Frequently asked questions
What is Meta Muse Code?
It is a terminal coding agent Meta Superintelligence Labs released in beta on 5 August 2026, for macOS and Linux, installed with a single curl command from dev.meta.ai. It plans a change, writes the code and validates the result across a large repository, and it can fan work out to persistent subagents running in isolated git worktrees. The model underneath is Muse Spark 1.2, released the same day.
How much does Muse Code cost?
There are two tiers. Standard is $1.25 per million input tokens, $4.25 output and $0.15 for cached input, with a no-training commitment. The contributor tier is $0.10 input, $0.20 output and $0.002 cached, which is about twenty-one times cheaper on output, and it requires you to let Meta train future models on your prompts and completions. Both tiers want billing details on file before the agent will run at all.
Is Muse Spark 1.2 better than Claude Opus 5 or GPT-5.6?
Not on the numbers Meta itself published. Terminal-Bench 2.1 puts Muse Spark 1.2 at 82.9 against 86.7 for Claude Opus 5 and 81.8 for GPT-5.6 Terra. DeepSWE 1.1 puts it at 59.3 against 65.0 and 64.8. On Meta's internal coding bench it scores 70.6 against 79.4 for Opus 5. So it sits mid-pack on frontier coding and wins on price, which is a coherent position, just not the one the launch language implies.
What happens to my code on the contributor tier?
Meta gets permission to use your prompts and completions to train future models. In a coding agent, prompts are not just questions: they carry the file contents the agent read, the diffs it proposed and whatever secrets happen to be sitting in the repo. That is a licensing and compliance decision, not a billing one. Zero data retention is being handled as a separate request process, and Meta's AI chief has described it as an enterprise feature rather than a default.
What is the rate limit on the cheap tier?
60 requests per minute, against 3,000 requests and 4 million tokens per minute on standard. That gap matters more than it looks, because the headline feature is fanning a job out to parallel subagents and every one of those subagents spends requests from the same budget. We have not seen anyone measure where 60 per minute actually binds, so treat it as a thing to test rather than a verdict.


