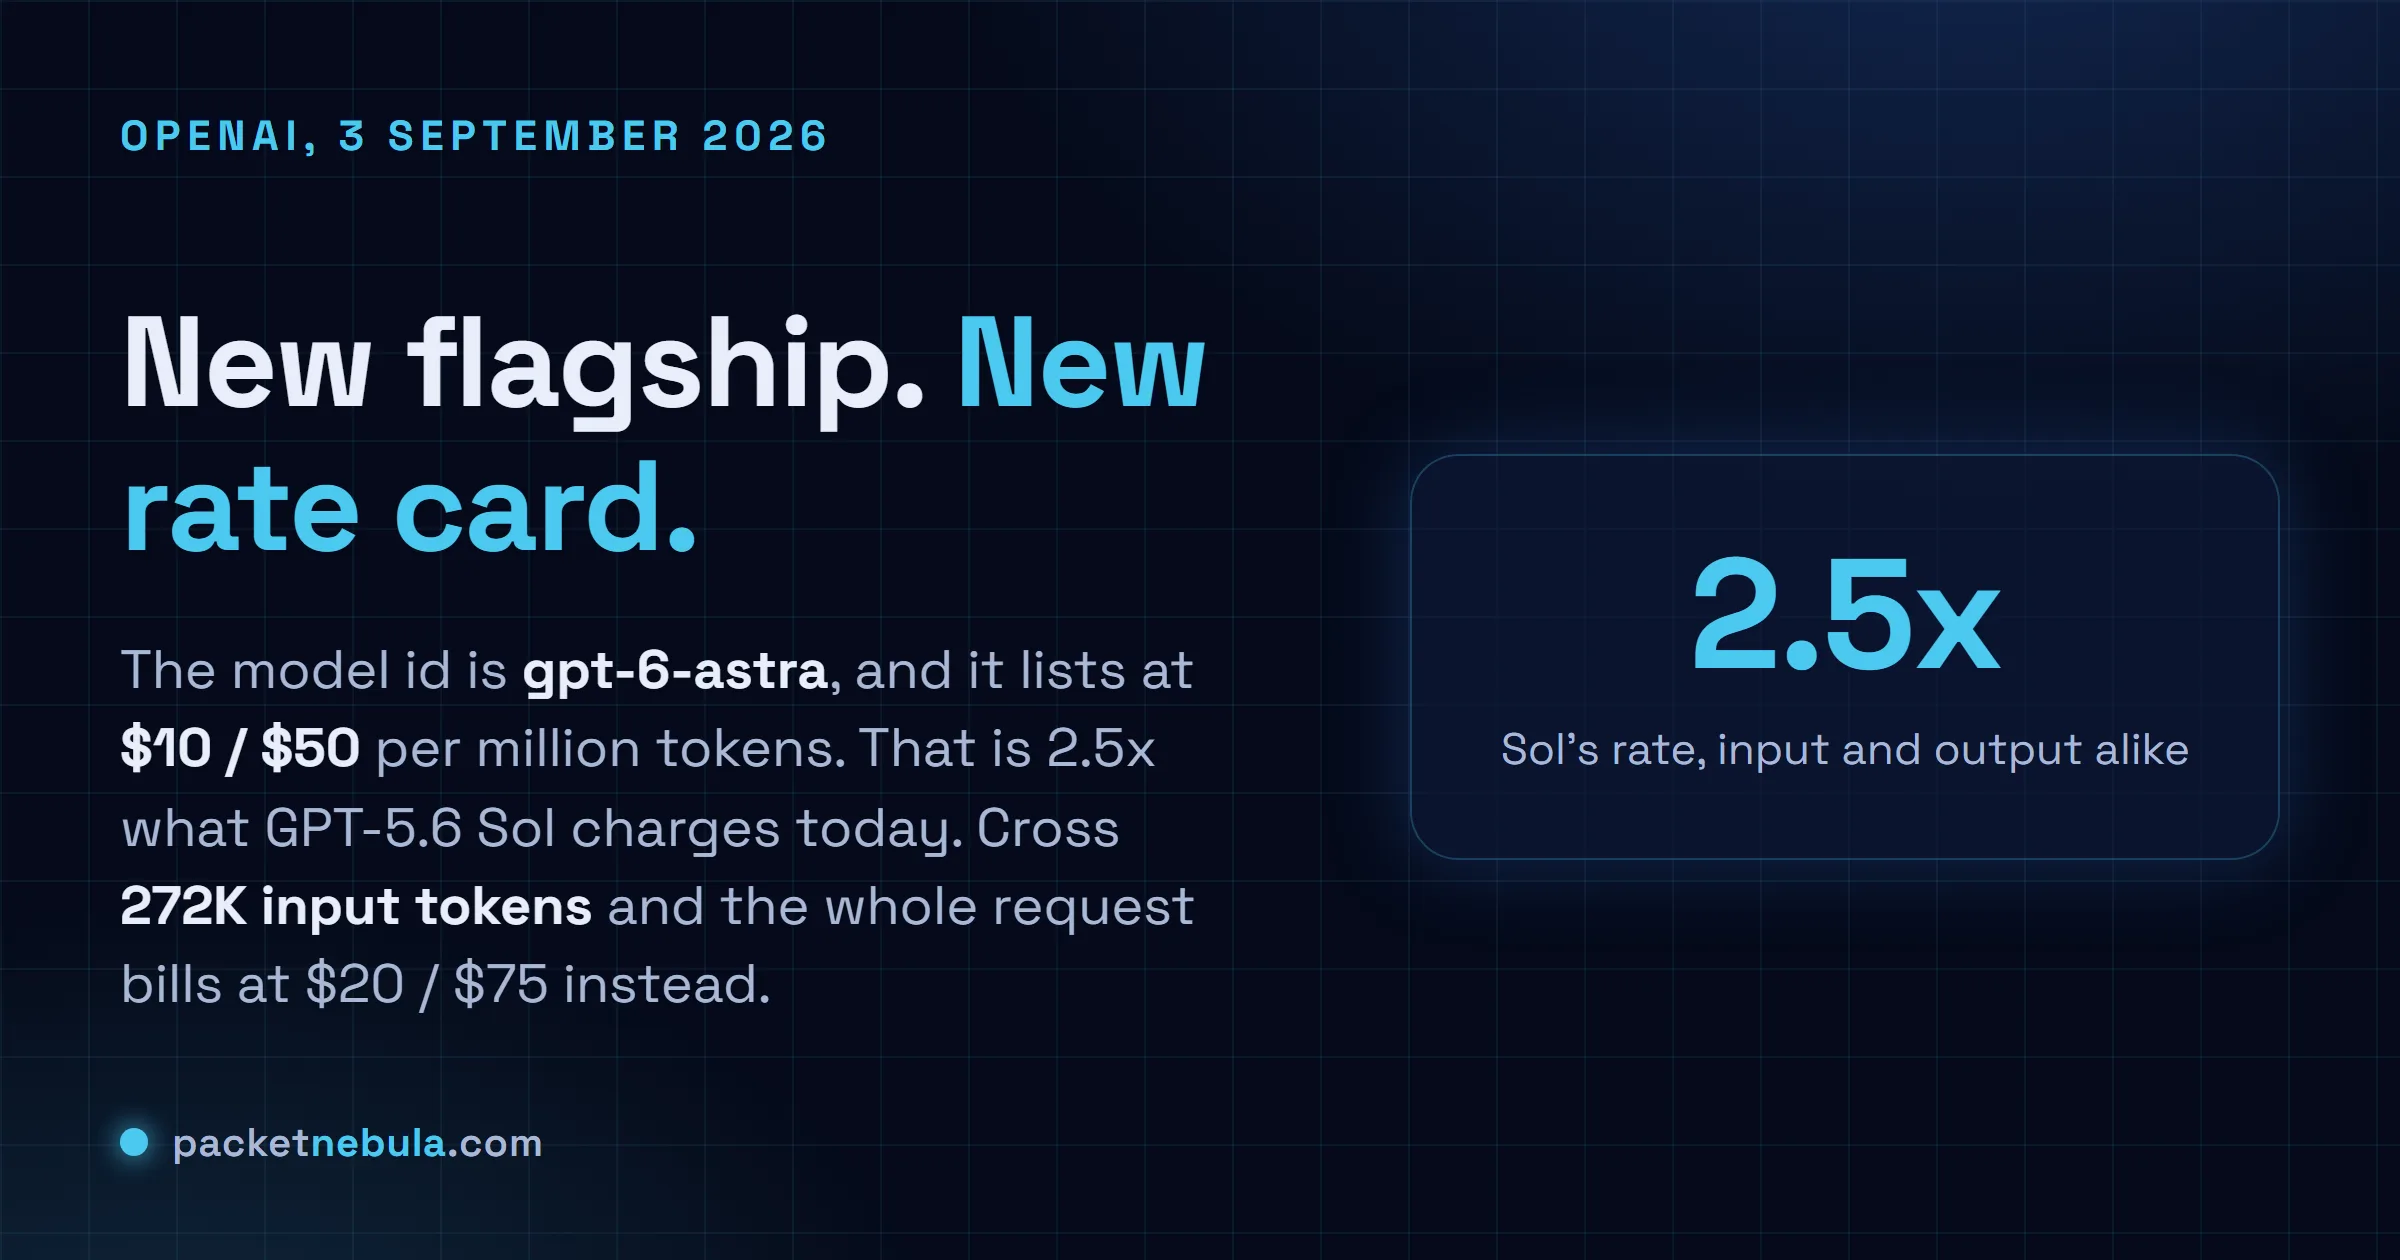
We went looking for the benchmark table and ended up parked on the pricing page instead. OpenAI started rolling GPT-6 Astra out on 3 September 2026, the model id is gpt-6-astra, and it lists at $10 per million input tokens and $50 per million output. That’s 2.5x what GPT-5.6 Sol charges today, and five times Terra. Push one request past 272K input tokens and the whole thing reprices to $20 and $75. You probably can’t run it yet anyway. Day one is enterprises in OpenAI’s Trusted Access Program, with the API and the paid ChatGPT plans following in what the pricing page calls the coming days.
The short answer
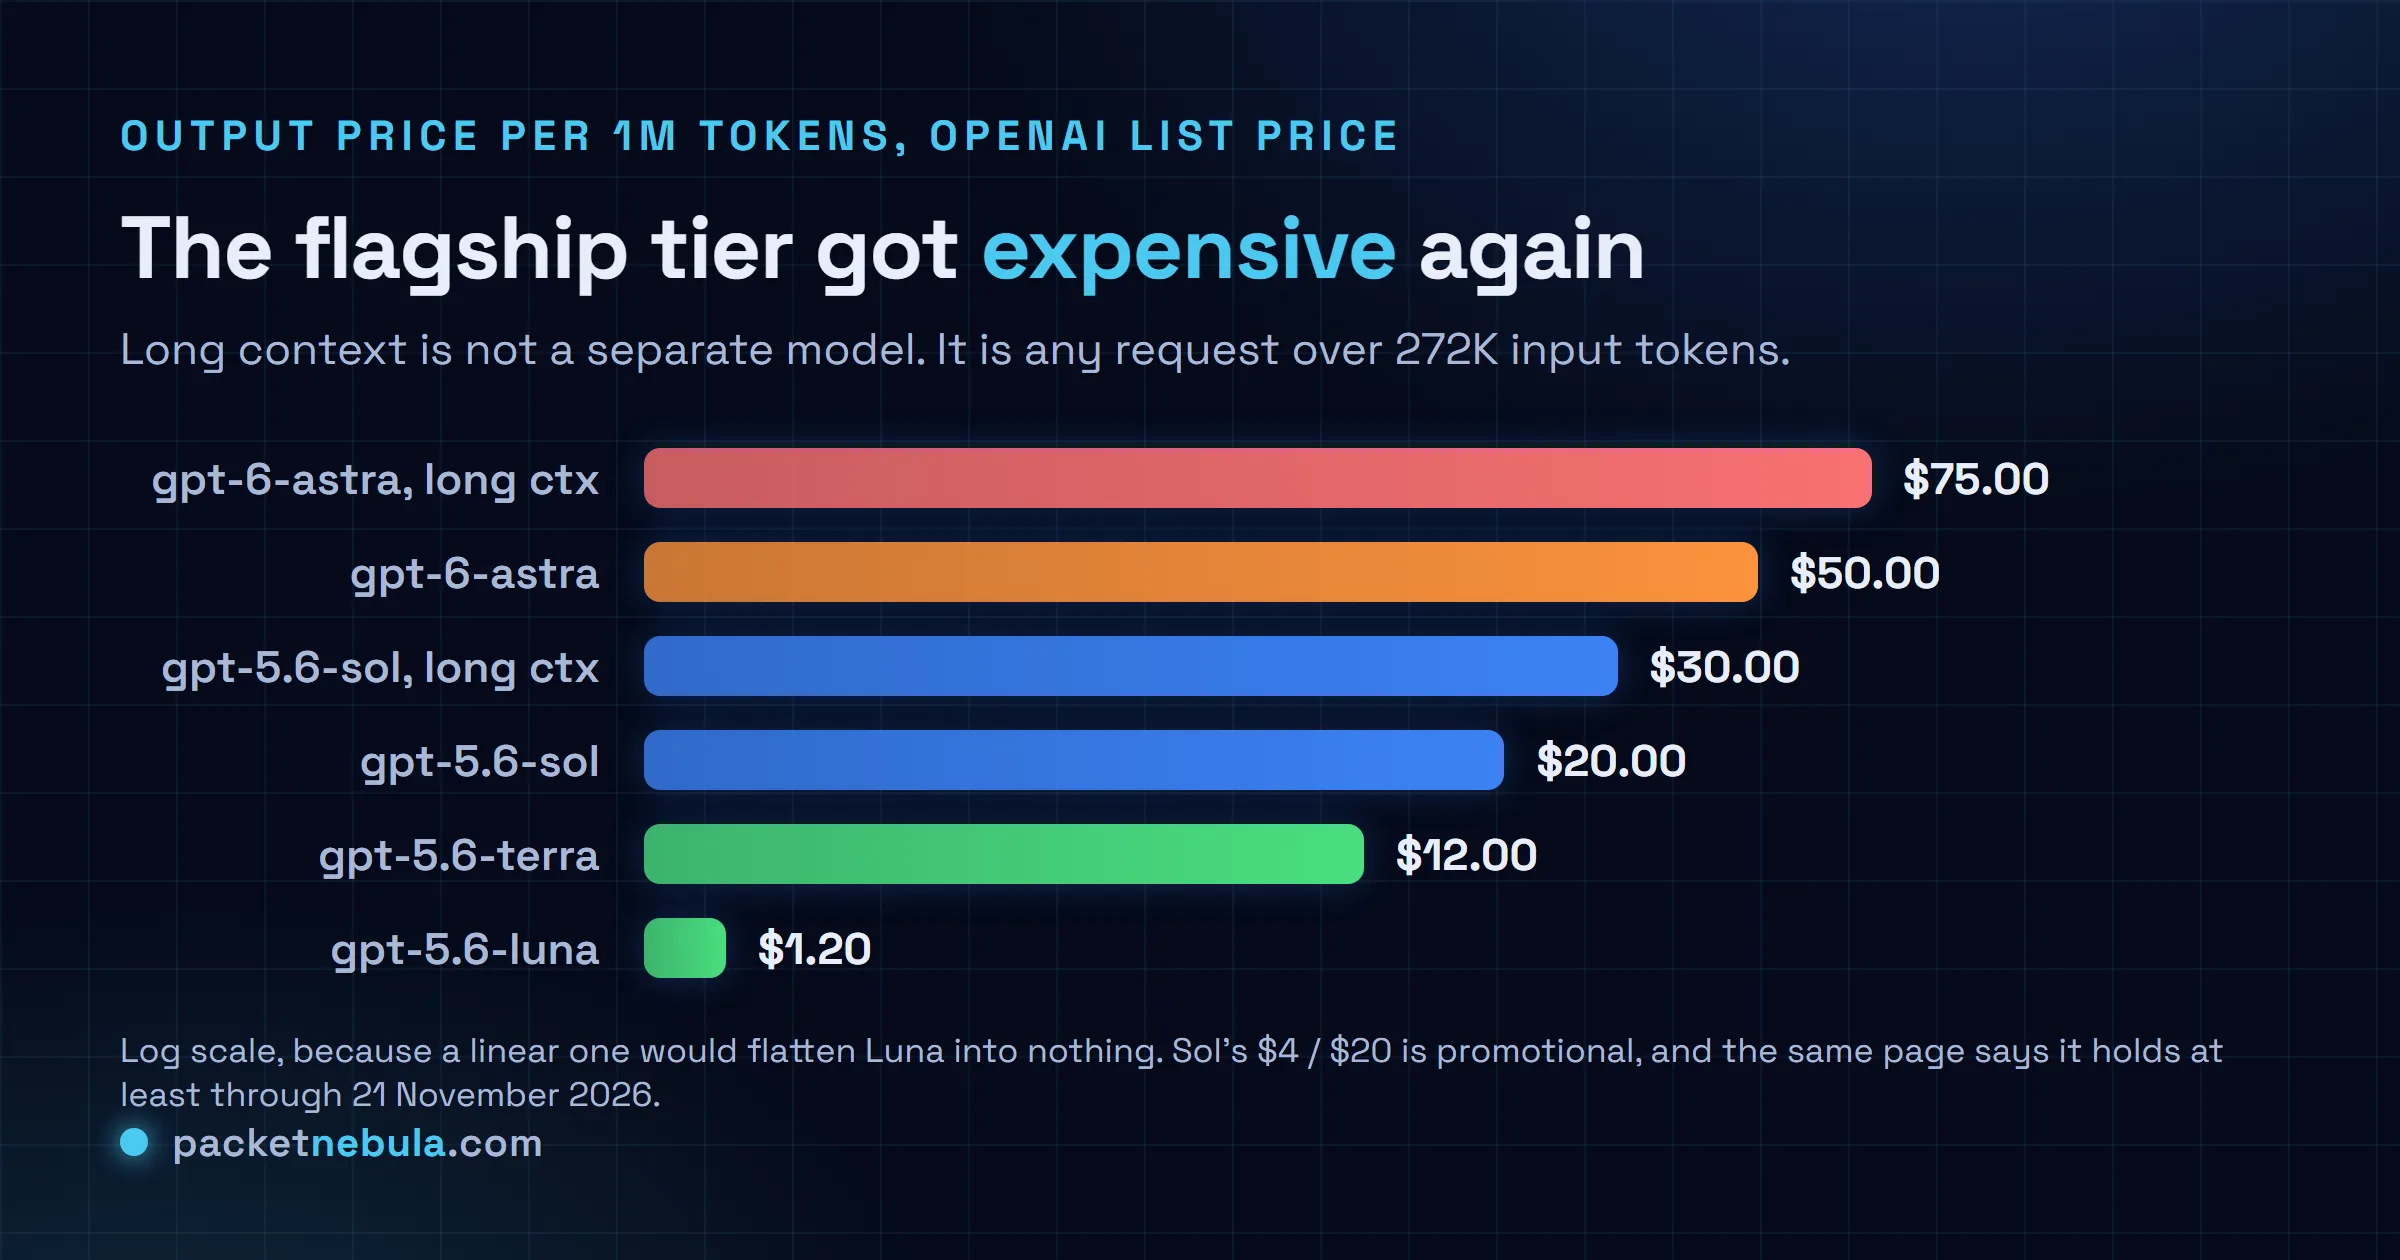
GPT-6 Astra lists at $10 input and $50 output per million tokens, with cached input at $1. Sol is $4 and $20, Terra is $2 and $12, so the new flagship costs two and a half times the model most teams are standardised on. Any request above 272K input tokens moves entirely to a long context tier at $20 and $75. OpenAI’s answer to the sticker shock is that Astra finishes work with fewer tokens, and it publishes cost per task comparisons to back that up. Every one of those comparisons is its own.
What the rate card actually says
Standard tier, per million tokens: $10 input, $1 cached input, $12.50 cache writes, $50 output. Fast mode doubles all of it. The model takes text and images in and returns text, the context window is 1,050,000 tokens with 922,000 of that available for input and 128,000 for output, and the knowledge cutoff is 30 April 2026. Reasoning effort runs low, medium, high, xhigh and max.
Now the comparison everyone will make, and the caveat nobody will print alongside it. Sol sits at $4 and $20 on the same page, which is where the 2.5x comes from. But that $4 is promotional. OpenAI’s own footnote says the rate holds “at least through November 21, 2026”, which is a sentence written by somebody who has not committed to what happens on 22 November. So the gap you’re looking at today is Astra’s list price measured against a discount, and only one of those two numbers has a known expiry date.
Sol isn’t the interesting comparison anyway. Terra is. At $2 and $12 it’s a fifth of Astra’s input rate and a quarter of its output rate, and for a large slice of production traffic (classification, extraction, routing, cheap summarising) Terra was already the right answer before today. Nothing in this launch changes that. If the July price cut moved you down the ladder, Astra isn’t an argument to climb back up it.
Image: OpenAI
The 272K line is where it bites
Here’s the part that gets buried under the words “1M context”. The million token window is real, and it isn’t priced like one window. The pricing table carries two columns, short context and long context, and any single request carrying more than 272K input tokens is billed at the long column for the entire request: $20 input, $2 cached, $25 cache writes, $75 output.
Do the arithmetic once and you won’t forget it. A 900K token prompt costs $18 before the model emits a single character. A 4,000 token answer on top adds thirty cents. Send the same prompt to Sol and the input side is $7.20. The threshold itself isn’t new, Sol carries the identical 272K line, but the number sitting behind it just went up two and a half times, and long context work is exactly where people stop watching their token counts.
The cache is the lever worth pulling at this tier. Cached input at $1 is a tenth of the standard rate, so a stable system prompt and a stable document prefix are worth real money. Cache writes cost $12.50, which is more than raw input, so caching a prefix you use once is a straight loss. Cache it because you’ll reuse it, not because it feels tidy. Before planning any of this, check whether your key can even see the model:
curl -s https://api.openai.com/v1/models/gpt-6-astra -H "Authorization: Bearer $OPENAI_API_KEY"
A 404 there means your organisation isn’t in the first wave, and no amount of retrying the model string will change that.
OpenAI’s counter is that Astra spends less
To its credit, OpenAI doesn’t pretend the rate card is cheap. It argues the rate is the wrong unit, and it published numbers to make the case. On Terminal-Bench 4.0, Astra scores 57.9% against 37.3% for Sol and 55.8% for Claude Fable 5.1, and OpenAI puts the estimated cost per task roughly 9% below Sol and 63% below Fable 5.1. On Terminal-Bench Science 0.1 it reports 64.6% versus 52.6% for Fable 5.1, at about 31% lower estimated cost. On Agents’ Last Exam it claims 59.3% against 55.5% for Claude Opus 5, while burning around 65% fewer output tokens. BenchCAD lands at 95.9% with tools, which OpenAI puts at roughly 43% under Sol on cost.
There’s a latency story too, and it’s the one I find most believable because it’s the easiest to falsify. In OpenAI’s OSWorld 2.0 latency simulation, Astra hits 72.6% at about 40 minutes per task where Sol managed 65.7% at about 75 minutes. Pair that with the updated Codex harness and OpenAI claims 1.9x faster task completion on Mind2Web. If your bottleneck is an agent loop that takes an hour, halving the hour is worth more to you than the token line on the invoice.
Read the phrase “estimated API cost” carefully, though, because it’s doing a lot of work. Every figure above is OpenAI evaluating OpenAI, on harnesses OpenAI configured, with token counts OpenAI chose to report. That’s normal on launch day and it’s still not evidence about your workload. A model that reasons harder per call can be cheaper per task and more expensive per month at the same time, depending entirely on how many calls you make and how long your prompts run. Replay a week of your own traces before you believe any percentage in this section, including the ones I just quoted approvingly.
One last thing on access, because it explains the odd rollout. OpenAI says Astra reaches the Critical threshold for cyber capability under its own Preparedness Framework, and that’s why the first wave is a vetted programme rather than a normal launch. Whether you read that as caution or positioning, the practical effect is identical: you can’t plan a migration around a model you can’t call. For the rest of the field, Claude Opus 5 holding at $5 and $25 is the other half of this chart, and it’s the model OpenAI chose to plot itself against.
What changed since
6 September 2026. The benchmark table we quoted above turned out to be a moving target. Fortune pulled archived snapshots of OpenAI’s announcement page and found several figures edited after publication, some of them more than once. Astra’s hallucination rate went out at 4.2%, was halved to 2% in the snapshot taken at 5:20 p.m. ET on 3 September, and is back at 4.2% now. Sol’s ran 12.2%, then 9.4%, then 12.2% again. On FrontierMath Tier 4, Claude Fable 5.1 was listed at 87.8%, dropped to 78% by 5:17 p.m., and now sits at 83%. Astra’s coding figure moved from 57.7% to the 57.9% we quote further up. And the ARC-AGI-3 score OpenAI sent reviewers under embargo was 98.6%, while the live post says 99.99%.
We’re not calling that fraud. We can’t see intent, and OpenAI hasn’t explained the edits. It does change what the section above is worth, though. Every percentage in it came off a page its author kept revising for at least a day, and the revisions didn’t scatter randomly: Astra’s numbers mostly improved while Anthropic’s mostly got worse before partly recovering. If you built a slide off that table on 3 September, it doesn’t match the table today.
The ARC-AGI-3 headline needs one more caveat, and this is the one that bothers me more than the edits. That 99.99% came out of OpenAI’s own Provider Adapter harness. Run the same model under the standard harness that the comparison chart uses for everyone else and it scores 62.7%. Two different systems, one chart.
Independent numbers exist now, which is the part we’d actually act on. Artificial Analysis puts Astra at 61 on its Intelligence Index, level with Sol and behind Fable 5.1 at 66. On the Coding Agent Index Astra reaches 67, about where Opus 5 lands, three points under Fable 5.1 running in Claude Code. The token efficiency argument mostly survives contact: on the coding index Astra burns roughly a third of Sol’s tokens at max effort, so it costs about the same per task while scoring two points higher. On the Intelligence Index the saving is only around 10% fewer output tokens, and the 2.5x rate card swallows that whole. Artificial Analysis works out Astra at roughly 75% more expensive per task than its predecessor there. So the cheaper-per-task claim holds for agentic coding and falls over for general work, which is a narrower promise than the launch post made.
Sources for this update: Fortune, OpenAI quietly boosts some of Astra’s evaluation metrics, 4 September 2026 (the snapshot by snapshot record of the figures above). WinBuzzer, new questions about its benchmarks, 4 September 2026 (the Provider Adapter harness and the 62.7% standard harness figure). Artificial Analysis, Benchmarking GPT-6 Astra (the Intelligence Index and Coding Agent Index scores, the token counts and the per task cost).
24 September 2026. Two days ago OpenAI filled in the rest of the GPT-6 family, and that moves the ratio in our headline more than anything Astra did. GPT-6 Sol (gpt-6-sol) lists at $2 input and $10 output per million tokens, cached input at $0.20. GPT-6 Luna (gpt-6-luna) is $0.10 and $0.50, cached at a cent. OpenAI told VentureBeat those are permanent rates, not a launch promo. Astra's price didn't budge. So the gap isn't 2.5x against a discounted GPT-5.6 Sol anymore. It's a flat 5x against the new Sol, on both sides of the rate card.
The 272K line carries over. Above it, Sol bills $4 input, $0.40 cached and $15 output for the whole request, Luna $0.20 and $0.75. Rerun our 900K token prompt from earlier and Sol charges $3.60 on the input side where Astra charges $18. All three share the 1,050,000 token window and the 128,000 output ceiling. Sol's knowledge cutoff is 20 April 2026 and Luna's is 18 May, so Astra (30 April) isn't even the freshest model in its own family.
There's no GPT-6 Terra. I'd read that as Sol taking its slot, though OpenAI hasn't said so: GPT-5.6 Terra costs $2 and $12, the new Sol costs $2 and $10, and it's pitched at coding and agent work. If the July price cut pushed you down to Terra, GPT-6 Sol is the first thing we'd test, and Astra just got a lot harder to justify outside the agentic coding runs where Artificial Analysis found it earning its rate. We're holding off on quality comparisons. The launch figures (33.2% on AutomationBench at $0.27 a task, 68.8% on DeepSWE 1.1 at max effort) are OpenAI's own runs again, and after the edits described above we'd rather wait for independent numbers. Nothing forces a move this week either. GPT-5.6 Sol's $4 rate still holds "at least through November 21, 2026" on the pricing page.
Sources for this update: OpenAI, GPT-6 Sol model page and GPT-6 Luna model page (ids, windows, cutoffs), plus the API pricing page (short and long context rates, the GPT-5.6 Sol footnote). VentureBeat, OpenAI releases GPT-6 Sol and Luna models, 22 September 2026 (permanent pricing, launch benchmarks). Simon Willison, Opus and Sol and Luna, 22 September 2026.
Sources
OpenAI, GPT-6 Astra, a new generation of intelligence, 3 September 2026 (the announcement, the benchmark figures, the rollout wording and the image above). OpenAI, API pricing (the $10 and $50 standard rates, the $20 and $75 long context column, the Sol, Terra and Luna rows, and the 21 November promotional note). OpenAI, the gpt-6-astra model reference (the model id, the 1,050,000 token window, the 272K threshold, the knowledge cutoff and the reasoning effort levels). 9to5Google, OpenAI launches GPT-6 Astra, 3 September 2026 (independent confirmation of the staged rollout).
Frequently asked questions
How much does GPT-6 Astra cost?
Ten dollars per million input tokens and $50 per million output, with cached input at $1 and cache writes at $12.50, on OpenAI’s standard tier. Fast mode charges double. Requests carrying more than 272K input tokens are billed instead at $20 input, $2 cached, $25 cache writes and $75 output, and that applies to the whole request rather than to the excess.
Is GPT-6 Astra more expensive than GPT-5.6 Sol?
Yes, by a factor of two and a half on both input and output. Sol lists at $4 and $20, Astra at $10 and $50. Worth knowing before you quote the ratio at anyone: Sol’s $4 is promotional, and OpenAI’s pricing page only commits to it through 21 November 2026, so today’s gap is a list price measured against a discount.
Can I use GPT-6 Astra right now?
Probably not. OpenAI began rolling it out on 3 September 2026 to enterprises in its Trusted Access Program, with the API and the Plus, Pro, Business and Enterprise plans arriving over the following days. Microsoft Azure and AWS Bedrock are listed as launch surfaces too. Query the model endpoint with your own key, and a 404 tells you where you stand.
What is the GPT-6 Astra context window?
1,050,000 tokens in total, split as up to 922,000 input tokens and 128,000 output tokens, with a 30 April 2026 knowledge cutoff. Filling it isn’t cheap. Anything over 272K input tokens tips the entire request into the long context pricing column, so a 900K token prompt costs $18 on the input side alone.
Is GPT-6 Astra actually cheaper per task despite the higher rate?
That’s OpenAI’s claim, and it published estimated cost per task figures for Terminal-Bench 4.0, Terminal-Bench Science 0.1 and BenchCAD showing Astra below both Sol and Claude Fable 5.1. The catch is that all of it is OpenAI running its own evaluations and estimating its own costs. Nothing independent existed on launch day. Replay your own traffic before you rewrite a budget around it.


