
• Latest
  • Trending
  • All
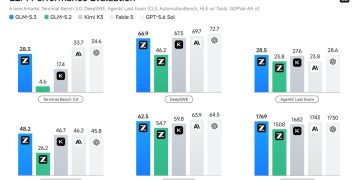
Z.ai official benchmark chart for GLM-5.3, six grouped bar charts comparing GLM-5.3, GLM-5.2, Kimi K3, Fable 5 and GPT-5.6 Sol on Terminal Bench 3.0, DeepSWE, Agents Last Exam, AutomationBench, HLE with Tools and GDPval-AA v2.

GLM-5.3: open weights in two weeks, breaking API change now

14 August 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
Answer card stating that Jev 1.13 from TypeSafe AI is a decision model in early access since 15 September 2026 that returns typed probabilities instead of text, priced at 42 dollars per billion input tokens with output tokens free, answering in 70 to 500 milliseconds, with a 64K token request budget, text input only, and a documented list of things it does badly, including counting and dates.

Jev 1.13 bills $42 a billion tokens, and it can’t count

19 September 2026
Answer card stating that Qwen3.8-Omni-Flash launched on 17 September 2026 as an API only model on Alibaba Cloud Model Studio, taking text, images, audio and video in a 1M token context and returning text only, priced at 0.15 dollars per million input tokens for every modality and 0.47 dollars per million output tokens in the international regions, with no open weights published and the Qwen-Live Harness GitHub repository returning 404.

Qwen3.8-Omni-Flash bills audio at $0.15 and ships no weights

18 September 2026
Answer card stating that on 15 September 2026 AWS said it is unable to restore access to resources and data hosted exclusively in the Middle East Bahrain region me-south-1 and in the mec1-az2 zone of the UAE region, because the damage spanned multiple Availability Zones and exceeded what multi-AZ services are designed to withstand.

AWS can’t restore me-south-1, six months after the drone strikes

17 September 2026
Answer card stating that Google released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking on 15 September 2026 at 3 dollars per million audio input tokens and 12 dollars out, that the thinking model requires asynchronous tools, and that Artificial Analysis scores it 82.6 on its Speech to Speech Quality Index.

Gemini 3.8 Live Extended Thinking rejects any tool that blocks

16 September 2026
Answer card summarising the Atria Dawn Preview release: 744B GLM-5.2 base, MIT licence, 1.5 TB BF16 and 756 GB FP8 checkpoints, 256K context, top on five of sixteen benchmark rows and trailing on SWE-bench Pro.

Atria Dawn Preview is 744B under MIT, and the BF16 weighs 1.5 TB

15 September 2026
Answer card stating that OpenAI released the Agents API in public beta on 10 September 2026 with no separate fee, billed through model tokens, tool calls and hosted sandbox time, with a choice of OpenAI hosted, self hosted or partner sandboxes, US only data residency and no Zero Data Retention support.

OpenAI’s Agents API has no fee, no ZDR and a one hour sandbox clock

14 September 2026
Answer card: Sakana Fugu Max at $2 and $6 per million tokens, Fugu Ultra v2 unchanged at $5 and $30, and Sakana saying Ultra v2 scores without Fable 5 or GPT-6 Astra in its pool.

Fugu Max costs $2 and $6 while Fugu Ultra v2 runs without Fable 5

13 September 2026
Answer card stating that DeepSeek released DeepSeek-V4.1-Flash on 10 September 2026 as a 552 billion parameter mixture of experts model with a new causal encoder decoder architecture that activates 8 billion parameters on input and 16 billion on output, with native vision, a one million token context and MIT licensed weights, that the API model name is now deepseek-flash at 0.15 dollars per million input tokens and 0.60 dollars per million output tokens off peak, and that DeepSeek announced V4 Pro would be routed to V4.1-Flash from 14 September and reversed that on 11 September.

DeepSeek V4.1-Flash arrived, and the V4 Pro retirement lasted a day

12 September 2026
Answer card stating that Cognition released SWE-2 on 10 September 2026, a coding model post-trained from Kimi K3, scoring 50.0 percent on FrontierCode 1.1 Main against 50.9 percent for Claude Fable 5.1 and 27.3 percent on Terminal-Bench 4 against 55.8 percent, available only inside Devin.

SWE-2 trails Fable 5.1 by one point, and by 28 on Terminal-Bench 4

11 September 2026
Answer card for Meta Muse, free to 100 million tokens a week then $20 a month, launched 8 September 2026 for United States adults only, running in a dedicated per user virtual machine.

Does Meta Muse do enough to earn your inbox and a card on file?

9 September 2026
Answer card stating that the public download pages for the VMware Virtual Disk Development Kit on developer.broadcom.com began returning 404 errors on 25 August 2026 with no announcement or deprecation notice, that Broadcom support tells customers the kit is no longer available for use or download, and that release lines 7.0.3.1, 8.x and 9.x are all affected.

Broadcom pulled VDDK 8.0 and 9.0, and the 404 is the only notice

8 September 2026
  • About
  • Contact
  • Privacy
  • Legal
Monday, September 21, 2026
  • Login
Packet Nebula
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About
No Result
View All Result
Packet Nebula
No Result
View All Result
Home Dev

GLM-5.3: open weights in two weeks, breaking API change now

by stephane
14 August 2026
in Dev
0
Z.ai official benchmark chart for GLM-5.3, six grouped bar charts comparing GLM-5.3, GLM-5.2, Kimi K3, Fable 5 and GPT-5.6 Sol on Terminal Bench 3.0, DeepSWE, Agents Last Exam, AutomationBench, HLE with Tools and GDPval-AA v2.
496
SHARES
1.4k
VIEWS
Share on FacebookShare on Twitter

Z.ai put a Hugging Face button on its own GLM-5.3 announcement page, and the button says Coming Soon. That is the launch in one image: the model went live on 14 August through the API and the Coding Plan, billed as the most capable open weights model for coding, while the weights themselves sit behind a two week safety review. There is a second catch that matters more if you already run GLM-5.2. Thinking can no longer be switched off. Send thinking.type disabled to glm-5.3 and the request fails, so pointing an existing integration at the new model ID is not the one line change it looks like. Same base model as 5.2, incidentally. Every gain here comes from scaled post-training, and on Terminal Bench 3.0 that took the score from 4.6 to 28.3.

The short answer

GLM-5.3 went live on 14 August on the Z.ai API and the Coding Plan. It reuses the GLM-5.2 base model and gets everything from post-training, which moved the coding and agent scores a long way. Two things to handle before you touch it: the weights are not out yet, and non-thinking calls now fail outright.
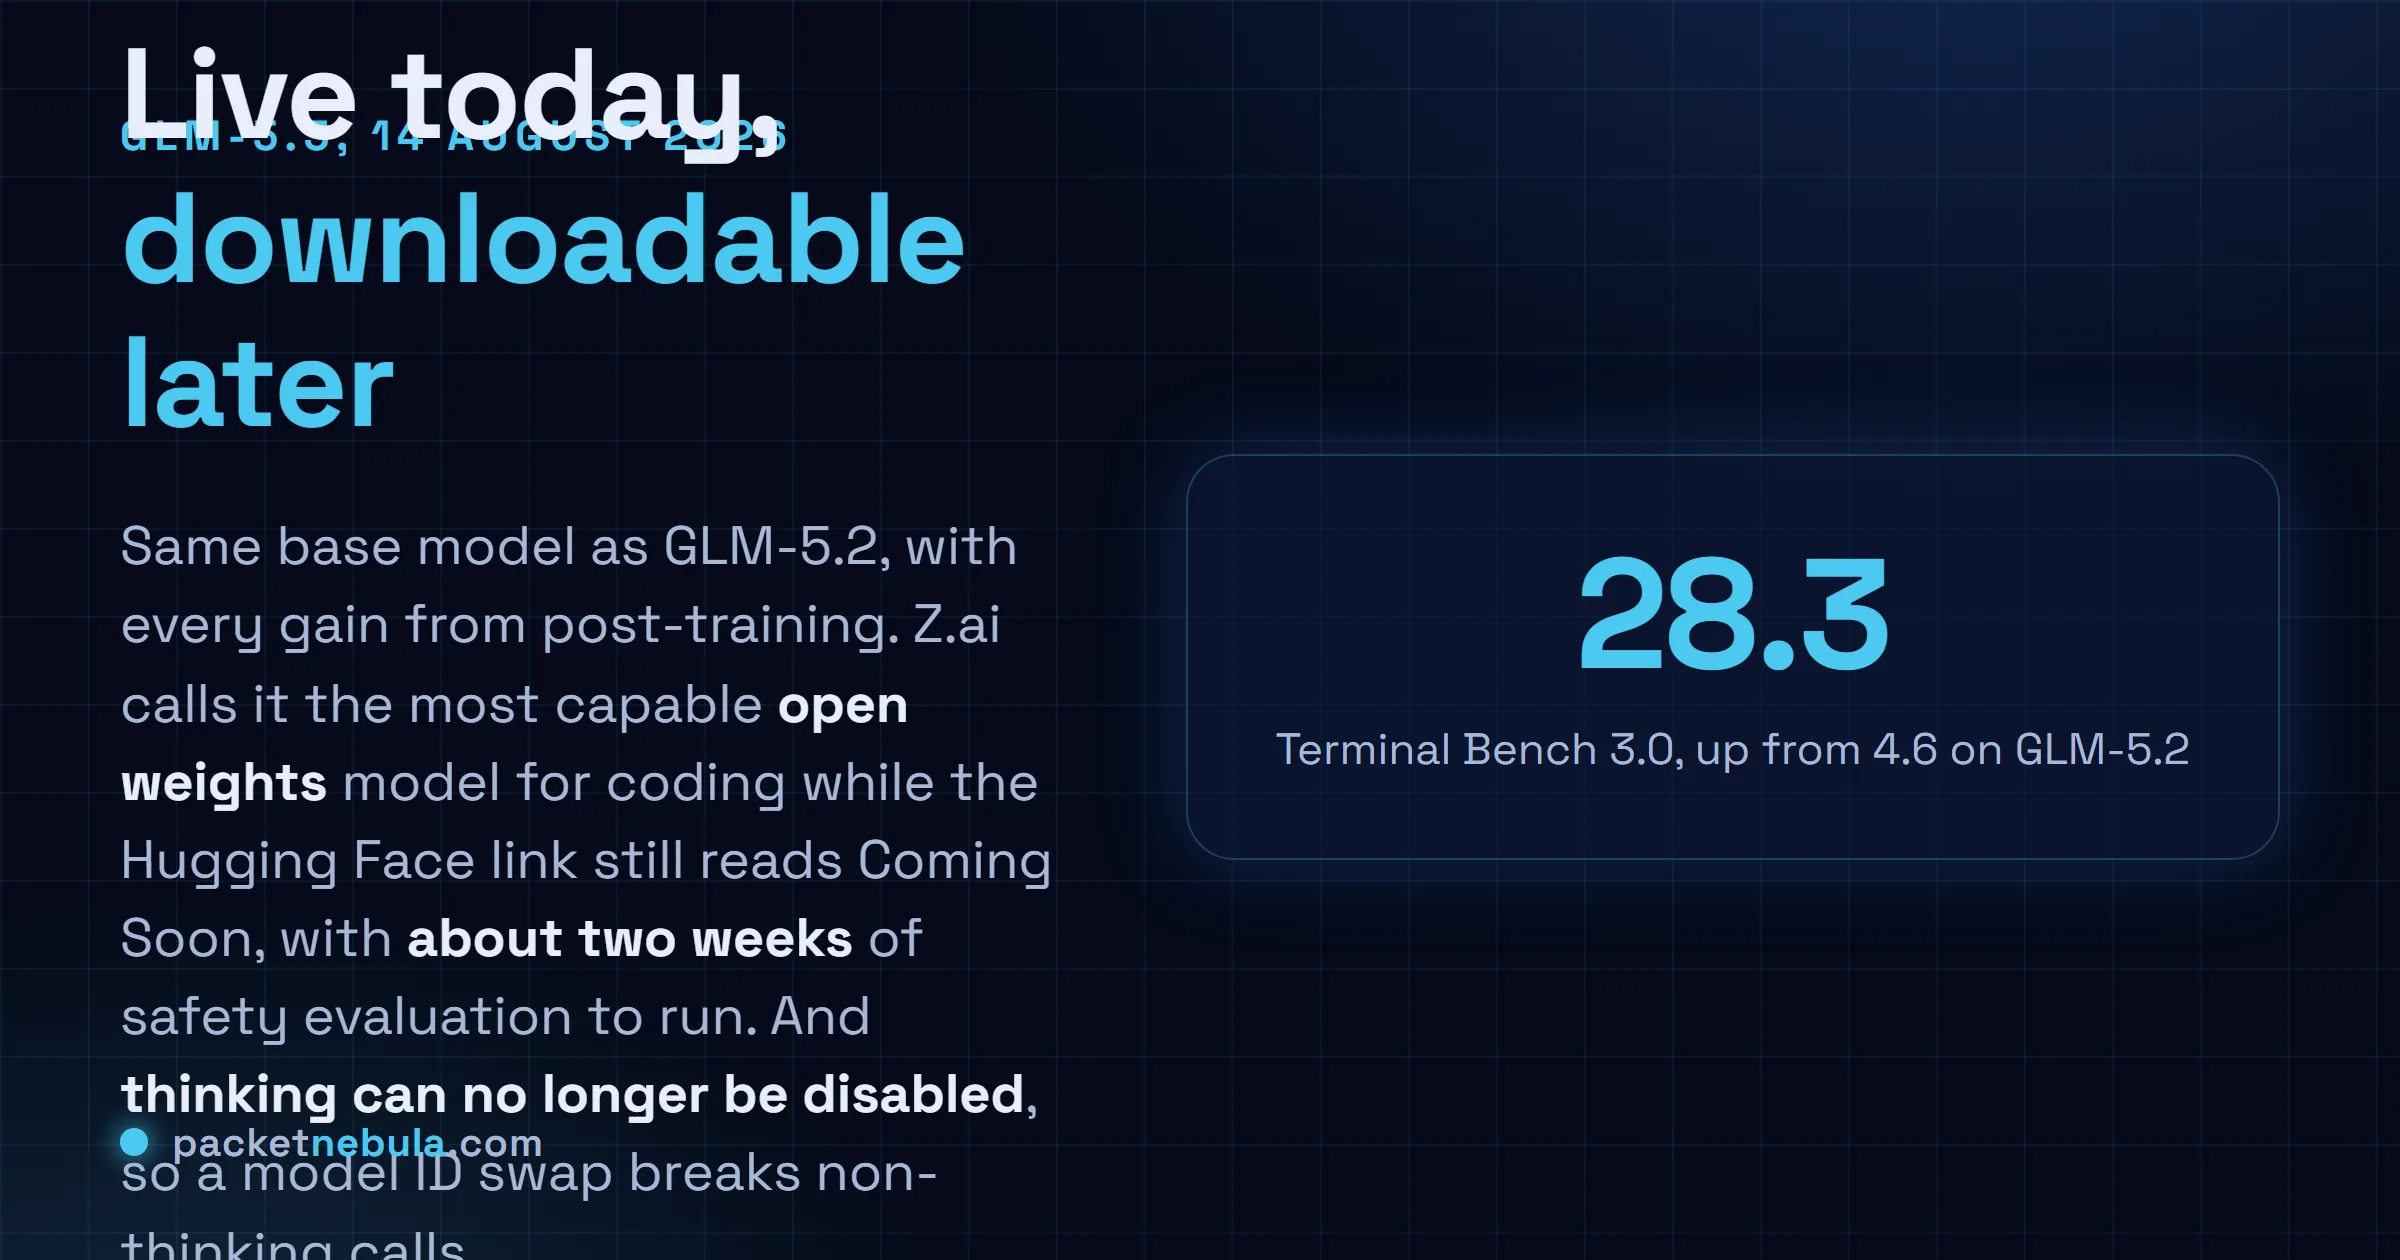
28.3Terminal Bench 3.0, was 4.6
~2 weeksuntil the weights are public
thinking offno longer supported
Answer card: Z.ai released GLM-5.3 on 14 August 2026 on the same base model as GLM-5.2, with the open weights held back about two weeks pending safety evaluation, and with thinking.type disabled removed from the API so that non-thinking requests fail.
Live today, downloadable later, and not a drop in replacement.

What Z.ai shipped

GLM-5.3 is a post-training release. Not a new pretrain, not a new size. Z.ai opens its own write up by saying scaling post-training is all it did, on the same stack GLM-5.2 introduced, with more environments and more compute thrown at them over the past month.

That framing is unusually honest and it sets the expectation correctly. A month of reinforcement learning on harder environments is exactly the kind of work that lifts long horizon agent scores and leaves single turn quality roughly where it was.
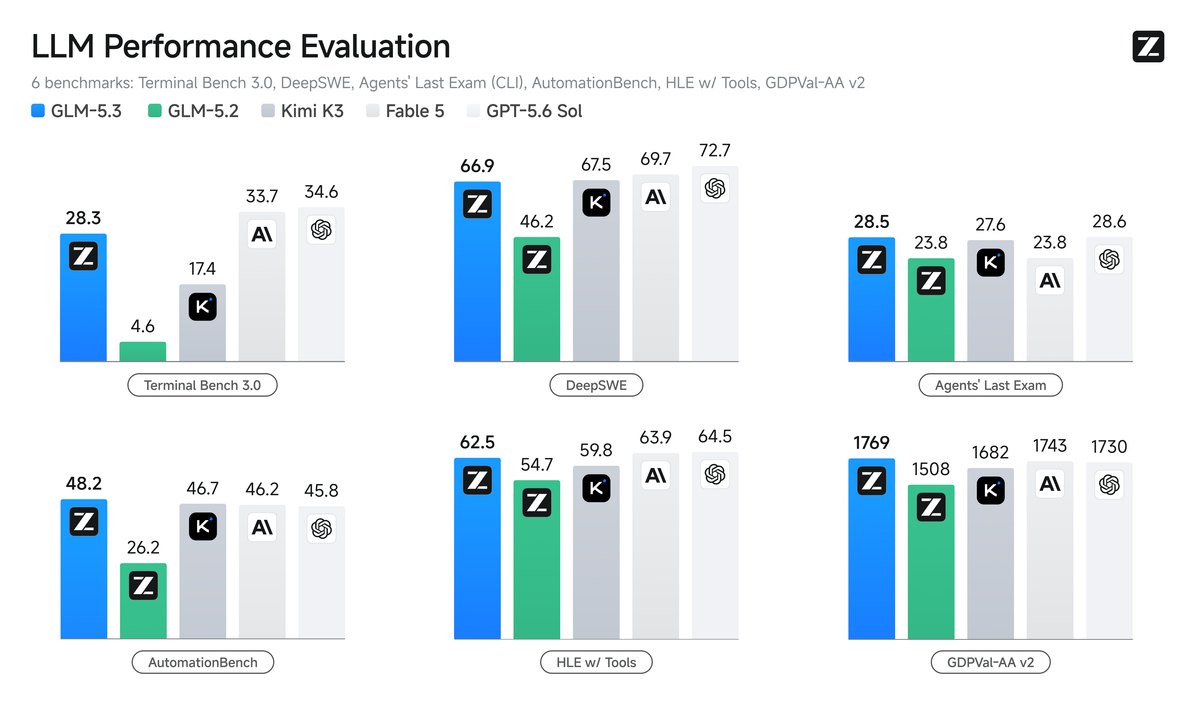
Z.ai's official benchmark chart for GLM-5.3: six grouped bar charts covering Terminal Bench 3.0, DeepSWE, Agents Last Exam, AutomationBench, HLE with Tools and GDPval-AA v2, comparing GLM-5.3 against GLM-5.2, Kimi K3, Fable 5 and GPT-5.6 Sol. Image: Z.ai

It is available now through the Z.ai API, in ZCode, and in the GLM Coding Plan, where Z.ai says it has already rolled out to every existing subscriber. No per token API rate appeared in the announcement, so if you bill by the token rather than by subscription you are waiting on the pricing page.

The migration note nobody put in the headline

Here is the part that will cost somebody an afternoon.

GLM-5.3 supports three thinking effort levels, low, high and max, with max as the default. And thinking.type: disabled is gone. Z.ai’s own wording is that disabling thinking is no longer supported, and that a request carrying the old parameter will fail. The documented migration is to set thinking to enabled and reasoning_effort to low first, then change the model ID.
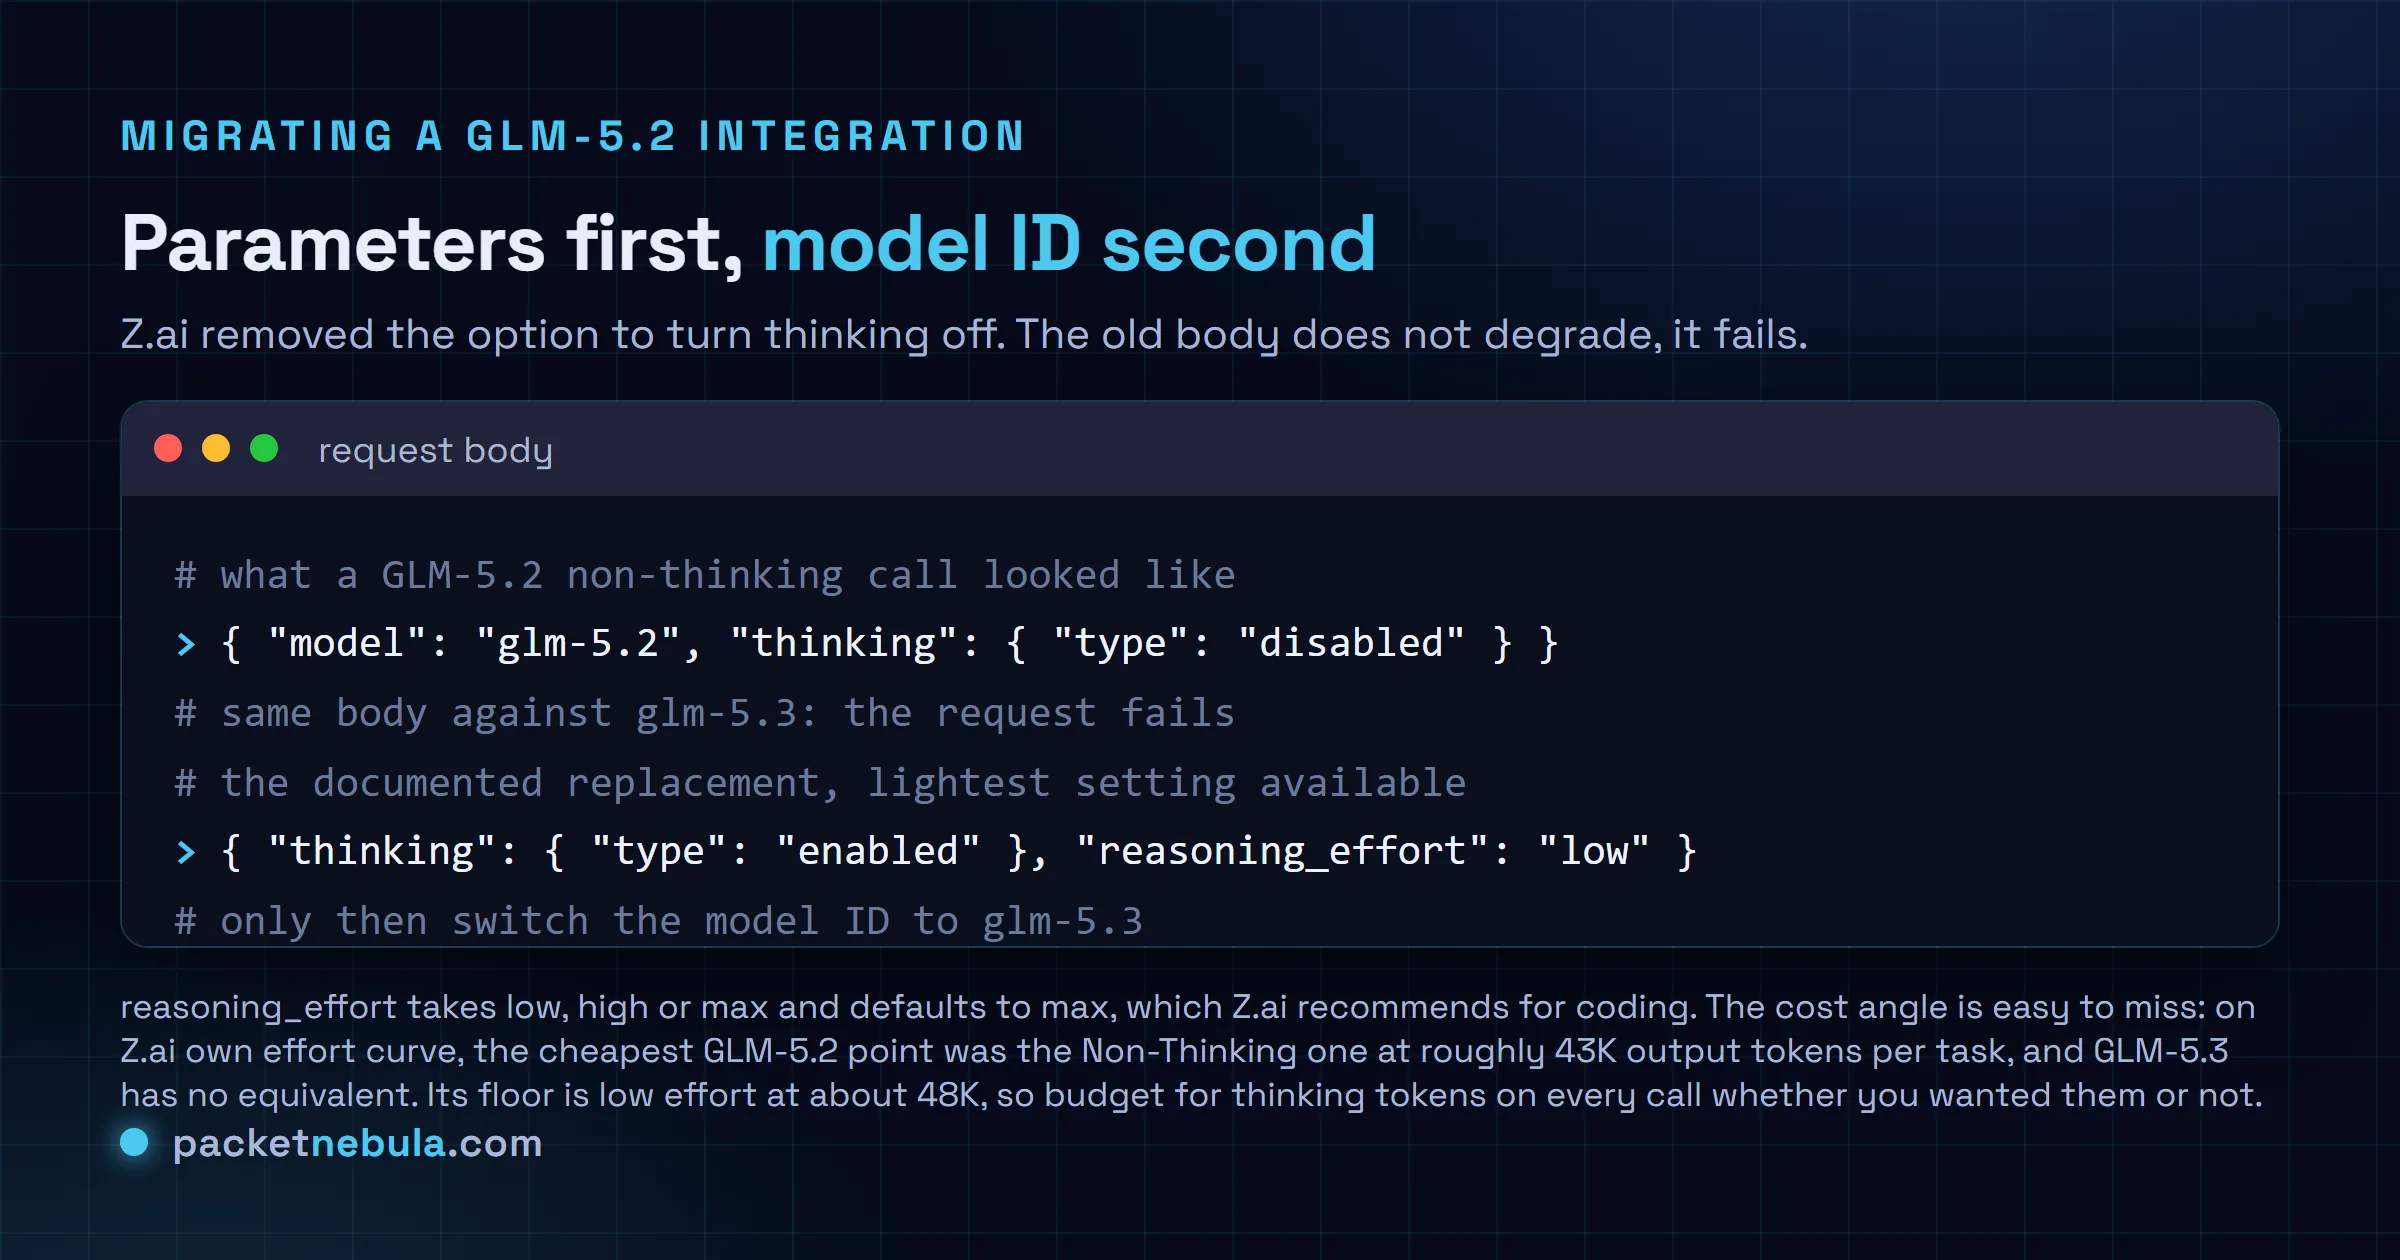
Terminal figure showing the GLM-5.2 request body with thinking type disabled failing against glm-5.3, and the corrected body setting thinking type enabled with reasoning_effort low, plus the ordering advice to change the parameters before the model ID.
Change the parameters, then the model ID. The other order gives you failed requests.

Look at what that does to the cheap end of the range. On Z.ai’s own effort curve, GLM-5.2’s leftmost point is labelled Non-Thinking, sitting at roughly 43K output tokens per task. GLM-5.3 has no such point. Its floor is Low, at about 48K. So the cheapest way to call this model family just stopped existing, and low effort thinking is what replaces it.

For a chat feature or a classification pass where you deliberately turned thinking off to keep latency down, that is a real change, not a parameter rename. I’d test the latency before assuming low effort behaves like the old non-thinking mode. Honestly I doubt it will.

The coding numbers, and what they are worth

The public benchmark jumps are large.
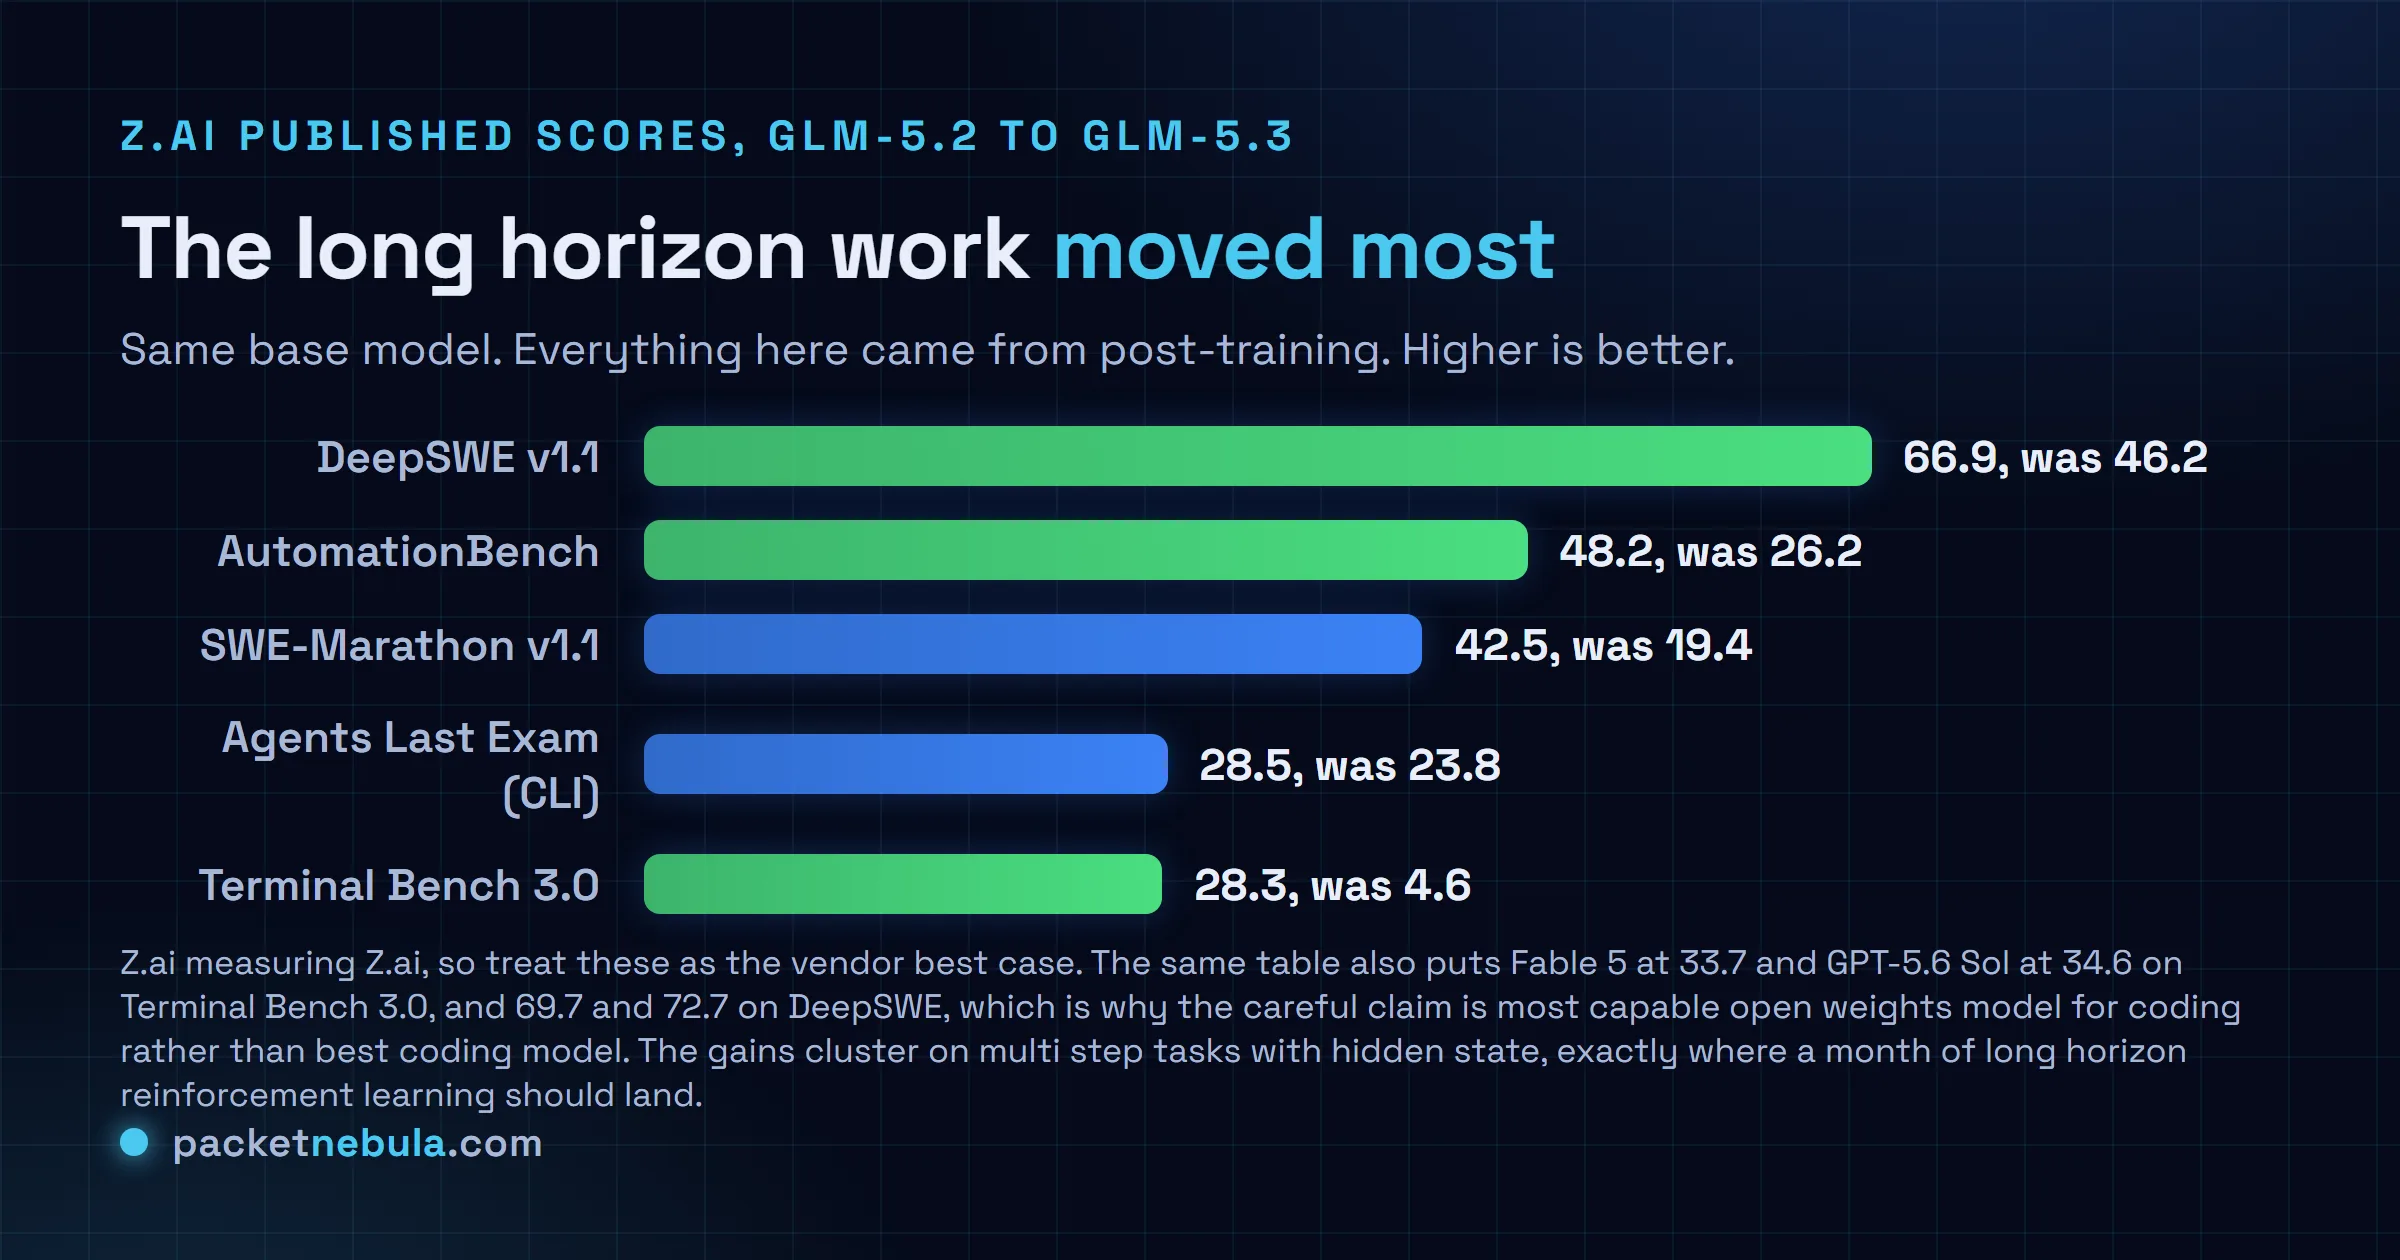
Bar chart of Z.ai published scores for GLM-5.3 against GLM-5.2: Terminal Bench 3.0 28.3 versus 4.6, SWE-Marathon v1.1 42.5 versus 19.4, AutomationBench 48.2 versus 26.2, DeepSWE v1.1 66.9 versus 46.2 and Agents Last Exam CLI 28.5 versus 23.8.
Every bar is Z.ai measuring Z.ai. The shape is still informative.

Terminal Bench 3.0 went from 4.6 to 28.3. SWE-Marathon v1.1 more than doubled, 19.4 to 42.5. AutomationBench went 26.2 to 48.2, DeepSWE v1.1 46.2 to 66.9, GDPval-AA v2 1508 to 1769. The gains cluster where you would expect a month of long horizon RL to land: multi step work with hidden state, where the model has to recover from its own mistakes instead of answering once.

Now the caveat, and it is the usual one. Same table, same page: Fable 5 scores 33.7 on Terminal Bench 3.0 and GPT-5.6 Sol 34.6, against GLM-5.3’s 28.3. DeepSWE reads 69.7 and 72.7 against 66.9. Kimi K3 is ahead on SWE-Marathon and Toolathlon. So the claim to read carefully is the specific one Z.ai makes, most capable open weights model for coding, not best coding model.
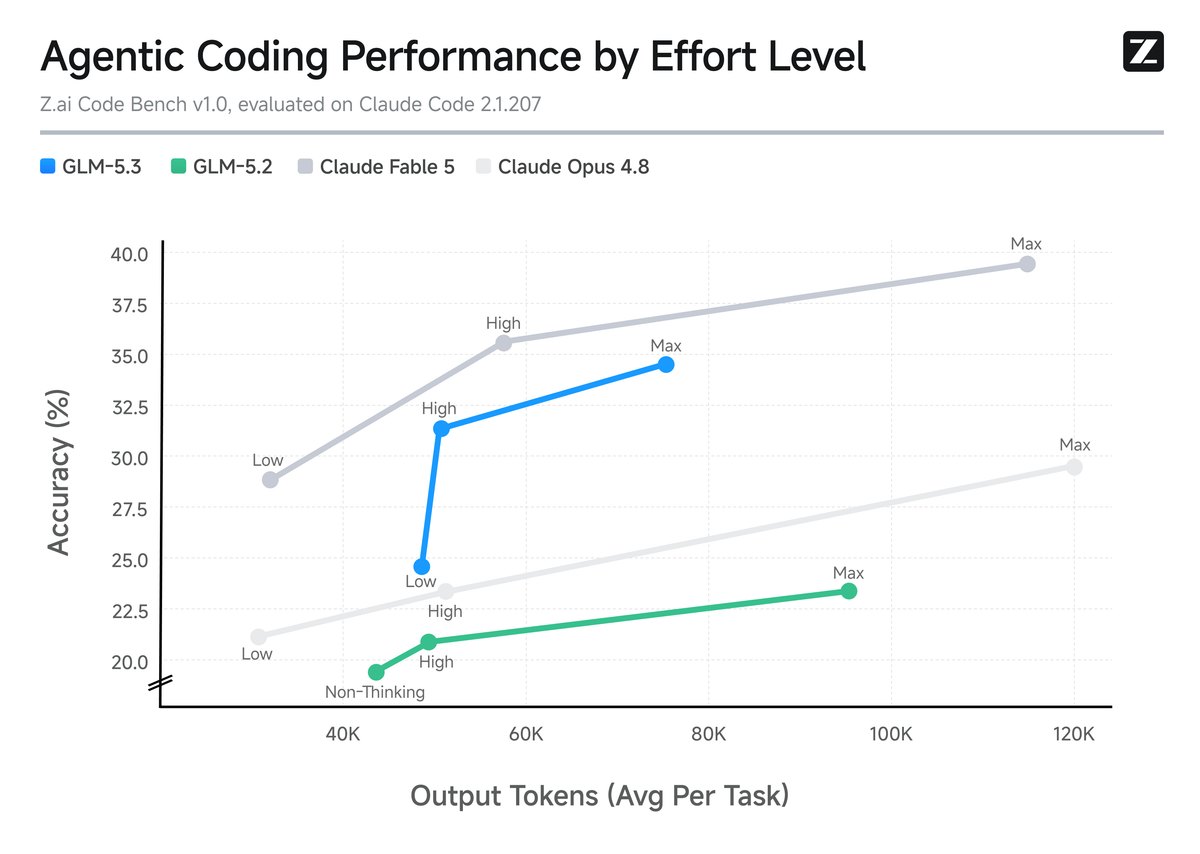
Z.ai's official agentic coding chart plotting accuracy against average output tokens per task on Z.ai Code Bench v1.0, with GLM-5.3, GLM-5.2, Claude Fable 5 and Claude Opus 4.8 curves across low, high and max effort levels. Image: Z.ai

The token efficiency chart is the one Z.ai clearly likes best, and it is the one to trust least, because Z.ai Code Bench is private. At high effort GLM-5.3 hits 31.4 percent at around 50K output tokens per task, above Opus 4.8’s 29.5 percent at 120K. At max it reaches 34.5 percent at roughly 75K, against 23.4 percent at 96K for GLM-5.2. Fable 5 still tops the chart at 39.5 percent.

Being right at half the output tokens is worth money, and nobody outside Z.ai can reproduce that measurement. Both things are true. We said much the same when GLM-5.2 landed against GPT-5.5 and Opus 4.8, and the pattern has not changed.

Open weights, in two weeks

Z.ai will publish the weights about two weeks after launch, once safety evaluation and hardening are done. The stated reason for the delay is that one capability grew faster than the lab expected as post-training scaled, specifically vulnerability discovery, where GLM-5.3 posts the top score on the CyberGym benchmark at 84.5 percent. Z.ai has paired that with a public disclosure ledger for the findings its security partners have filed.

Whatever you make of the reasoning, the practical consequence is simple. If the reason you run GLM is that you can host it yourself, GLM-5.3 does not exist for you today. GLM-5.2 does. And “about two weeks” is not a date, so if you have a launch pinned to self-hosted 5.3, pin it to something else. Kimi K3 published its weights on day one, which is the comparison the open weights crowd will make.

The Coding Plan clock

Worth ten seconds of attention if you subscribe. The plan moved to a points based quota, counted separately for input, cached input and output tokens, and calls made outside peak hours cost half the points.

Peak is 14:00 to 18:00 UTC+8, Monday to Friday. Everything else, weekends included, is half price. Run that through a European clock and peak becomes 08:00 to 12:00 in Paris during summer time. On the US east coast it is roughly 02:00 to 06:00, so an American team is off peak for its entire working day without doing anything. There is also a 1.5x quota boost on ZCode running to 31 August.

Would we move

If you are on GLM-5.2 through the Coding Plan, yes, it is already there and the agent scores went one direction. Budget an hour for the thinking parameter, not five minutes.

If you self host, wait. There is nothing to download and no date for when there will be.

And if you were choosing between this and a closed frontier model on raw coding quality, the table still says you would be trading a few points for the price. That was true in July and it is true now, just with a smaller gap.

Sources

Z.ai, GLM-5.3: Frontier Coding with Emergent Cyber Capabilities, 14 August 2026, for the benchmark table, the effort level charts, the API changes and the Coding Plan terms. Z.ai, Z.ai developer pack overview. Unite.AI, Z.ai launches GLM-5.3 with frontier coding, 14 August 2026. BigGo Finance, Zhipu AI releases GLM-5.3, open source weights coming in two weeks. Both charts reproduced above are Z.ai’s own, from the announcement page.

Frequently asked questions

When are the GLM-5.3 weights released?

Z.ai says about two weeks after the 14 August launch, once safety evaluation and hardening are complete, which points at the end of August 2026. No exact date has been published. The Hugging Face link on the announcement page reads Coming Soon, and the local serving section says only that the weights will be publicly available soon.

Can you disable thinking on GLM-5.3?

No. Z.ai's API notes state that thinking.type disabled is no longer supported on glm-5.3, and that a request sending it will fail. The replacement is reasoning_effort with three values, low, high and max, defaulting to max. Z.ai's migration instruction is to switch thinking.type to enabled and set reasoning_effort to low before you change the model ID.

Is GLM-5.3 a new base model?

No, it uses the same base model as GLM-5.2. Z.ai is explicit that every gain comes from post-training, specifically more reinforcement learning environments and more compute spent on them, running on the same IndexShare, SAO and slime stack that GLM-5.2 introduced.

How does GLM-5.3 compare to Claude Fable 5 and GPT-5.6 Sol on coding?

Still behind, on Z.ai's own published table. Terminal Bench 3.0 reads 28.3 for GLM-5.3 against 33.7 for Fable 5 and 34.6 for GPT-5.6 Sol. DeepSWE v1.1 reads 66.9 against 69.7 and 72.7. On Z.ai Code Bench, the vendor's private benchmark, GLM-5.3 reaches 31.4 percent at high effort while Fable 5 reaches 39.5 percent at max.

What changed in the GLM Coding Plan?

It moved to a points based quota, counted separately for input, cached input and output tokens. Calls outside peak hours cost half the standard points. Peak is 14:00 to 18:00 UTC+8, Monday to Friday, which is 08:00 to 12:00 in Paris during summer time and the small hours in North America.

Tags: aiapicodingllmnewsopen-weights
Share198Tweet124
stephane

stephane

  • Trending
  • Comments
  • Latest
Answer card: Proton Lumo 2.0 is private by policy, not by locality. Saved history is locked so even Proton cannot read it, but the prompt is decrypted on a Proton EU server to answer it, then forgotten.

Proton Lumo 2.0 review: how private is it, really?

3 September 2026
The Agentic Coding section of the official Hy4 preview benchmark appendix published by Tencent, a table comparing Hy3 and Hy4 preview against DeepSeek V4 Pro 0813, Qwen 3.8 Max, GLM 5.3, Kimi K3, GPT 5.6 Sol and Claude Opus 5 across SWE-bench Multilingual, SWE-bench Pro, DeepSWE, three SWE Atlas tasks, SWE-Marathon, Terminal-Bench 2.1, NL2Repo-Bench, CyberGym, ProgramBench, PostTrainBench and Harbor-Index.

Tencent’s 770B Hy4 tops one benchmark row in 46

3 September 2026
Answer card: Qwen 3.7 Max is API-only and cannot run locally yet; the open Qwen models (Qwen 3.6 27B, qwen3:8b to 32b) run offline via Ollama.

Qwen 3.7 local: what you can actually run offline

22 June 2026
Answer card: JWTs are not encrypted, anyone can read them; the signature proves who issued the token, not who may read it.

Are JWTs encrypted? No, and the difference will bite you

0
Answer card: a random 8 character password falls in under 2 hours offline, while 16 random characters hold for 1.4 trillion years at the same speed.

How long does it take to crack a password in 2026?

0
Answer card: three DNS records decide if your mail lands or bounces; SPF lists allowed senders, DKIM signs messages, DMARC sets the failure policy.

SPF, DKIM and DMARC explained: the records your email needs

0
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
Answer card stating that Jev 1.13 from TypeSafe AI is a decision model in early access since 15 September 2026 that returns typed probabilities instead of text, priced at 42 dollars per billion input tokens with output tokens free, answering in 70 to 500 milliseconds, with a 64K token request budget, text input only, and a documented list of things it does badly, including counting and dates.

Jev 1.13 bills $42 a billion tokens, and it can’t count

19 September 2026
Answer card stating that Qwen3.8-Omni-Flash launched on 17 September 2026 as an API only model on Alibaba Cloud Model Studio, taking text, images, audio and video in a 1M token context and returning text only, priced at 0.15 dollars per million input tokens for every modality and 0.47 dollars per million output tokens in the international regions, with no open weights published and the Qwen-Live Harness GitHub repository returning 404.

Qwen3.8-Omni-Flash bills audio at $0.15 and ships no weights

18 September 2026
  • About
  • Contact
  • Privacy
  • Legal

Copyright © 2026 Stephane Cardon.

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About

Copyright © 2026 Stephane Cardon.