
• Latest
  • Trending
  • All
Answer card: Grok 4.5 launched at $2 input and $6 output per million tokens, the cheapest serious coding model, trailing Fable 5 on hard benchmarks but far more token-efficient.

xAI Grok 4.5 is here: cheap, fast, coding-first

8 July 2026
The official xAI announcement card for Grok 4.7, white type on a dark grey and navy gradient.

Grok 4.7 keeps $2 and $6, and its gains over 4.6 are xhigh versus high

22 September 2026
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.

Qwen-Image-2.1 brings the weights back, but not the Apache licence

21 September 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
Answer card stating that Jev 1.13 from TypeSafe AI is a decision model in early access since 15 September 2026 that returns typed probabilities instead of text, priced at 42 dollars per billion input tokens with output tokens free, answering in 70 to 500 milliseconds, with a 64K token request budget, text input only, and a documented list of things it does badly, including counting and dates.

Jev 1.13 bills $42 a billion tokens, and it can’t count

19 September 2026
Answer card stating that Qwen3.8-Omni-Flash launched on 17 September 2026 as an API only model on Alibaba Cloud Model Studio, taking text, images, audio and video in a 1M token context and returning text only, priced at 0.15 dollars per million input tokens for every modality and 0.47 dollars per million output tokens in the international regions, with no open weights published and the Qwen-Live Harness GitHub repository returning 404.

Qwen3.8-Omni-Flash bills audio at $0.15 and ships no weights

18 September 2026
Answer card stating that on 15 September 2026 AWS said it is unable to restore access to resources and data hosted exclusively in the Middle East Bahrain region me-south-1 and in the mec1-az2 zone of the UAE region, because the damage spanned multiple Availability Zones and exceeded what multi-AZ services are designed to withstand.

AWS can’t restore me-south-1, six months after the drone strikes

17 September 2026
Answer card stating that Google released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking on 15 September 2026 at 3 dollars per million audio input tokens and 12 dollars out, that the thinking model requires asynchronous tools, and that Artificial Analysis scores it 82.6 on its Speech to Speech Quality Index.

Gemini 3.8 Live Extended Thinking rejects any tool that blocks

16 September 2026
Answer card summarising the Atria Dawn Preview release: 744B GLM-5.2 base, MIT licence, 1.5 TB BF16 and 756 GB FP8 checkpoints, 256K context, top on five of sixteen benchmark rows and trailing on SWE-bench Pro.

Atria Dawn Preview is 744B under MIT, and the BF16 weighs 1.5 TB

15 September 2026
Answer card stating that OpenAI released the Agents API in public beta on 10 September 2026 with no separate fee, billed through model tokens, tool calls and hosted sandbox time, with a choice of OpenAI hosted, self hosted or partner sandboxes, US only data residency and no Zero Data Retention support.

OpenAI’s Agents API has no fee, no ZDR and a one hour sandbox clock

14 September 2026
Answer card: Sakana Fugu Max at $2 and $6 per million tokens, Fugu Ultra v2 unchanged at $5 and $30, and Sakana saying Ultra v2 scores without Fable 5 or GPT-6 Astra in its pool.

Fugu Max costs $2 and $6 while Fugu Ultra v2 runs without Fable 5

13 September 2026
Answer card stating that DeepSeek released DeepSeek-V4.1-Flash on 10 September 2026 as a 552 billion parameter mixture of experts model with a new causal encoder decoder architecture that activates 8 billion parameters on input and 16 billion on output, with native vision, a one million token context and MIT licensed weights, that the API model name is now deepseek-flash at 0.15 dollars per million input tokens and 0.60 dollars per million output tokens off peak, and that DeepSeek announced V4 Pro would be routed to V4.1-Flash from 14 September and reversed that on 11 September.

DeepSeek V4.1-Flash arrived, and the V4 Pro retirement lasted a day

12 September 2026
Answer card stating that Cognition released SWE-2 on 10 September 2026, a coding model post-trained from Kimi K3, scoring 50.0 percent on FrontierCode 1.1 Main against 50.9 percent for Claude Fable 5.1 and 27.3 percent on Terminal-Bench 4 against 55.8 percent, available only inside Devin.

SWE-2 trails Fable 5.1 by one point, and by 28 on Terminal-Bench 4

11 September 2026
  • About
  • Contact
  • Privacy
  • Legal
Tuesday, September 22, 2026
  • Login
Packet Nebula
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About
No Result
View All Result
Packet Nebula
No Result
View All Result
Home Dev

xAI Grok 4.5 is here: cheap, fast, coding-first

by stephane
8 July 2026
in Dev
0
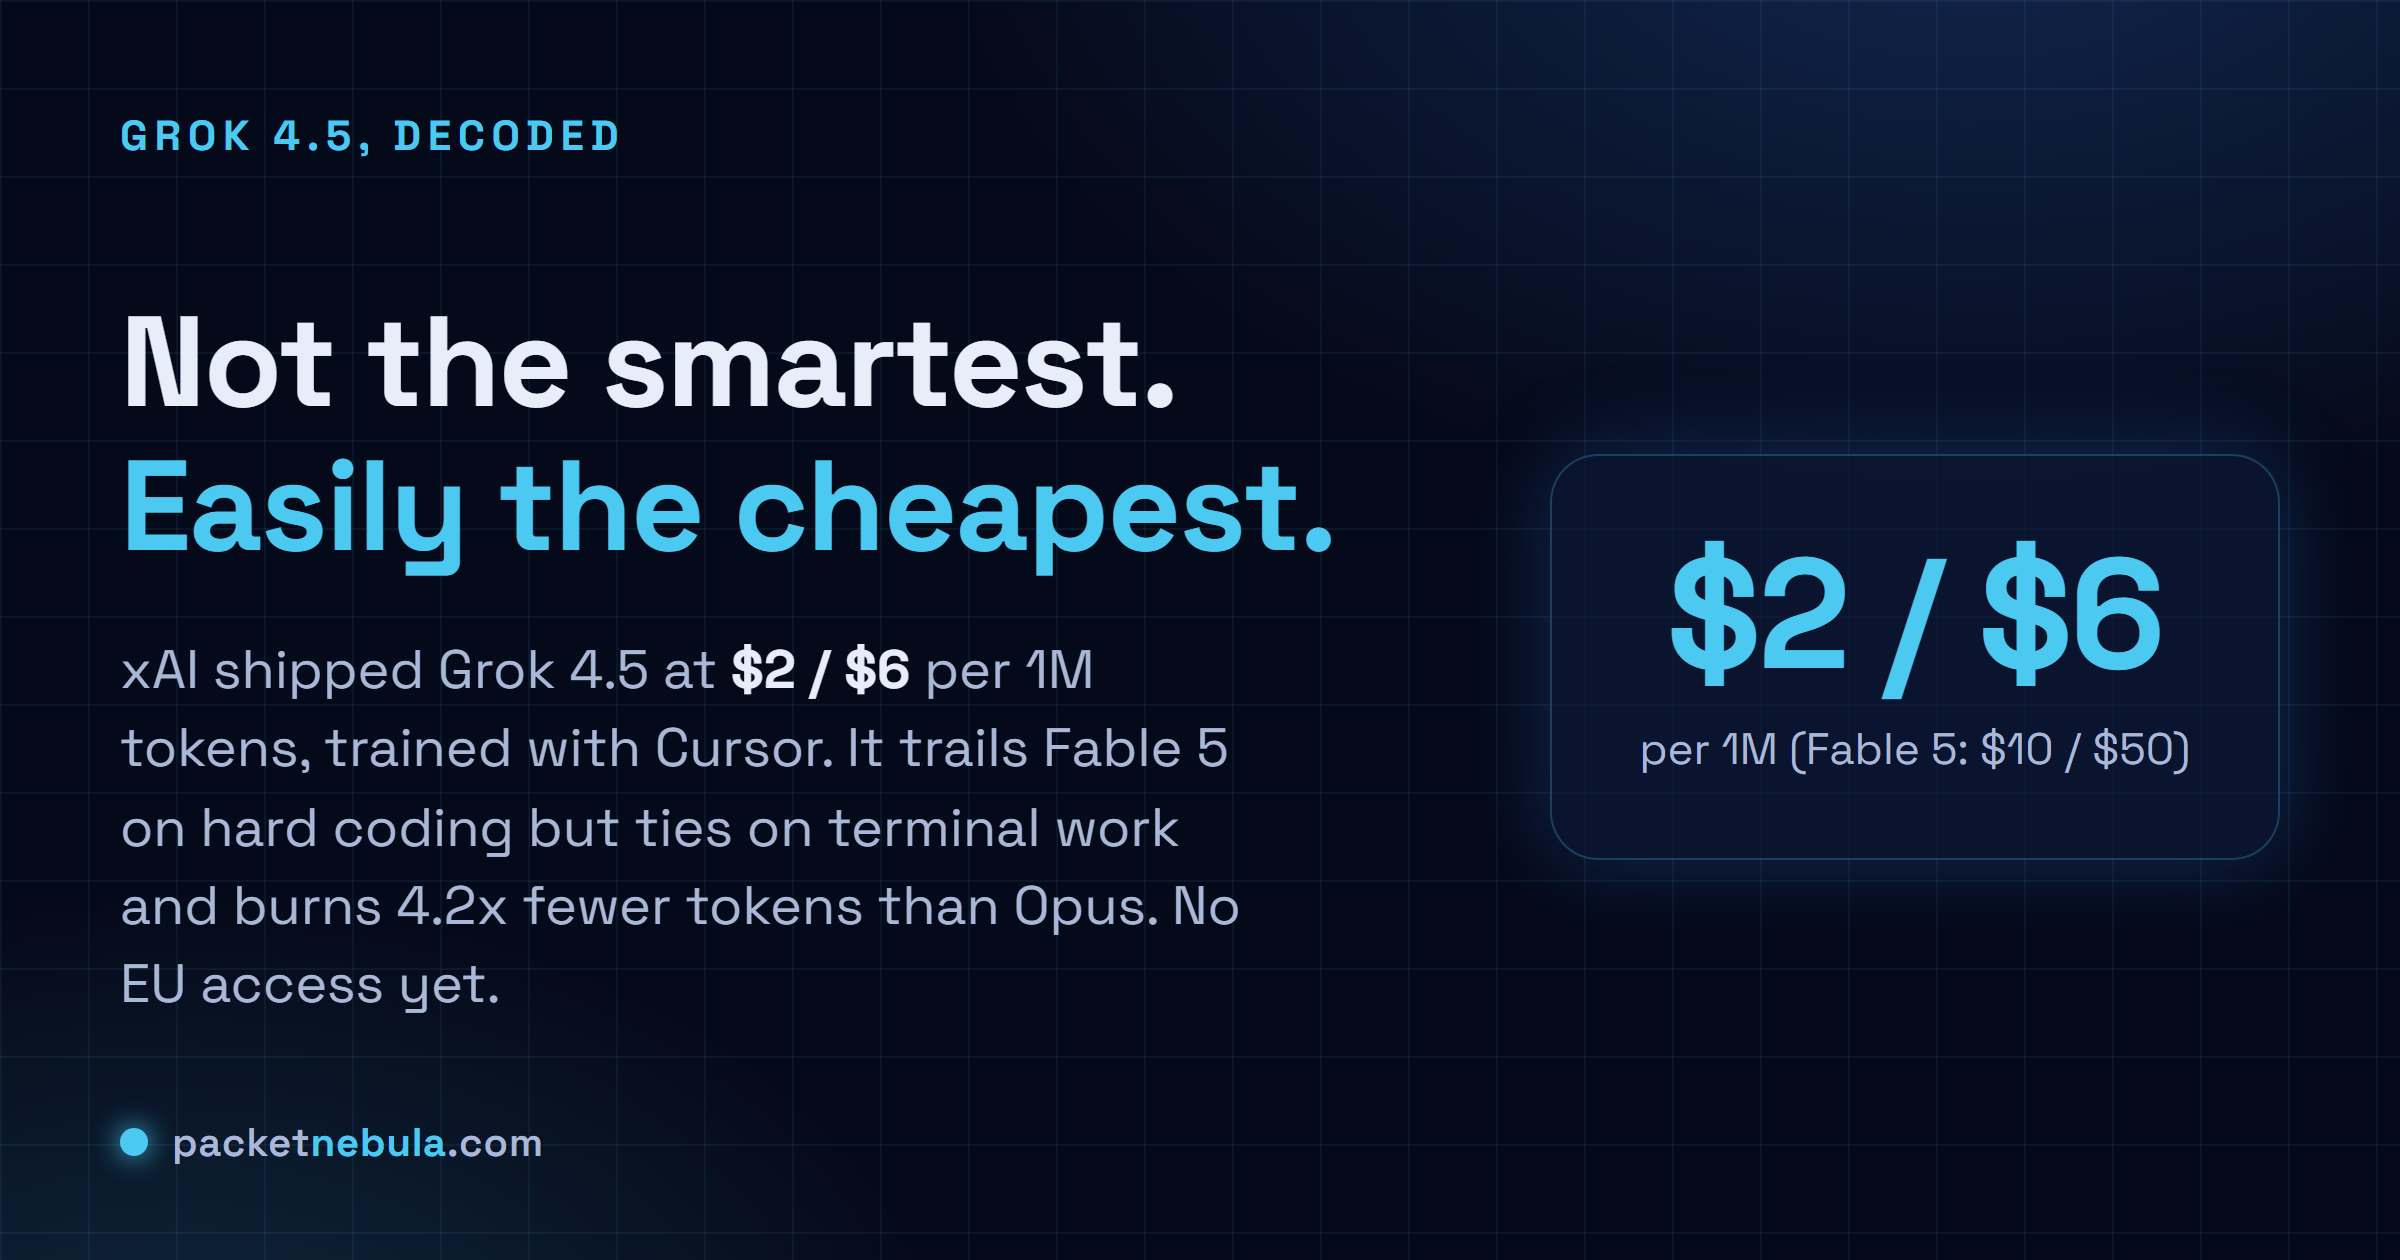
Answer card: Grok 4.5 launched at $2 input and $6 output per million tokens, the cheapest serious coding model, trailing Fable 5 on hard benchmarks but far more token-efficient.
494
SHARES
1.4k
VIEWS
Share on FacebookShare on Twitter

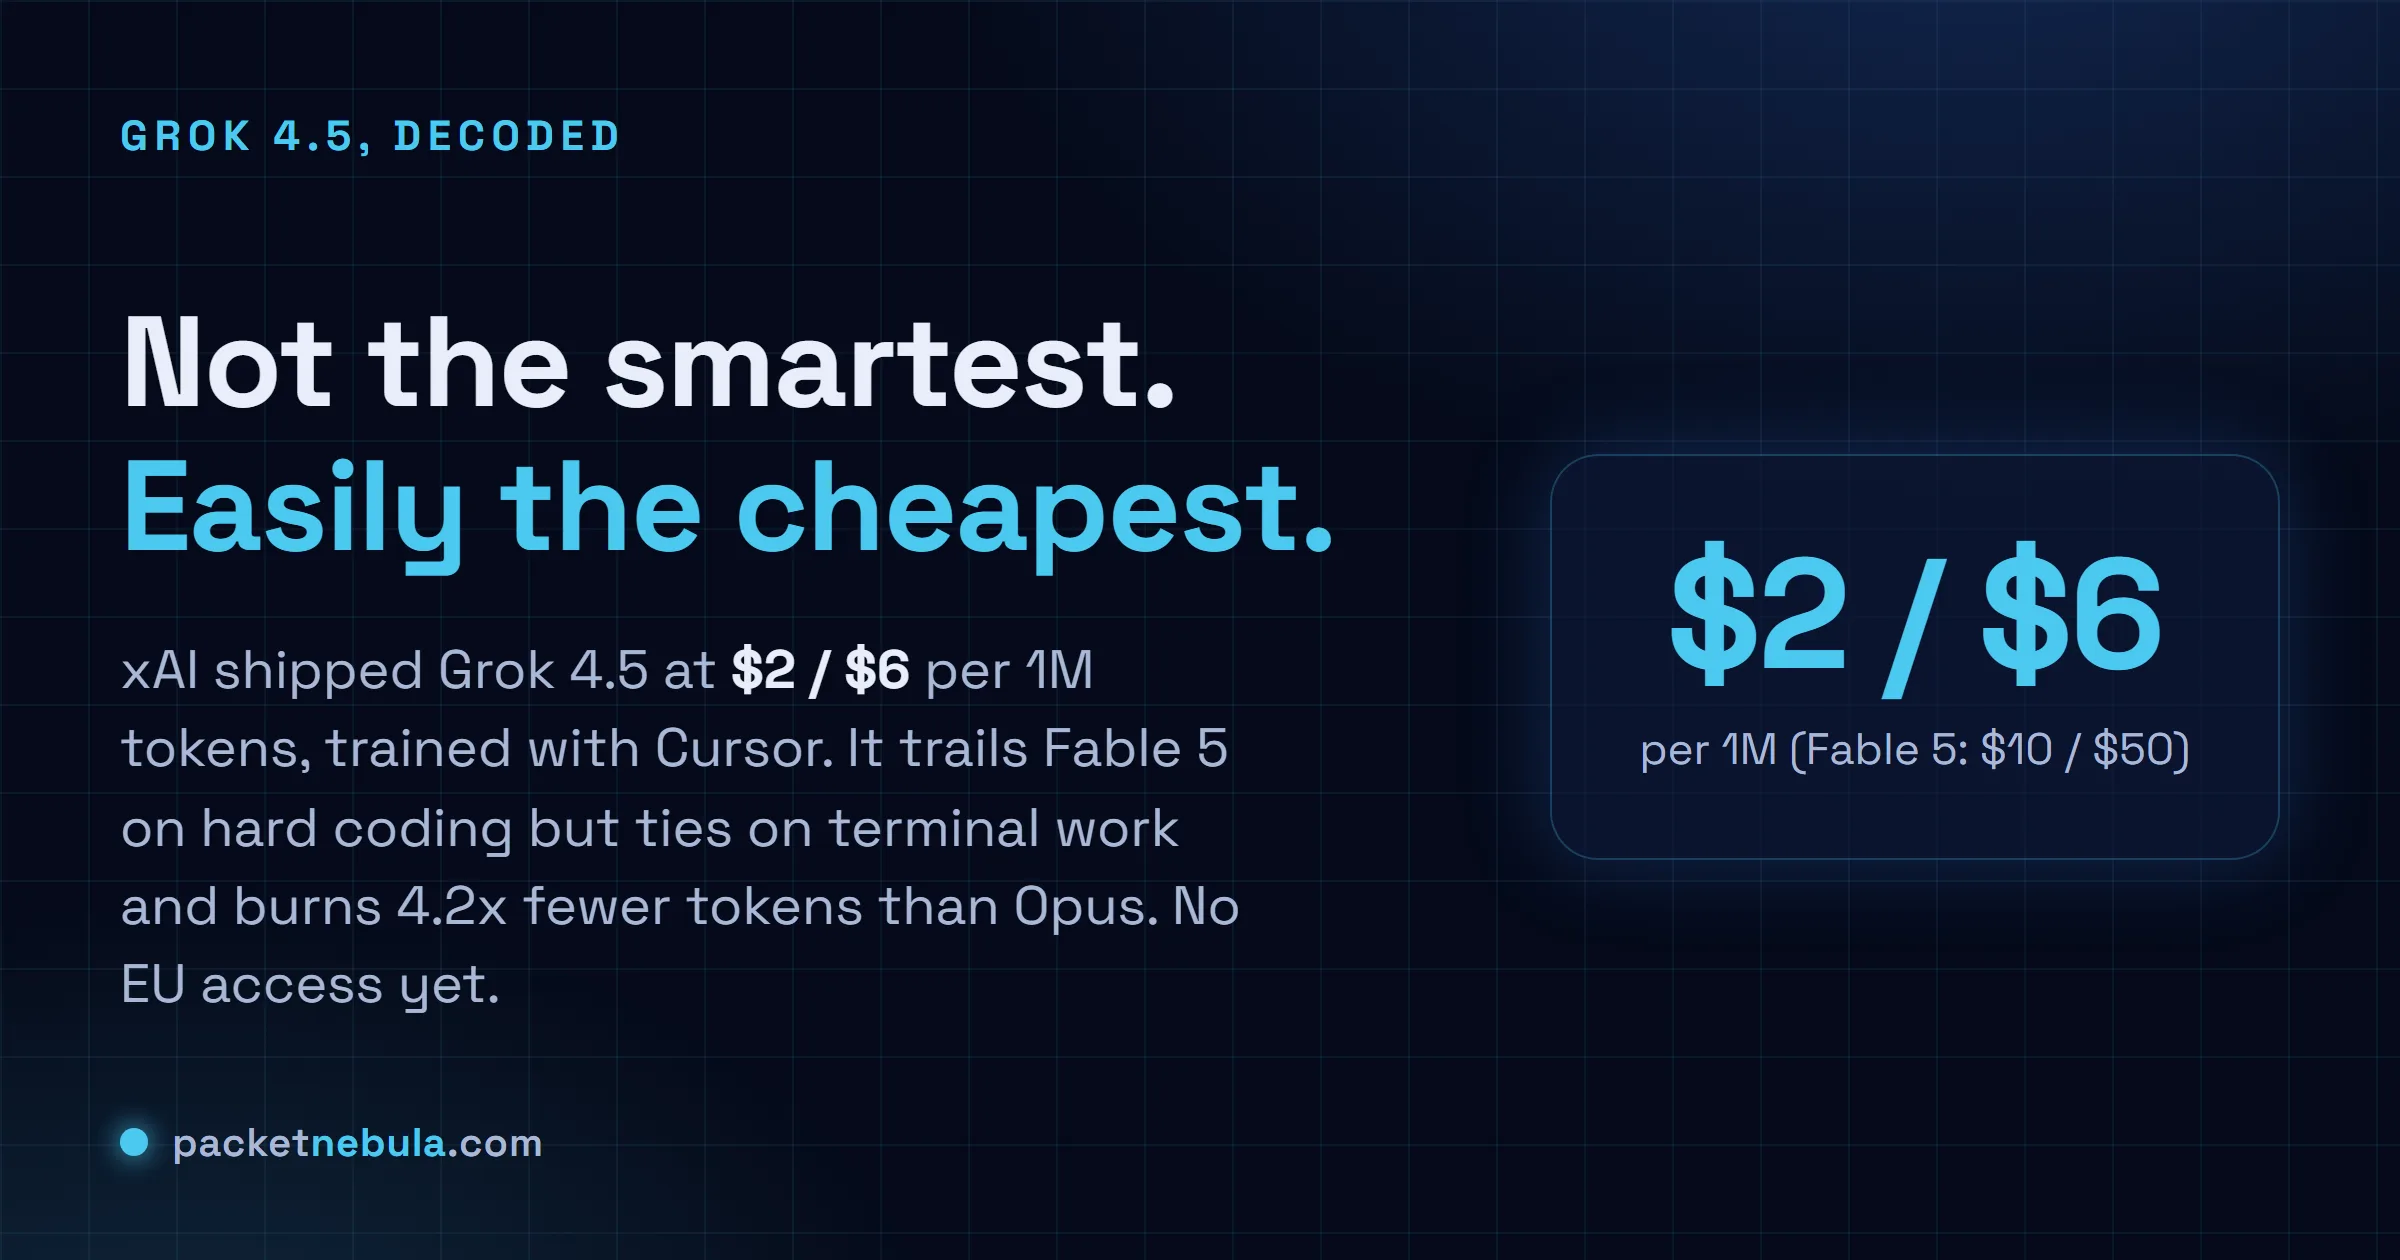
xAI shipped Grok 4.5 on July 8, and the number that matters is not a benchmark, it's the price: $2 in, $6 out per million tokens. That undercuts every frontier coding model, some of them badly. Grok 4.5 is not the smartest model on the market, it trails Anthropic's Fable 5 on the hard coding tests, but it is by a distance the cheapest one anyone takes seriously, and it burns far fewer tokens getting there. It was trained alongside Cursor and ships inside it, aimed at coding and agent work rather than chat. One catch for us in Europe: it isn't available in the EU yet. Here is what actually launched, and whether the price makes the gaps forgivable.

The short answer

Grok 4.5 landed July 8 as the cheapest serious coding model: $2 in, $6 out, about 80 tokens a second, trained alongside Cursor and shipping inside it. It trails Fable 5 on the hard coding benchmarks but is essentially tied on terminal work, and it burns a fraction of the tokens. The price is the pitch. The catch, for us: no EU access yet.
$2 / $6per 1M tokens
4.2xfewer tokens than Opus
not in EUat launch
Answer card: Grok 4.5 is the cheapest serious coding model at $2 and $6 per million tokens, trailing Fable 5 on hard benchmarks but far more token-efficient.
Not the smartest model. Comfortably the cheapest one that still counts.

The launch, in one line: price

xAI does not usually win on modesty, so it is a little funny that Grok 4.5’s headline is a spreadsheet. At $2 input and $6 output per million tokens, it undercuts the field: Opus 4.8 sits at $5/$25, GPT-5.5 at $5/$30, and Anthropic’s flagship Fable 5 at $10/$50. On output tokens, the part of any bill that hurts, Grok 4.5 is roughly four times cheaper than Opus and more than eight times cheaper than Fable 5. That is not a discount. That is a different shelf.

The model went public on July 8, live inside Cursor on all plans and through xAI’s own console. It was trained alongside Cursor, the AI coding editor, which tells you what it is for: writing and fixing code, driving agents, grinding through office work, not holding a conversation. It runs around 80 tokens a second, which feels quick when you are watching it edit a file.
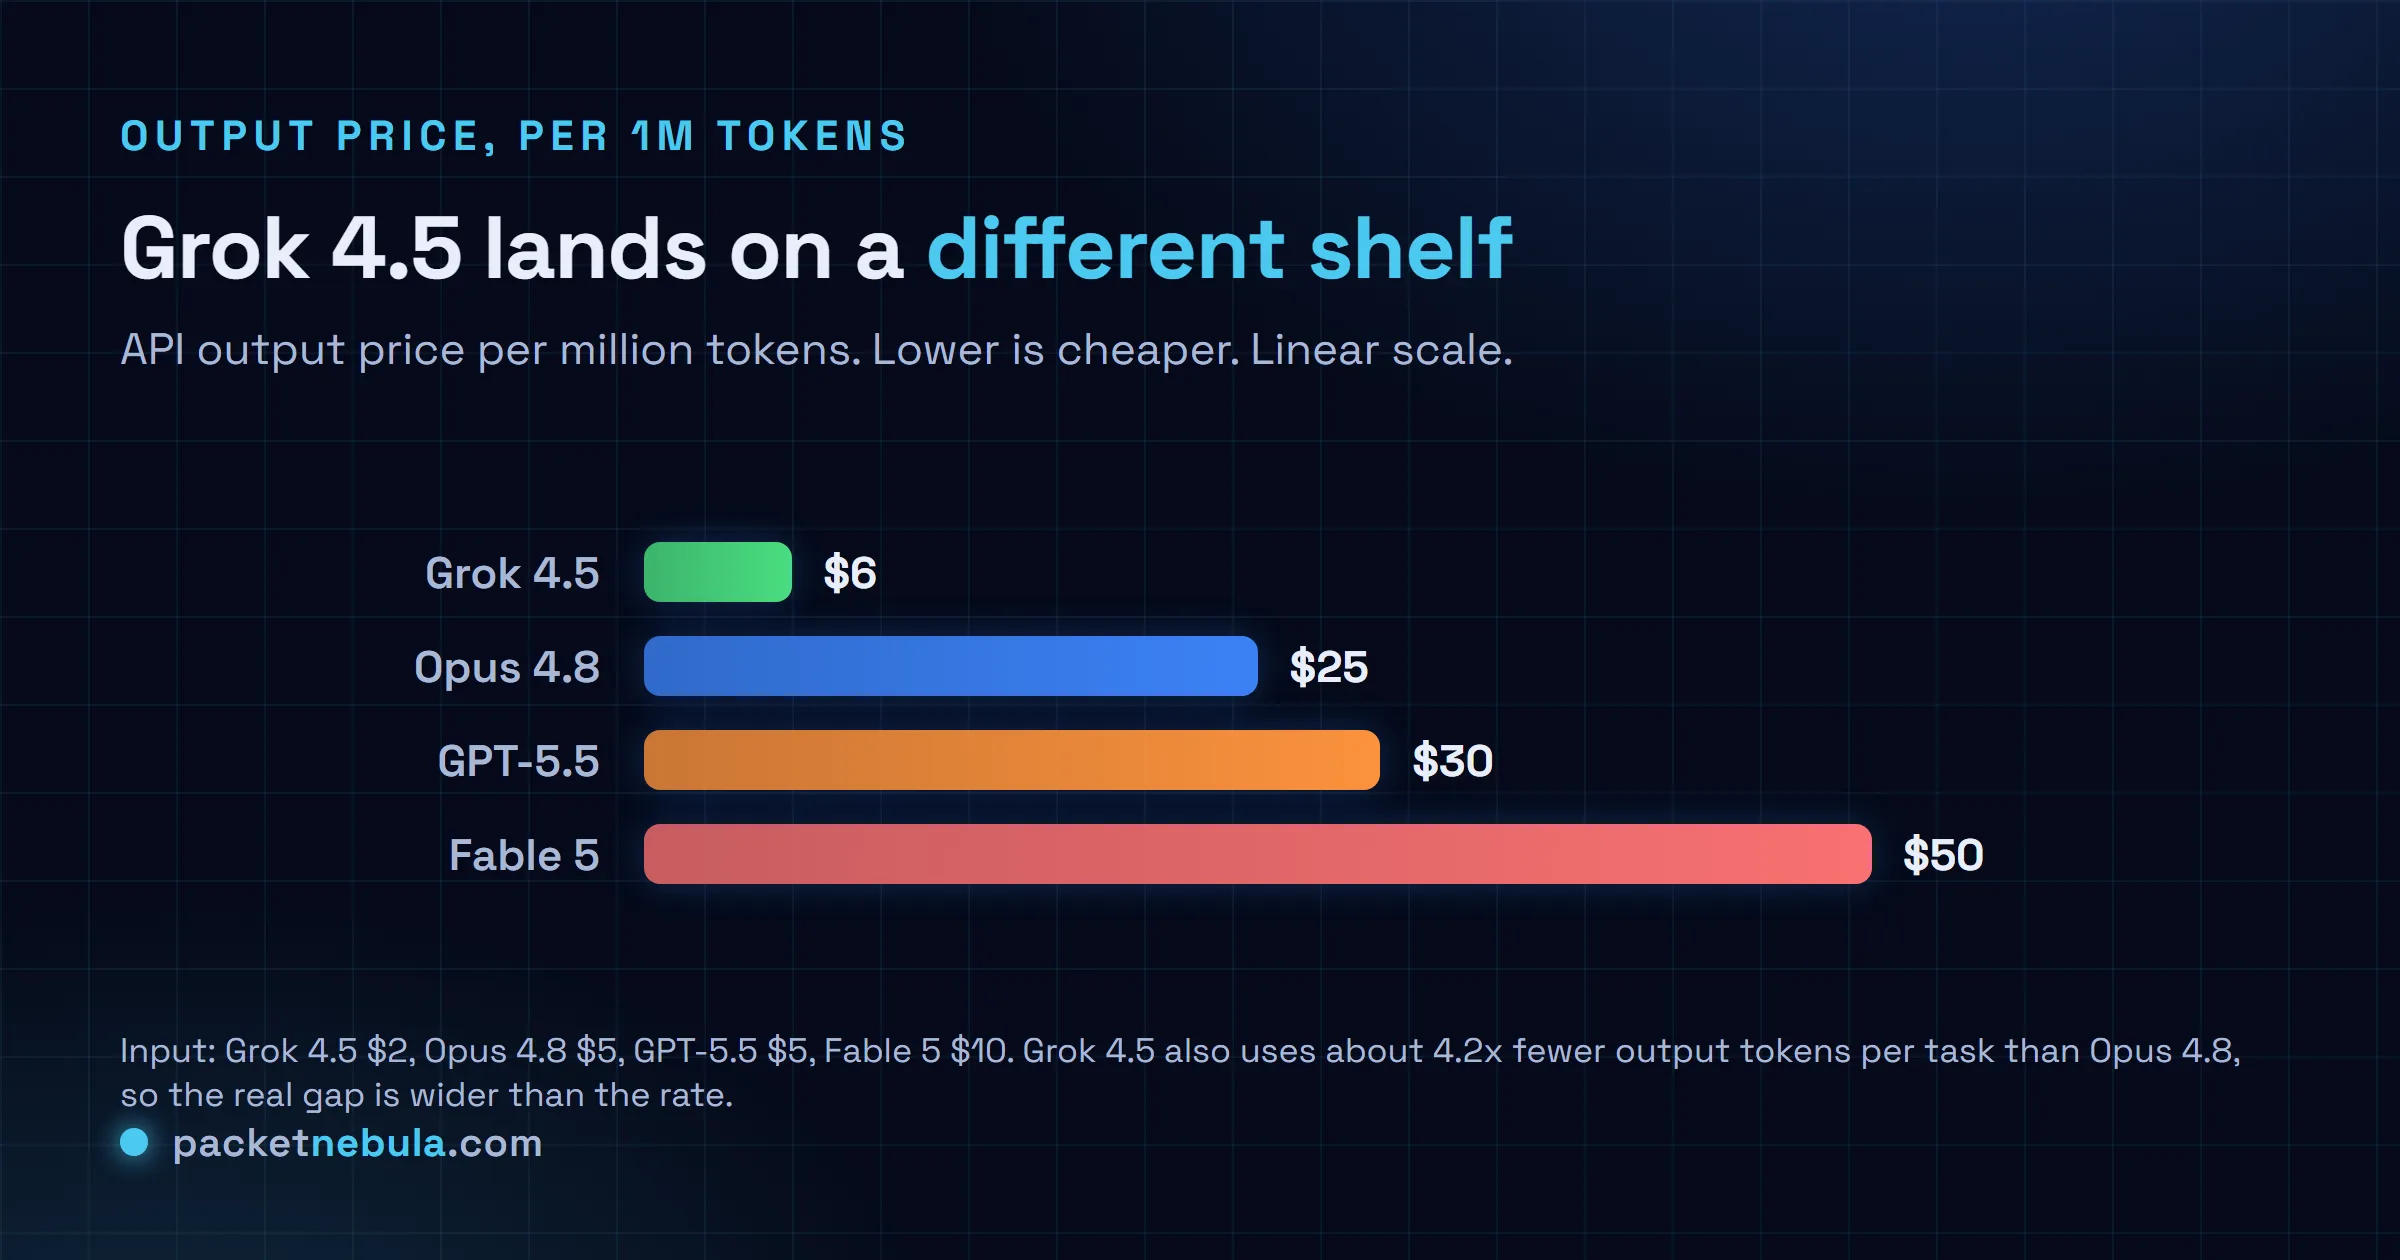
Bar chart of output price per million tokens: Grok 4.5 $6, Opus 4.8 $25, GPT-5.5 $30, Fable 5 $50.
Output price per million tokens. This one chart is most of the story.

Where Grok 4.5 actually holds up

Cheap would not matter if the model were bad, and it isn’t. On Terminal-Bench 2.1, the test for command-line and agent work, Grok 4.5 scores 83.3, a hair behind Fable 5’s 84.3 and ahead of Opus 4.8’s 78.9. For the everyday shape of agentic coding, the kind of loop that reads a file, runs a test and patches, it is right there with models that cost five to eight times more per token.

Then the efficiency. xAI reports Grok 4.5 resolves SWE-bench Pro tasks using about 15,954 output tokens on average, against roughly 67,020 for Opus 4.8 at maximum effort. That is a 4.2x gap, and it stacks on top of the cheaper rate. Cheaper tokens, and far fewer of them. For anyone running an agent at volume, where the token meter never stops, that combination is the whole argument, and it is a strong one.

Where it trails, and it does

Now the honest column. On the deep coding benchmarks, Grok 4.5 is not frontier. SWE-bench Pro, the multi-file repository test, has it at 64.7 against Fable 5’s 80.4 and Opus 4.8’s 69.2. On DeepSWE 1.1, which measures resolving real GitHub issues, it hits 53 against Fable 5’s 70. Those are not small gaps. On a genuinely hard, sprawling change, the more expensive models still land more of them, and the difference is the kind you find in production rather than in review.

So Grok 4.5 is not the model you reach for when a task is at the edge of what any model can do. It is the model you reach for when the task is normal, the volume is high, and the bill is real, which describes most of the coding most teams actually do.
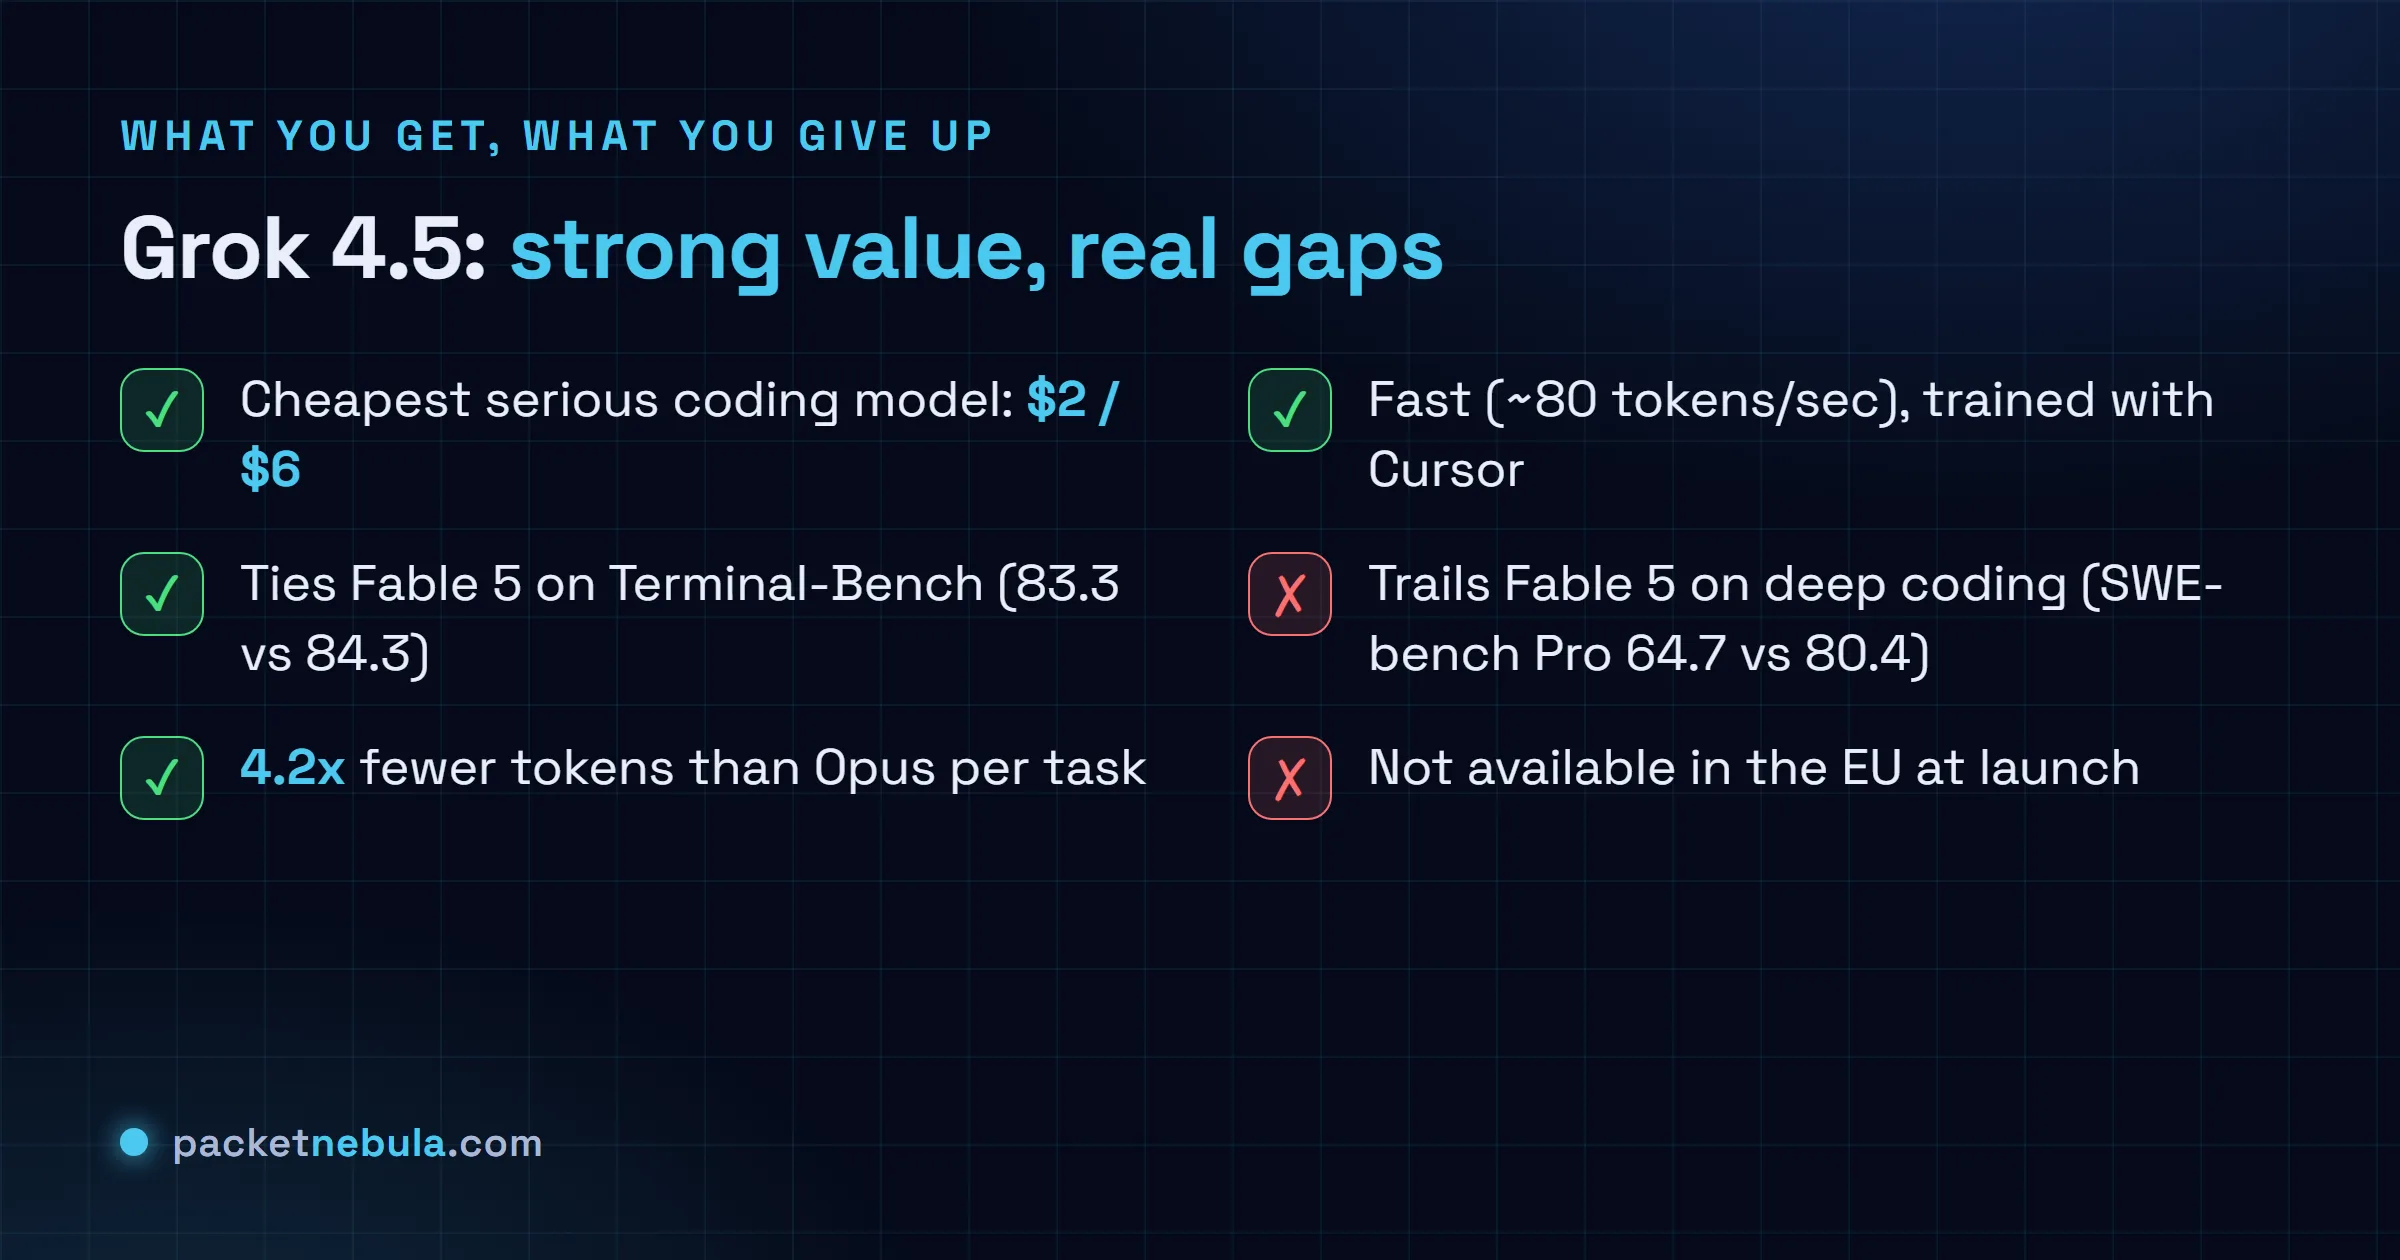
Checklist of Grok 4.5 strengths and catches: cheap, fast, token-efficient, tied on Terminal-Bench, trained with Cursor; trails Fable 5 on deep coding, weaker on DeepSWE, and not available in the EU.
The short version: strong value, real gaps, one hard blocker for EU users.

The catch we can’t ignore: no EU

For readers here, there is a blocker that no benchmark shows. At launch, Grok 4.5 is not available in the European Union. If you are in the EU and you want to use it today, you can’t, full stop, and that decides the question before any price or score does. It is a fair bet xAI opens access later, but “later” is not a plan you can build on this week.

If you are outside the EU and you spend real money on coding tokens, Grok 4.5 is the most interesting launch of the month, and you should try it on your own workload before trusting any benchmark, ours included. If you want the model that wins the hardest coding outright, that is still Fable 5, and we put the two head to head in Claude Fable 5 vs Grok 4.5. If you want the cheaper end of the Anthropic family instead, our Sonnet 5 vs Opus 4.8 breakdown covers it. The pattern across all of them holds: the frontier keeps getting more crowded, and cheaper, from the bottom.

Sources: xAI’s Grok 4.5 announcement and provider listings; benchmark and pricing tables collated by The Decoder and OpenRouter, July 8 2026. Some figures are xAI-reported and not yet independently reproduced; EU availability and exact context limits may change.

Frequently asked questions

How much does Grok 4.5 cost?

Two dollars per million input tokens and six per million output. For comparison, Opus 4.8 is $5/$25, GPT-5.5 is $5/$30, and Fable 5 is $10/$50. On output, the most expensive part, Grok 4.5 is about four times cheaper than Opus and more than eight times cheaper than Fable 5.

Is Grok 4.5 better than Claude Fable 5?

Not on raw capability. Fable 5 leads the hard coding tests: SWE-bench Pro 80.4 against Grok 4.5's 64.7, and DeepSWE 1.1 70 against 53. Grok 4.5 is essentially tied on Terminal-Bench (83.3 vs 84.3). So Fable 5 wins the benchmarks; Grok 4.5 wins the invoice, by a wide margin.

Why is Grok 4.5 so cheap to run?

Two reasons. The per-token rate is low, and the model is unusually token-efficient: xAI reports it resolves SWE-bench Pro tasks using about 15,954 output tokens on average, against roughly 67,020 for Opus 4.8 at max effort, a 4.2x gap. Cheaper tokens and fewer of them compound, so the real per-task cost is lower still.

Can I use Grok 4.5 in the EU?

Not yet. At launch Grok 4.5 is not available in the European Union. If you are in the EU and want a frontier coding model today, that points you back to the Claude, GPT or open-weight options until xAI opens access.

What is Grok 4.5 built for?

Coding, agentic tasks and office work rather than open-ended chat. It was trained alongside Cursor, the AI coding editor, and ships inside it on all plans, plus xAI's own console. It runs at roughly 80 tokens per second, which is quick for a model in this tier.

Tags: aiarticlegrokllmpricingxai
Share198Tweet124
stephane

stephane

  • Trending
  • Comments
  • Latest
Answer card: Proton Lumo 2.0 is private by policy, not by locality. Saved history is locked so even Proton cannot read it, but the prompt is decrypted on a Proton EU server to answer it, then forgotten.

Proton Lumo 2.0 review: how private is it, really?

3 September 2026
The Agentic Coding section of the official Hy4 preview benchmark appendix published by Tencent, a table comparing Hy3 and Hy4 preview against DeepSeek V4 Pro 0813, Qwen 3.8 Max, GLM 5.3, Kimi K3, GPT 5.6 Sol and Claude Opus 5 across SWE-bench Multilingual, SWE-bench Pro, DeepSWE, three SWE Atlas tasks, SWE-Marathon, Terminal-Bench 2.1, NL2Repo-Bench, CyberGym, ProgramBench, PostTrainBench and Harbor-Index.

Tencent’s 770B Hy4 tops one benchmark row in 46

3 September 2026
Answer card: Qwen 3.7 Max is API-only and cannot run locally yet; the open Qwen models (Qwen 3.6 27B, qwen3:8b to 32b) run offline via Ollama.

Qwen 3.7 local: what you can actually run offline

22 June 2026
Answer card: JWTs are not encrypted, anyone can read them; the signature proves who issued the token, not who may read it.

Are JWTs encrypted? No, and the difference will bite you

0
Answer card: a random 8 character password falls in under 2 hours offline, while 16 random characters hold for 1.4 trillion years at the same speed.

How long does it take to crack a password in 2026?

0
Answer card: three DNS records decide if your mail lands or bounces; SPF lists allowed senders, DKIM signs messages, DMARC sets the failure policy.

SPF, DKIM and DMARC explained: the records your email needs

0
The official xAI announcement card for Grok 4.7, white type on a dark grey and navy gradient.

Grok 4.7 keeps $2 and $6, and its gains over 4.6 are xhigh versus high

22 September 2026
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.

Qwen-Image-2.1 brings the weights back, but not the Apache licence

21 September 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
  • About
  • Contact
  • Privacy
  • Legal

Copyright © 2026 Stephane Cardon.

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About

Copyright © 2026 Stephane Cardon.