• Latest
  • Trending
  • All
Answer card: Fable 5 wins the hard coding benchmarks by 15 to 17 points; Grok 4.5 costs about 8x less on output and uses far fewer tokens.

Claude Fable 5 vs Grok 4.5: is 8x cheaper worth it?

3 September 2026
Answer card: Reflection AI announced Beam, a 501B parameter open-weight mixture of experts model, with weights promised later in October 2026.

Reflection Beam is a 501B open model with no weights yet

6 October 2026
Answer card: Aleph Alpha released Kolibri-1 on 3 October 2026 as an Apache 2.0 mixture of experts model with 78.1 billion total and 3.46 billion active parameters, served at 1 million tokens of context but trained on sequences of up to 256 thousand tokens.

Kolibri-1 serves 1M tokens but was trained to 256K

4 October 2026
Answer card on Gemini 4 Argon pricing and gated access, announced by Google on 30 September 2026.

Gemini 4 Argon costs $2 and $10 now, $4 and $20 later

2 October 2026
Answer card for GPT-6.1 Sol showing 2 dollars in and 10 dollars out per million tokens, unchanged from GPT-6 Sol, with cached input at 10 cents.

GPT-6.1 Sol costs what GPT-6 Sol did, and only the cache got cheaper

30 September 2026
Answer card for Claude Sonnet 5.5 showing 2 dollars in and 10 dollars out per million tokens, unchanged from Sonnet 5, and between_tools replacing disabled thinking.

Claude Sonnet 5.5 keeps $2 and $10 and retires thinking disabled

29 September 2026
Answer card: Xiaomi retrained MiMo-V2.6 to stop repeating tool calls, API swapped on 25 September 2026, MIT weights on 27 September, same model names.

MiMo-V2.6-Pro was quietly retrained to stop looping on tool calls

28 September 2026
Answer card: Anthropic committed $11.6 billion over seven years to Akamai Cloud for CPU workloads only, with revenue from the second half of 2027.

Anthropic’s $11.6B Akamai deal buys CPUs, not GPUs

27 September 2026
Answer card: Google Suncatcher MVP satellite, four Trillium TPUs on about one kilowatt, launching on SpaceX Transporter-18, reported for 1 October 2026.

Google’s first Suncatcher satellite flies four TPUs on 1 kW

25 September 2026
Answer card for Claude Opus 5.5: 4 dollars in and 20 dollars out per million tokens, down from 5 and 25, with cache reads at 20 cents.

Claude Opus 5.5 drops to $4 and $20, and breaks four Opus 5 habits

23 September 2026
The official xAI announcement card for Grok 4.7, white type on a dark grey and navy gradient.

Grok 4.7 keeps $2 and $6, and its gains over 4.6 are xhigh versus high

22 September 2026
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.

Qwen-Image-2.1 brings the weights back, but not the Apache licence

21 September 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
  • About
  • Contact
  • Privacy
  • Legal
Wednesday, October 7, 2026
  • Login
Packet Nebula
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About
No Result
View All Result
Packet Nebula
No Result
View All Result
Home Dev

Claude Fable 5 vs Grok 4.5: is 8x cheaper worth it?

by stephane
3 September 2026
in Dev
0
Answer card: Fable 5 wins the hard coding benchmarks by 15 to 17 points; Grok 4.5 costs about 8x less on output and uses far fewer tokens.
495
SHARES
1.4k
VIEWS
Share on FacebookShare on Twitter

Two coding models, one released a week apart, sitting at opposite ends of the market. Claude Fable 5 is the benchmark king: it wins the hardest coding tests outright, and it charges for it at $10 in, $50 out per million tokens. Grok 4.5 lost most of those benchmarks, then answered with a price tag, $2 and $6, that makes you do a double take: about 8x cheaper on output, and it burns roughly a quarter of the tokens on the same task. So the real question isn't which is better, it's whether the gap in quality is worth 8x the bill. Mostly it depends on how hard your work actually is. Here’s the split, priced and mapped, with the one blocker that decides it for anyone in the EU.

The short answer

Fable 5 wins the hard coding benchmarks by 15 to 17 points and charges $10/$50. Grok 4.5 loses those, ties on terminal work, and charges $2/$6 while burning far fewer tokens. Outside the EU, Grok 4.5 is the cost default and Fable 5 the escalation for the hardest work. Inside the EU, Grok isn’t an option yet, so it’s Fable 5.
~8xcheaper output (Grok)
80.4 vs 64.7SWE-bench Pro
EU: Fable onlyGrok not available
Answer card: Fable 5 wins the hard coding benchmarks by 15 to 17 points; Grok 4.5 costs about 8x less on output and uses far fewer tokens.
Raw power versus cheap and efficient. The choice is really about how hard your work is.

Same job, opposite strategies

These two models were built to win different arguments. Fable 5, Anthropic’s Mythos-class flagship, is out to be the most capable coding model on the market, and on the hardest tests it is. Grok 4.5, trained alongside Cursor, is out to be the cheapest model you’d still trust with real code, and on price it’s not close to anyone. One optimizes for the ceiling. The other optimizes for the bill.

The spec sheets even disagree on shape. Fable 5 carries a 1 million token context and always reasons before it answers, with an effort dial that quietly moves the cost. Grok 4.5 ships with a smaller listed context and runs fast and lean, around 80 tokens a second. So this isn’t two versions of the same idea. It’s two bets on what a coding model should cost.

What the benchmarks say

Start where Fable 5 is strongest, because it’s the reason to pay for it. On SWE-bench Pro, the multi-file repository benchmark, Fable 5 scores 80.4 against Grok 4.5’s 64.7. On DeepSWE 1.1, resolving real GitHub issues, it’s 70 against 53. Those are 15 to 17 point gaps, and at that size they’re not noise. On a hard, sprawling change, Fable 5 simply lands more of it, and the misses Grok 4.5 leaves behind are the kind you find in production.

Then the surprise. On Terminal-Bench 2.1, the command-line and agent test, the two nearly tie: Fable 5 at 84.3, Grok 4.5 at 83.3, a single point. So the gap is specifically about deep repository work. For the everyday loop, read a file, run a test, patch, repeat, Grok 4.5 keeps up with a model that costs eight times more per output token. That one benchmark is why the price argument has teeth.
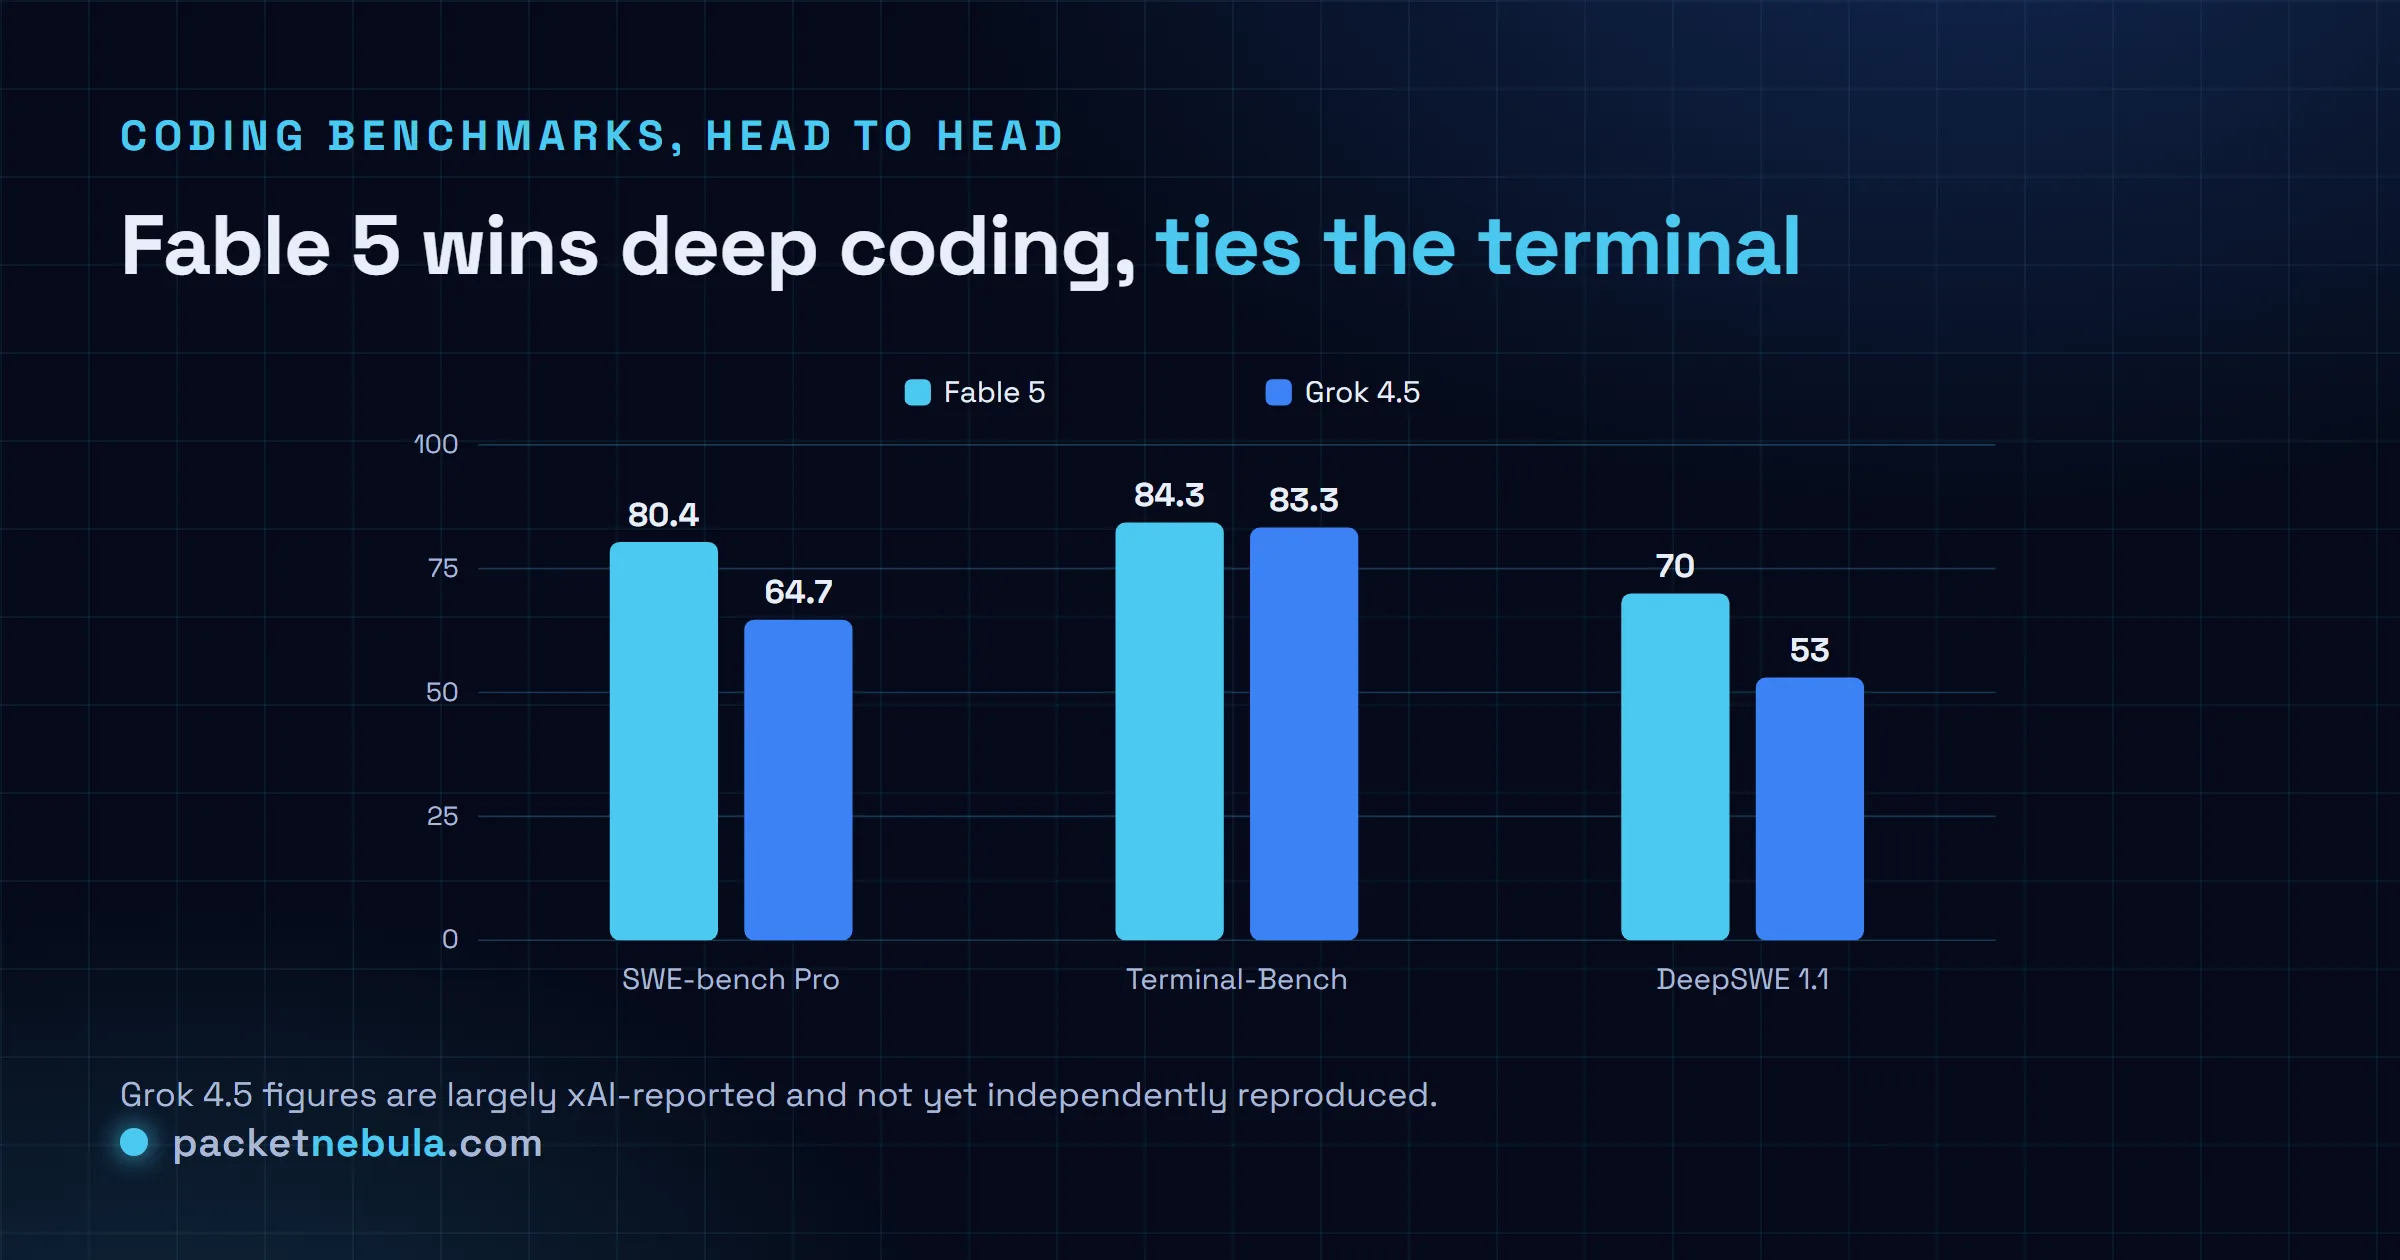
Grouped bar chart of Fable 5 vs Grok 4.5: SWE-bench Pro 80.4 vs 64.7, Terminal-Bench 2.1 84.3 vs 83.3, DeepSWE 1.1 70 vs 53.
Fable 5 wins the deep coding tests by a clear margin, and ties on terminal work. That split is the whole decision.

What the price says

Now the other side of the ledger, where the numbers flip hard. Grok 4.5 is $2 input and $6 output per million tokens. Fable 5 is $10 and $50. That’s five times cheaper on input and about 8.3 times cheaper on output, before you factor in anything else.

And there’s something else. Grok 4.5 is unusually token-efficient: xAI reports it resolving SWE-bench Pro tasks with about 15,954 output tokens on average, against roughly 67,020 for Opus 4.8 at max effort, a 4.2x gap. Fable 5, which always thinks and bills the thinking as output, sits at the expensive end of that spectrum, not the lean one. So the real per-task gap between these two is wider than 8x. On a high-volume agent workload, that’s not a rounding error on the invoice. It’s the invoice.
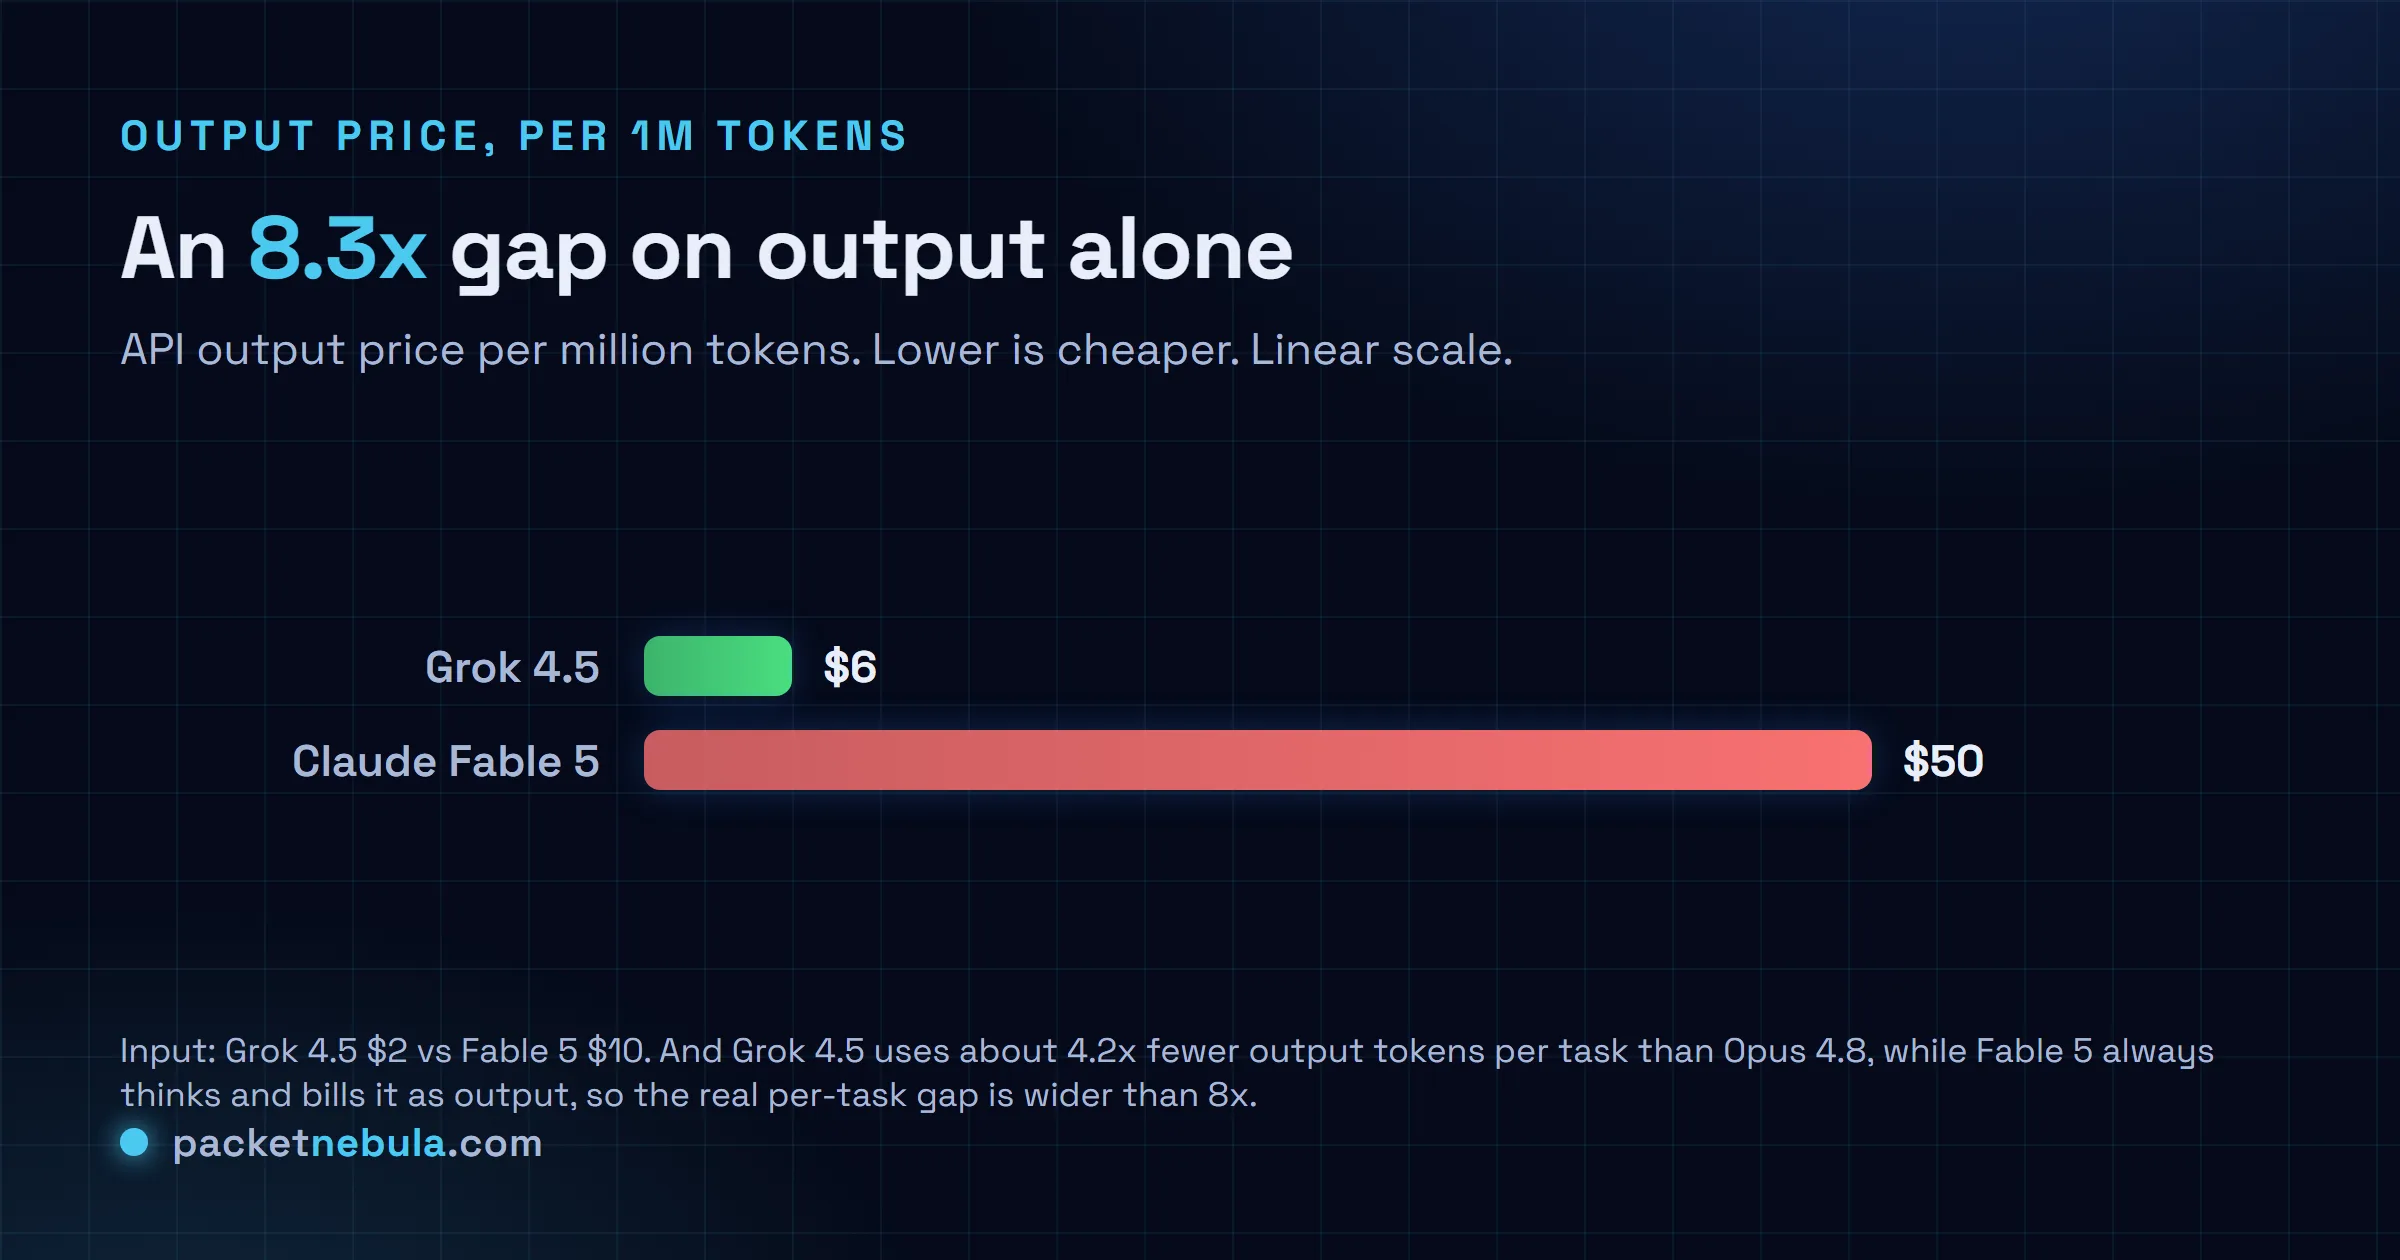
Bar chart of output price per million tokens: Grok 4.5 $6 versus Fable 5 $50, an 8.3x gap, with a note that Grok also uses about 4x fewer tokens per task.
Output price per million tokens. Then remember Grok uses far fewer of them per task.

The blocker no benchmark shows

Before the verdict, the thing that overrides all of it for a lot of readers here. Grok 4.5 isn’t available in the EU at launch. If you’re in Europe, the price and the benchmarks are academic, because you can’t run it, and Fable 5, which is available worldwide, wins by default. Worth knowing the flip side too: Fable 5 requires 30-day data retention and isn’t offered under zero-retention, so if your compliance rules forbid that, neither of these is your model and you’re back to something you can self-host.

The verdict

Outside the EU, run it like a budget with an escape hatch. Grok 4.5 is the default: most coding is normal-difficulty, high-volume work where being 8x cheaper and roughly 4x leaner beats the last fifteen benchmark points you’d never notice. Fable 5 is the escalation, summoned deliberately for the hardest repository-scale changes, the long agent runs, the problems where a run on Grok measurably came up short. Paying 8x for the top model on a task the cheap one handles fine is the expensive mistake here, the same one people make leaving Fable 5’s own effort dial pinned at maximum.

Inside the EU, there’s no fork yet: Fable 5, or one of the models you can actually reach, and our Sonnet 5 vs Fable 5 piece covers the cheaper Anthropic option while you wait for xAI to open the door.

Sources: xAI’s Grok 4.5 announcement and Anthropic’s Fable 5 materials; benchmark and pricing tables collated by The Decoder, July 8 2026. Grok 4.5 figures are largely xAI-reported and not yet independently reproduced; dollar comparisons use published per-million-token rates.

Frequently asked questions

Is Grok 4.5 or Claude Fable 5 better for coding?

For the hardest coding, Fable 5, clearly: it scores 80.4 on SWE-bench Pro and 95 on SWE-bench Verified, against Grok 4.5's 64.7 on Pro, and it leads DeepSWE 70 to 53. For everyday coding at volume, Grok 4.5 is close enough on many tasks and costs about 8x less on output, so it often wins on total cost.

How much cheaper is Grok 4.5 than Fable 5?

A lot. Grok 4.5 is $2 input and $6 output per million tokens; Fable 5 is $10 and $50. That’s 5x cheaper on input and about 8.3x on output. Grok 4.5 also uses roughly 4.2x fewer output tokens than Opus 4.8 on SWE-bench Pro tasks, so the real per-task gap is wider than the rate alone.

Where does Fable 5 clearly beat Grok 4.5?

On deep, multi-file work. SWE-bench Pro (80.4 vs 64.7) and DeepSWE 1.1 (70 vs 53) both put Fable 5 well ahead, by 15 to 17 points. On Terminal-Bench 2.1 they nearly tie (84.3 vs 83.3), so the gap is about the hardest repository-scale changes, not everyday agent work.

Can I use Grok 4.5 in Europe?

Not at launch. Grok 4.5 isn’t available in the EU as of July 8, 2026, while Fable 5 is available worldwide (Fable 5 also requires 30-day data retention, so it’s not offered under zero-retention). For EU teams today, that alone can settle the choice in Fable 5's favour.

Which should I default to?

If you’re outside the EU and cost matters, default to Grok 4.5 and escalate to Fable 5 for the tasks where a run measurably falls short. If you need the maximum coding quality, or you’re in the EU, Fable 5 is the safer default. Match the model to how hard the task really is, not to habit.
Tags: aiarticlebenchmarksclaudegrokllm
Share198Tweet124
stephane

stephane

  • Trending
  • Comments
  • Latest
Answer card: Proton Lumo 2.0 is private by policy, not by locality. Saved history is locked so even Proton cannot read it, but the prompt is decrypted on a Proton EU server to answer it, then forgotten.

Proton Lumo 2.0 review: how private is it, really?

3 September 2026
The Agentic Coding section of the official Hy4 preview benchmark appendix published by Tencent, a table comparing Hy3 and Hy4 preview against DeepSeek V4 Pro 0813, Qwen 3.8 Max, GLM 5.3, Kimi K3, GPT 5.6 Sol and Claude Opus 5 across SWE-bench Multilingual, SWE-bench Pro, DeepSWE, three SWE Atlas tasks, SWE-Marathon, Terminal-Bench 2.1, NL2Repo-Bench, CyberGym, ProgramBench, PostTrainBench and Harbor-Index.

Tencent’s 770B Hy4 tops one benchmark row in 46

3 September 2026
Answer card: Qwen 3.7 Max is API-only and cannot run locally yet; the open Qwen models (Qwen 3.6 27B, qwen3:8b to 32b) run offline via Ollama.

Qwen 3.7 local: what you can actually run offline

22 June 2026
Answer card: JWTs are not encrypted, anyone can read them; the signature proves who issued the token, not who may read it.

Are JWTs encrypted? No, and the difference will bite you

0
Answer card: a random 8 character password falls in under 2 hours offline, while 16 random characters hold for 1.4 trillion years at the same speed.

How long does it take to crack a password in 2026?

0
Answer card: three DNS records decide if your mail lands or bounces; SPF lists allowed senders, DKIM signs messages, DMARC sets the failure policy.

SPF, DKIM and DMARC explained: the records your email needs

0
Answer card: Reflection AI announced Beam, a 501B parameter open-weight mixture of experts model, with weights promised later in October 2026.

Reflection Beam is a 501B open model with no weights yet

6 October 2026
Answer card: Aleph Alpha released Kolibri-1 on 3 October 2026 as an Apache 2.0 mixture of experts model with 78.1 billion total and 3.46 billion active parameters, served at 1 million tokens of context but trained on sequences of up to 256 thousand tokens.

Kolibri-1 serves 1M tokens but was trained to 256K

4 October 2026
Answer card on Gemini 4 Argon pricing and gated access, announced by Google on 30 September 2026.

Gemini 4 Argon costs $2 and $10 now, $4 and $20 later

2 October 2026
  • About
  • Contact
  • Privacy
  • Legal

Copyright © 2026 Stephane Cardon.

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About

Copyright © 2026 Stephane Cardon.