
• Latest
  • Trending
  • All
Answer card: OpenAI GPT-Realtime-2.1 and a mini reasoning model for the Realtime API, with p95 latency down at least 25% from better caching.

OpenAI GPT-Realtime-2.1: what changed for voice agents

7 July 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
Answer card stating that Jev 1.13 from TypeSafe AI is a decision model in early access since 15 September 2026 that returns typed probabilities instead of text, priced at 42 dollars per billion input tokens with output tokens free, answering in 70 to 500 milliseconds, with a 64K token request budget, text input only, and a documented list of things it does badly, including counting and dates.

Jev 1.13 bills $42 a billion tokens, and it can’t count

19 September 2026
Answer card stating that Qwen3.8-Omni-Flash launched on 17 September 2026 as an API only model on Alibaba Cloud Model Studio, taking text, images, audio and video in a 1M token context and returning text only, priced at 0.15 dollars per million input tokens for every modality and 0.47 dollars per million output tokens in the international regions, with no open weights published and the Qwen-Live Harness GitHub repository returning 404.

Qwen3.8-Omni-Flash bills audio at $0.15 and ships no weights

18 September 2026
Answer card stating that on 15 September 2026 AWS said it is unable to restore access to resources and data hosted exclusively in the Middle East Bahrain region me-south-1 and in the mec1-az2 zone of the UAE region, because the damage spanned multiple Availability Zones and exceeded what multi-AZ services are designed to withstand.

AWS can’t restore me-south-1, six months after the drone strikes

17 September 2026
Answer card stating that Google released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking on 15 September 2026 at 3 dollars per million audio input tokens and 12 dollars out, that the thinking model requires asynchronous tools, and that Artificial Analysis scores it 82.6 on its Speech to Speech Quality Index.

Gemini 3.8 Live Extended Thinking rejects any tool that blocks

16 September 2026
Answer card summarising the Atria Dawn Preview release: 744B GLM-5.2 base, MIT licence, 1.5 TB BF16 and 756 GB FP8 checkpoints, 256K context, top on five of sixteen benchmark rows and trailing on SWE-bench Pro.

Atria Dawn Preview is 744B under MIT, and the BF16 weighs 1.5 TB

15 September 2026
Answer card stating that OpenAI released the Agents API in public beta on 10 September 2026 with no separate fee, billed through model tokens, tool calls and hosted sandbox time, with a choice of OpenAI hosted, self hosted or partner sandboxes, US only data residency and no Zero Data Retention support.

OpenAI’s Agents API has no fee, no ZDR and a one hour sandbox clock

14 September 2026
Answer card: Sakana Fugu Max at $2 and $6 per million tokens, Fugu Ultra v2 unchanged at $5 and $30, and Sakana saying Ultra v2 scores without Fable 5 or GPT-6 Astra in its pool.

Fugu Max costs $2 and $6 while Fugu Ultra v2 runs without Fable 5

13 September 2026
Answer card stating that DeepSeek released DeepSeek-V4.1-Flash on 10 September 2026 as a 552 billion parameter mixture of experts model with a new causal encoder decoder architecture that activates 8 billion parameters on input and 16 billion on output, with native vision, a one million token context and MIT licensed weights, that the API model name is now deepseek-flash at 0.15 dollars per million input tokens and 0.60 dollars per million output tokens off peak, and that DeepSeek announced V4 Pro would be routed to V4.1-Flash from 14 September and reversed that on 11 September.

DeepSeek V4.1-Flash arrived, and the V4 Pro retirement lasted a day

12 September 2026
Answer card stating that Cognition released SWE-2 on 10 September 2026, a coding model post-trained from Kimi K3, scoring 50.0 percent on FrontierCode 1.1 Main against 50.9 percent for Claude Fable 5.1 and 27.3 percent on Terminal-Bench 4 against 55.8 percent, available only inside Devin.

SWE-2 trails Fable 5.1 by one point, and by 28 on Terminal-Bench 4

11 September 2026
Answer card for Meta Muse, free to 100 million tokens a week then $20 a month, launched 8 September 2026 for United States adults only, running in a dedicated per user virtual machine.

Does Meta Muse do enough to earn your inbox and a card on file?

9 September 2026
Answer card stating that the public download pages for the VMware Virtual Disk Development Kit on developer.broadcom.com began returning 404 errors on 25 August 2026 with no announcement or deprecation notice, that Broadcom support tells customers the kit is no longer available for use or download, and that release lines 7.0.3.1, 8.x and 9.x are all affected.

Broadcom pulled VDDK 8.0 and 9.0, and the 404 is the only notice

8 September 2026
  • About
  • Contact
  • Privacy
  • Legal
Sunday, September 20, 2026
  • Login
Packet Nebula
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About
No Result
View All Result
Packet Nebula
No Result
View All Result
Home Dev

OpenAI GPT-Realtime-2.1: what changed for voice agents

by stephane
7 July 2026
in Dev
0
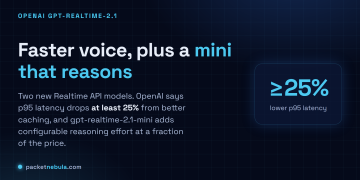
Answer card: OpenAI GPT-Realtime-2.1 and a mini reasoning model for the Realtime API, with p95 latency down at least 25% from better caching.
492
SHARES
1.4k
VIEWS
Share on FacebookShare on Twitter

Your voice agent hangs for a beat after the caller stops talking, and that beat is where the call feels robotic. On July 6, OpenAI pushed two new Realtime API models, gpt-realtime-2.1 and gpt-realtime-2.1-mini, and the headline we'd give a colleague is short: same voice stack, lower p95 latency (OpenAI says at least 25%, from better caching), and a mini model that now reasons with a configurable effort dial. It's an API update, not a new ChatGPT voice. So the real question is whether the numbers change how you'd build a phone agent, and which of the two you actually call.

The short answer

OpenAI shipped gpt-realtime-2.1 and gpt-realtime-2.1-mini for the Realtime API. The full model gets cleaner interruption and noise handling and better alphanumeric recognition. The mini now reasons with a configurable effort dial, at the same price as before. Latency drops at least 25% on OpenAI’s own p95 numbers, from caching. Net for you: a real, measurable upgrade for voice agents, but verify the latency claim on your own traffic.
July 6released on the API
≥25%lower p95 latency
$20 vs $64mini vs full, audio out
Answer card: OpenAI GPT-Realtime-2.1 brings faster voice and a mini model that reasons, with p95 latency down at least 25% from better caching.
The one-card version. Faster voice, a mini that now reasons, same Realtime plumbing.

What OpenAI actually shipped

Two model strings, not a new product. On July 6, OpenAI added gpt-realtime-2.1 and gpt-realtime-2.1-mini to the Realtime API, the speech-to-speech interface that powers phone agents, live support bots, and anything where a person talks and the model talks back in near real time. If you already run gpt-realtime-2, this is the next snapshot, and swapping to it is a model-string change you can A/B test.

The full model, gpt-realtime-2.1, is the incremental-but-useful kind of update. OpenAI calls out three fixes over gpt-realtime-2: better alphanumeric recognition, better silence and noise handling, and better interruption behaviour. That first one sounds dull and isn’t. If your agent takes order numbers, postcodes, card digits or booking references over the phone, garbled alphanumerics are the bug that quietly tanks your completion rate. We’ve watched a demo bot hear “B as in boy” and write “P”. So a cleaner read on codes is worth more than it looks on the changelog.
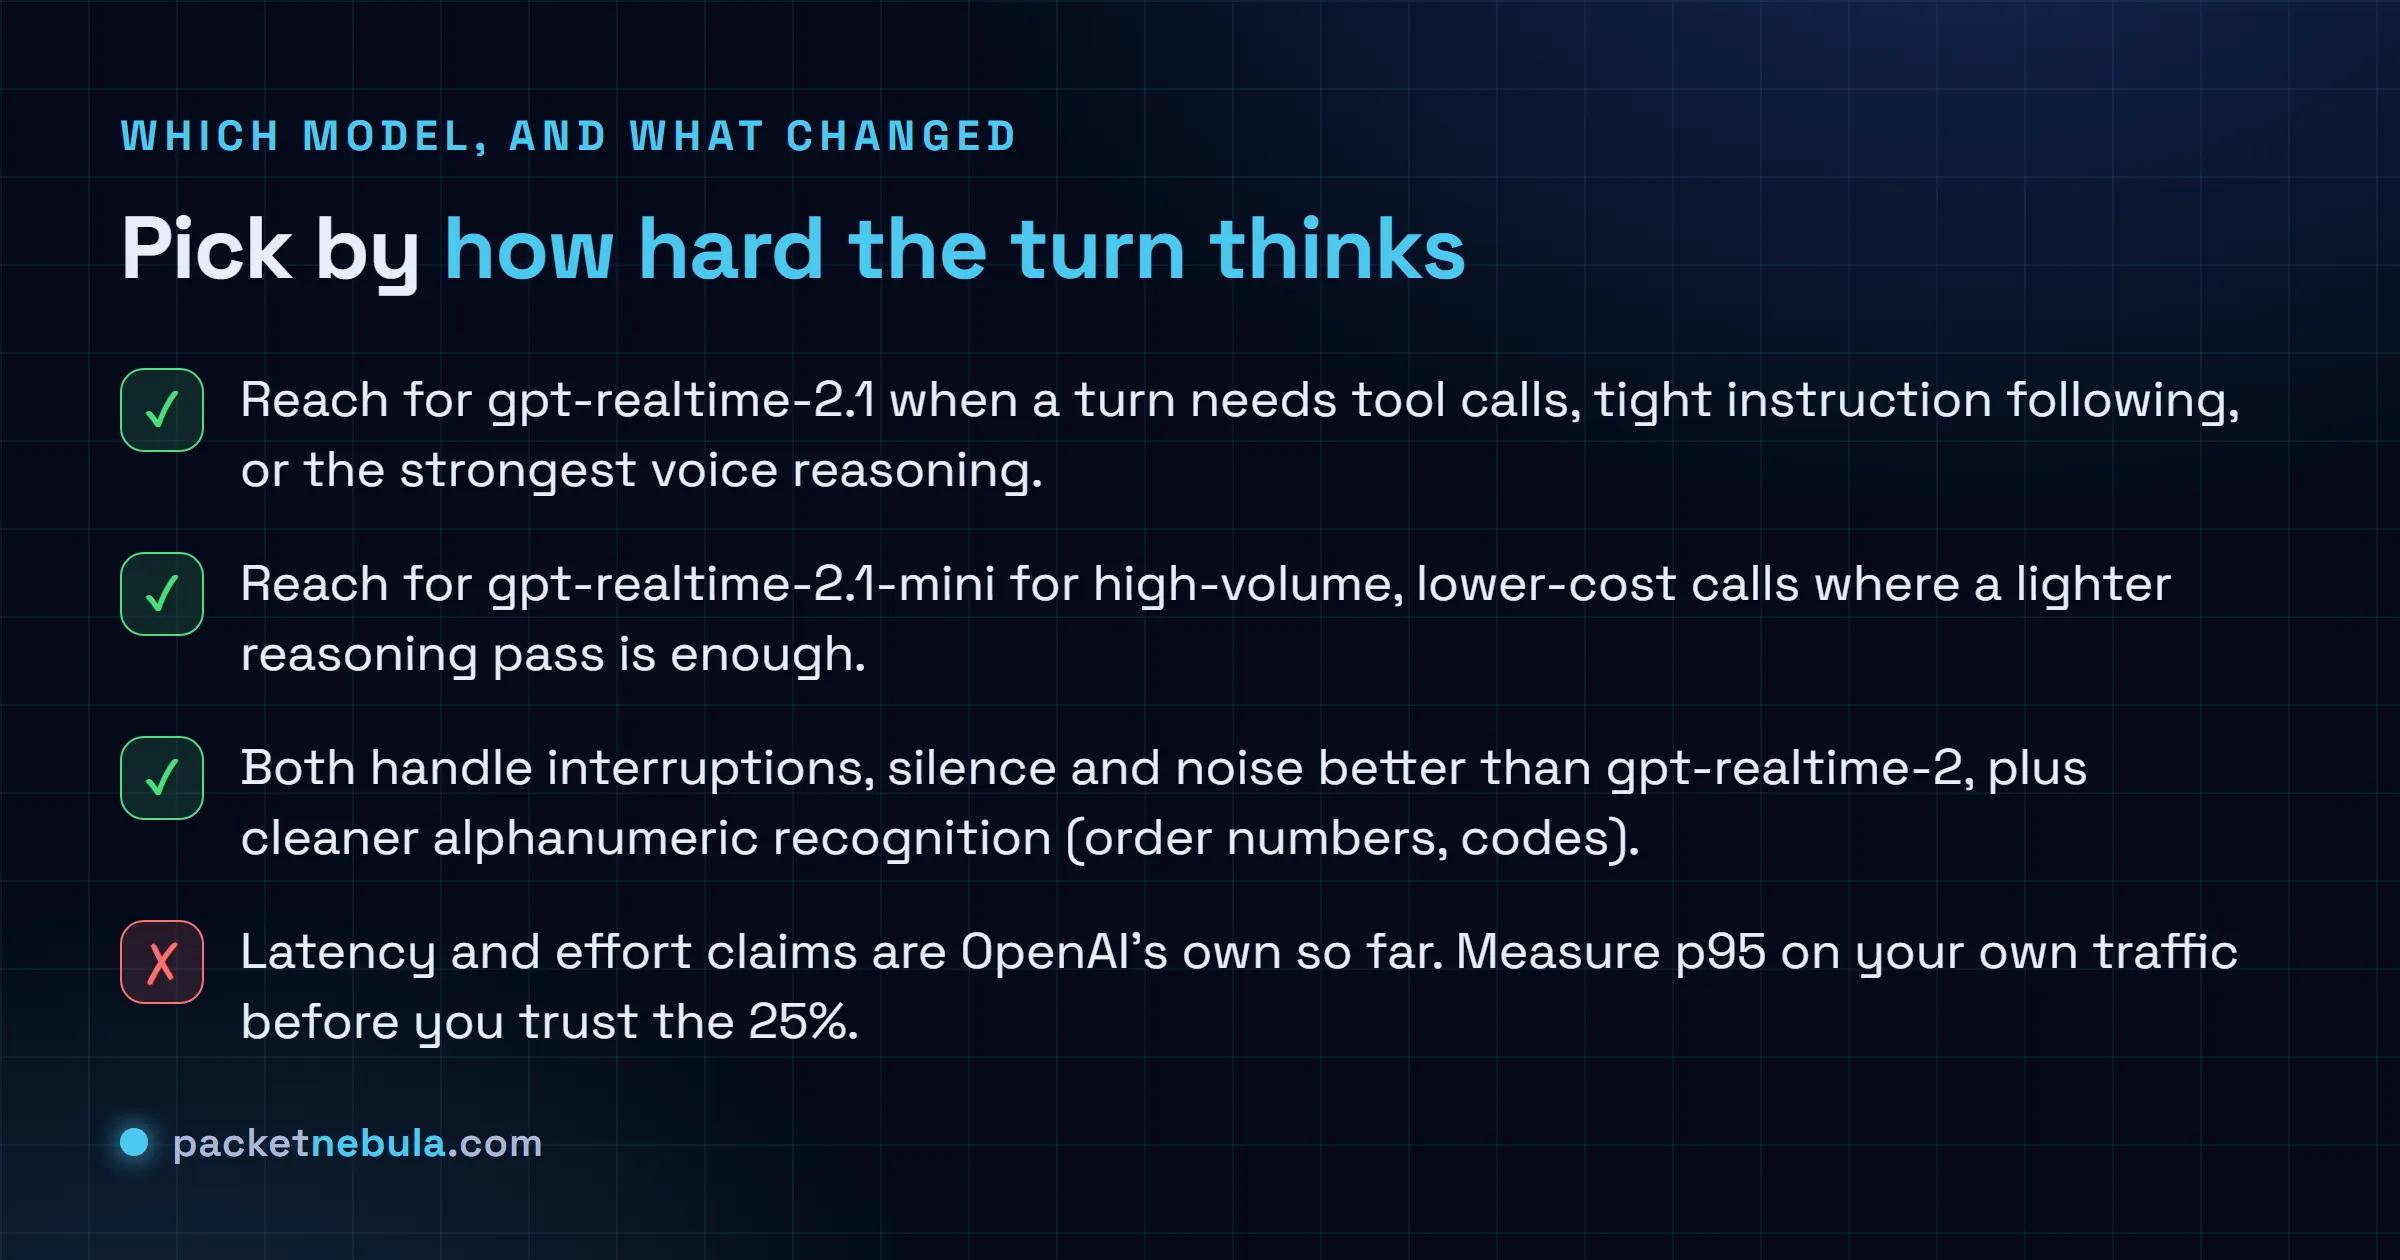
Checklist of when to use gpt-realtime-2.1 versus the mini, what improved over gpt-realtime-2, and the caveat that the latency claim is OpenAI's own.
The honest split: which model to call, what actually changed, and the one number to verify yourself.

The mini grew a brain

Here’s the part that’s genuinely new. gpt-realtime-2.1-mini isn’t just a smaller, cheaper voice model any more. It’s a mini reasoning model, with configurable reasoning effort, the same kind of low-to-high effort dial you’ve seen on the text side. Per OpenAI, the mini ships at the same price as the earlier gpt-realtime-mini. So the reasoning upgrade is, in effect, free.

Why does that matter for a voice build? Because voice agents live or die on the turn that needs a little thought. “Cancel my Tuesday appointment and rebook me after 3pm” is a turn where a purely reflexive model fumbles and a reasoning pass saves the call. Before, you’d reach for the full model for those, and eat the cost on every turn including the trivial ones. Now the mini can think a bit when it has to, and you keep the full model for the genuinely hard workflows: dense tool chains, strict instruction following, the stuff where a wrong step is expensive.

Honestly, I think the effort dial on the mini is the more interesting release than the latency line everyone’s quoting. Latency is a one-time win. A cheap model that can reason on demand changes how you architect the whole agent.

The price gap is the whole design decision

Audio output is what a talking agent burns most, and that’s where the two models split hard. The full model is $64 per million audio output tokens. The mini is $20. Input tells the same story: $32 versus $10 for audio, $4 versus $0.60 for text. At phone-agent volume, that difference isn’t a rounding error, it’s your margin.
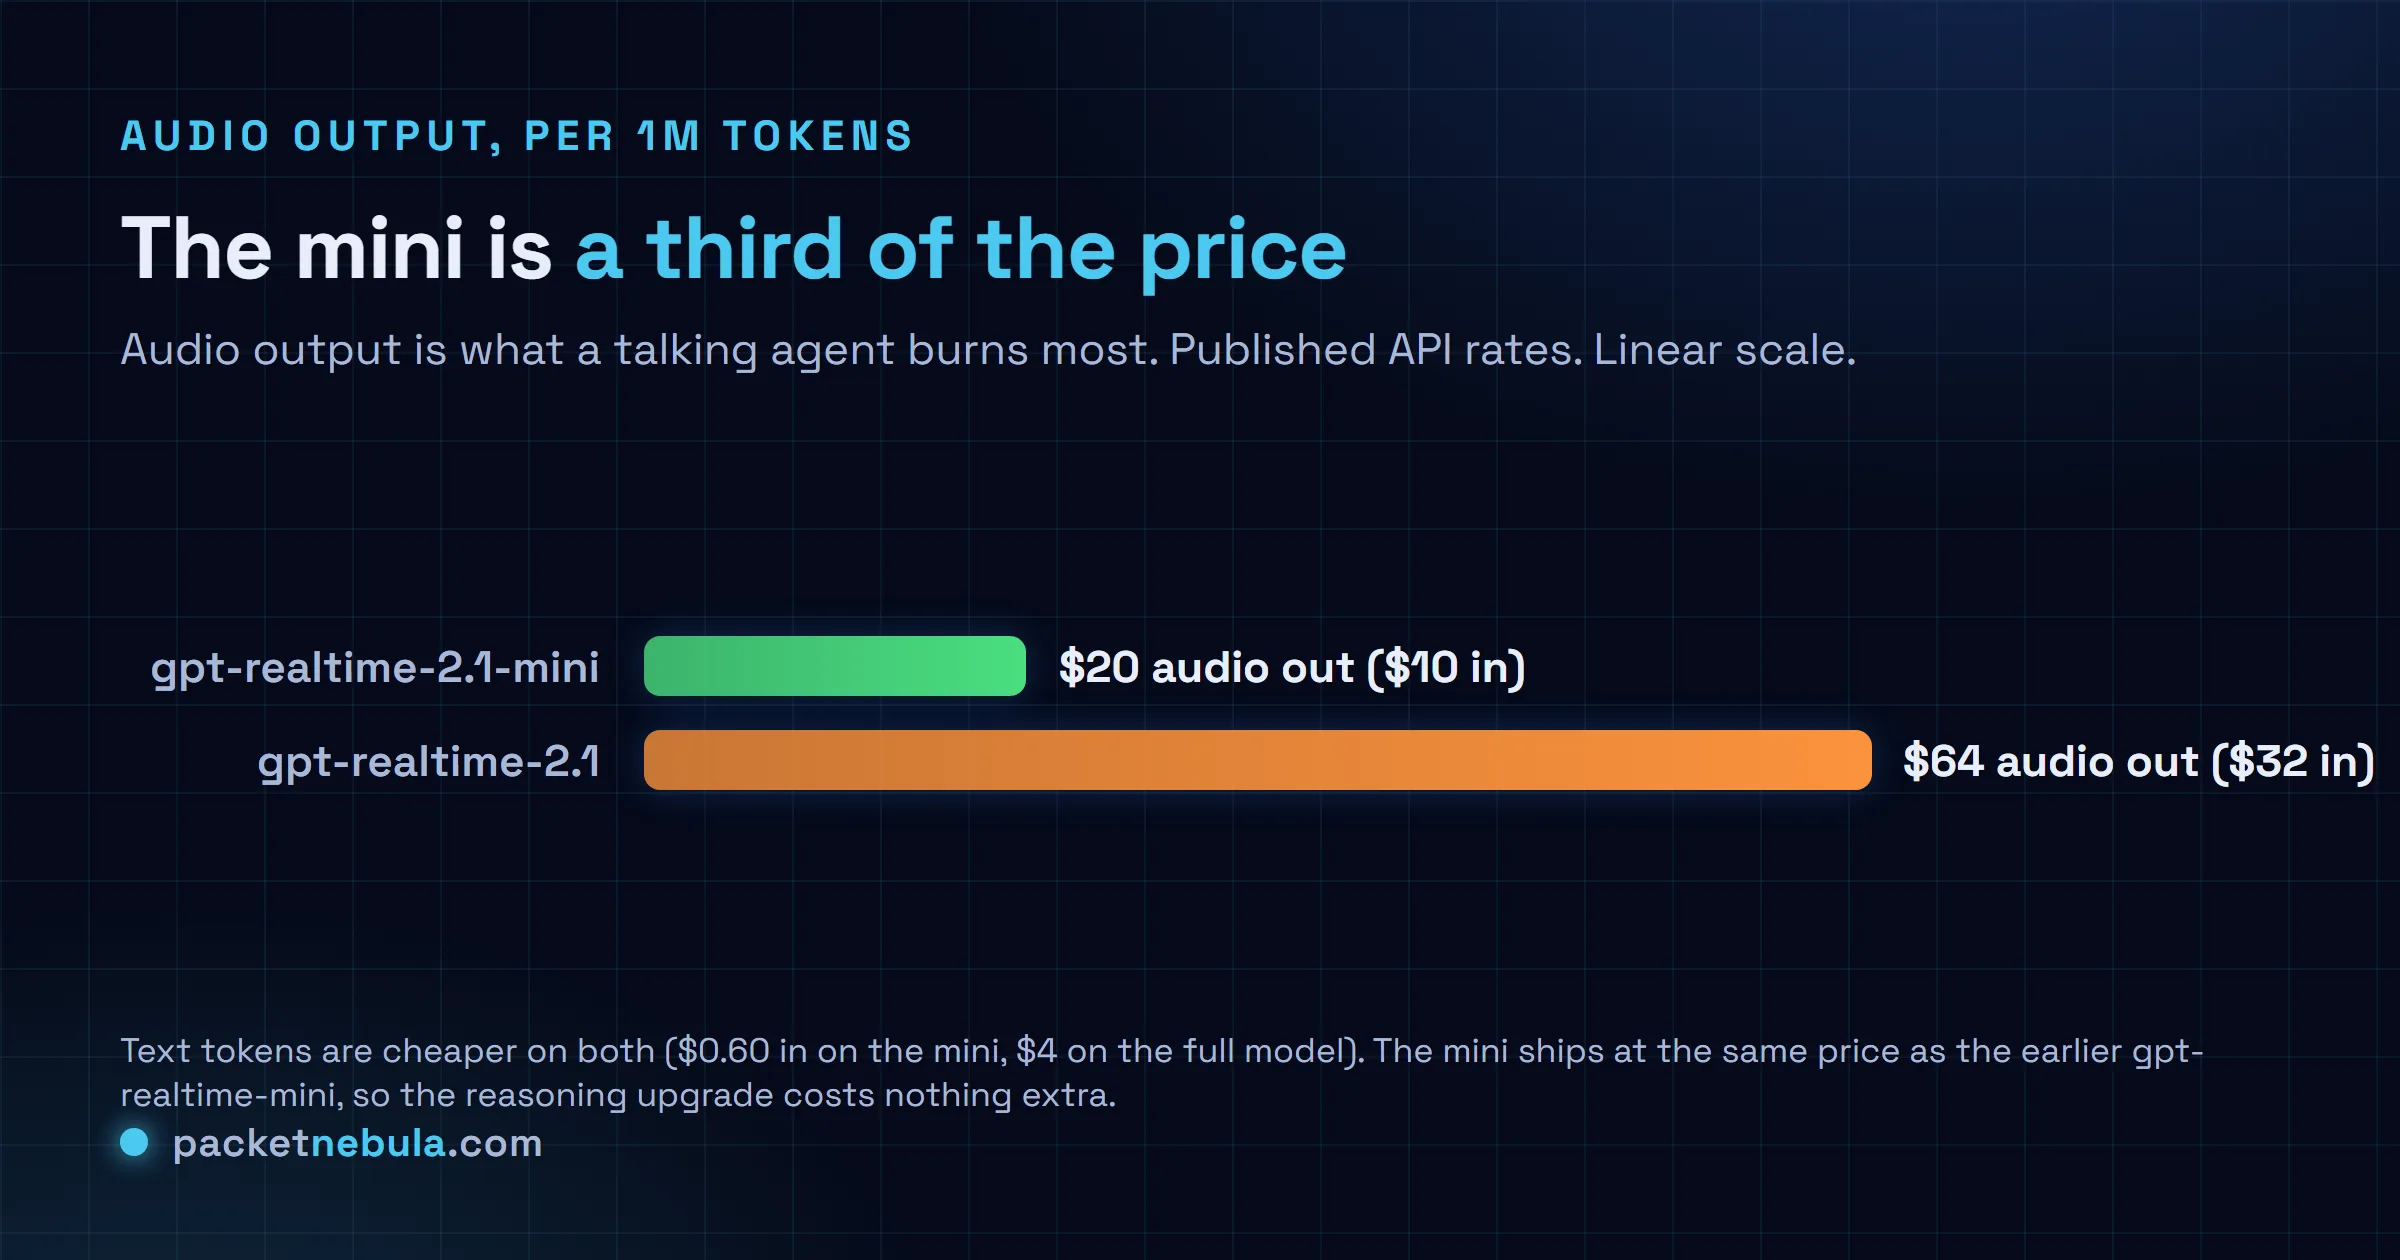
Comparison bar chart: gpt-realtime-2.1-mini at $20 per million audio output tokens versus gpt-realtime-2.1 at $64, roughly a third of the price.
Roughly a third of the price on audio output. The mini's new reasoning is what makes that a real choice, not a compromise.

So the build pattern writes itself. Default your turns to the mini. Route the hard ones, or the ones that trip its reasoning, up to gpt-realtime-2.1. If you’ve sized inference cost on the text side before, this is the same story in a different medium: the model rate is fixed, but which model you call on each turn is the dial that sets the bill. Our Fable 5 effort-level breakdown walks through exactly how a reasoning dial turns into real money, and it applies cleanly here.

About that 25% latency claim

The number OpenAI put front and centre is p95 latency down at least 25% across the Realtime voice models, and the cause it gives is improved caching. Read that the way you’d read any vendor’s own benchmark. It’s a p95, which is the right percentile to care about for voice (the tail is what a caller feels), and it’s plausible that better caching of session context shaves the slow turns. But it’s OpenAI measuring OpenAI, on unstated traffic. Your prompts, your tool latency, your audio setup all move the real number.

So do the boring thing. Log p95 on your current gpt-realtime-2 build, switch the model string, and log it again on the same traffic. If you get anywhere near 25%, lovely. If you don’t, you’ve lost nothing but a config change. We wouldn’t re-architect a call flow on a press-release number, and neither should you.

If you’re weighing this against a bigger model decision rather than a voice one, the GPT-5.6 versus GPT-5.5 tradeoff is the one that moves your bill more than a Realtime snapshot does.

The honest read

gpt-realtime-2.1 is a solid, unglamorous upgrade: faster on the tail, cleaner on codes and interruptions, worth the model-string swap once you’ve verified the latency on your own traffic. The mini is the quiet headline. A voice model at a third of the price that can now reason on demand changes the default answer to “which model do I call,” and it costs nothing extra to try. Build for the mini, escalate to the full model when a turn earns it, and measure p95 yourself instead of trusting the 25%. That’s the whole play.

Sources: OpenAI’s official Realtime models announcement on the OpenAI Developer Community (July 6, 2026), with reporting and pricing via MarkTechPost and The Next Web. Latency and effort figures are OpenAI’s own measurements; verify p95 on your own traffic before relying on them.

Frequently asked questions

What is gpt-realtime-2.1?

It is OpenAI's updated speech-to-speech model on the Realtime API, released on July 6, 2026. It succeeds gpt-realtime-2 with better alphanumeric recognition, silence and noise handling, and interruption behaviour, and OpenAI reports p95 latency down at least 25% across the Realtime voice models from improved caching. It is aimed at production voice agents that need tool use and tight instruction following.

How is gpt-realtime-2.1-mini different?

The mini is a smaller, cheaper Realtime model that now supports configurable reasoning effort, so you can trade a bit of latency for a stronger reasoning pass per turn. OpenAI ships it at the same price as the earlier gpt-realtime-mini, so the reasoning upgrade does not cost extra. Reach for it on high-volume calls where you do not need the full model's strongest reasoning or heaviest tool use.

How much does gpt-realtime-2.1 cost?

At the published Realtime API rates, gpt-realtime-2.1 is $4 per million text input tokens, $32 per million audio input, and $64 per million audio output. The mini is far cheaper at $0.60 text input, $10 audio input, and $20 audio output per million tokens. Cached input is heavily discounted on both, which is part of where the latency win comes from.

Is the 25% latency improvement guaranteed?

No. The at-least-25% p95 figure is OpenAI's own measurement across the Realtime voice models, driven by caching, and your result depends on your prompts, tools, and traffic shape. Treat it as a strong signal, not a spec, and measure p95 on your own agent before and after switching.

How do I switch to the new models?

Point your Realtime API session at the gpt-realtime-2.1 or gpt-realtime-2.1-mini model identifier instead of gpt-realtime-2. Both are available to test in the OpenAI Playground first. Nothing else in the Realtime flow changes, so it is a model-string swap you can A/B against your current build.

Tags: aiapinewsopenairealtimevoice
Share197Tweet123
stephane

stephane

  • Trending
  • Comments
  • Latest
Answer card: Proton Lumo 2.0 is private by policy, not by locality. Saved history is locked so even Proton cannot read it, but the prompt is decrypted on a Proton EU server to answer it, then forgotten.

Proton Lumo 2.0 review: how private is it, really?

3 September 2026
The Agentic Coding section of the official Hy4 preview benchmark appendix published by Tencent, a table comparing Hy3 and Hy4 preview against DeepSeek V4 Pro 0813, Qwen 3.8 Max, GLM 5.3, Kimi K3, GPT 5.6 Sol and Claude Opus 5 across SWE-bench Multilingual, SWE-bench Pro, DeepSWE, three SWE Atlas tasks, SWE-Marathon, Terminal-Bench 2.1, NL2Repo-Bench, CyberGym, ProgramBench, PostTrainBench and Harbor-Index.

Tencent’s 770B Hy4 tops one benchmark row in 46

3 September 2026
Answer card: Qwen 3.7 Max is API-only and cannot run locally yet; the open Qwen models (Qwen 3.6 27B, qwen3:8b to 32b) run offline via Ollama.

Qwen 3.7 local: what you can actually run offline

22 June 2026
Answer card: JWTs are not encrypted, anyone can read them; the signature proves who issued the token, not who may read it.

Are JWTs encrypted? No, and the difference will bite you

0
Answer card: a random 8 character password falls in under 2 hours offline, while 16 random characters hold for 1.4 trillion years at the same speed.

How long does it take to crack a password in 2026?

0
Answer card: three DNS records decide if your mail lands or bounces; SPF lists allowed senders, DKIM signs messages, DMARC sets the failure policy.

SPF, DKIM and DMARC explained: the records your email needs

0
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
Answer card stating that Jev 1.13 from TypeSafe AI is a decision model in early access since 15 September 2026 that returns typed probabilities instead of text, priced at 42 dollars per billion input tokens with output tokens free, answering in 70 to 500 milliseconds, with a 64K token request budget, text input only, and a documented list of things it does badly, including counting and dates.

Jev 1.13 bills $42 a billion tokens, and it can’t count

19 September 2026
Answer card stating that Qwen3.8-Omni-Flash launched on 17 September 2026 as an API only model on Alibaba Cloud Model Studio, taking text, images, audio and video in a 1M token context and returning text only, priced at 0.15 dollars per million input tokens for every modality and 0.47 dollars per million output tokens in the international regions, with no open weights published and the Qwen-Live Harness GitHub repository returning 404.

Qwen3.8-Omni-Flash bills audio at $0.15 and ships no weights

18 September 2026
  • About
  • Contact
  • Privacy
  • Legal

Copyright © 2026 Stephane Cardon.

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About

Copyright © 2026 Stephane Cardon.