A leaked internal memo, not a keynote, is how we found out Meta has a new chip. On July 9 Reuters reported it: Iris, the latest in Meta's in-house MTIA line, goes into volume production in September, built with Broadcom and fabbed at TSMC. Here's the one-line version we'd give a colleague. It's silicon for the boring, constant work, the ranking and recommendation that runs your Facebook and Instagram feed, not the frontier training that still leans on rented Nvidia and AMD. One chip reportedly cleared validation in about six weeks. It isn't for sale, there's no public benchmark, and nothing lands before the autumn. So the question isn't whether Meta can make a chip. It's whether any of this reaches you.
The short answer
A leaked memo says Meta will put Iris, the newest chip in its in-house MTIA line, into production in September. It targets ranking and app inference, not frontier training, and you cannot buy one. The near-term effect on your work is basically nothing. The slow-burn effect, if it pans out, is Meta leaning less on the Nvidia supply everyone else is fighting over.
What Meta actually confirmed (nothing, officially)
Start with how thin the confirmation is. There was no launch event. Reuters got an internal memo on July 9 and reported the plan, and everything below traces back to that. So we’re reading a company’s private roadmap, not a spec sheet. Worth holding onto as you read the numbers.
Here’s what the memo lays out. Iris is the next chip in Meta’s MTIA program, the in-house effort that stands for Meta Training and Inference Accelerator. Broadcom is the design partner, TSMC does the fabrication, and the memo names a supporting cast too: Samsung on memory, SanDisk on storage, Sumitomo on the fiber-optic gear that stitches the racks together. Production is set for September. One chip reportedly sailed through validation in roughly six weeks with no major anomaly, which is the kind of clean run that lets a schedule hold. Meta reportedly wants a fresh MTIA generation about every six months through 2027, each one a modular chiplet design building on the last.
The money behind it is the part that makes you sit up. Meta is trying to roughly double its AI compute, from about 7 gigawatts of capacity in 2026 to 14 in 2027, against projected capital spending somewhere in the $125 to $145 billion range this year. Iris is one lever on that bill.
Ranking and inference, not frontier training
Here’s the distinction that makes sense of the news, and it’s where Iris differs from the other custom-silicon story doing the rounds. Meta isn’t trying to train the next Llama on this thing. The memo points Iris at ranking and recommendation, the models that decide what shows up when you open the app, plus inference for Meta’s products. That’s the workload that never sleeps. Every scroll, every person, all day. At Meta’s scale it’s the meter that never stops spinning, and it’s exactly the kind of steady, predictable job custom silicon eats for lunch.
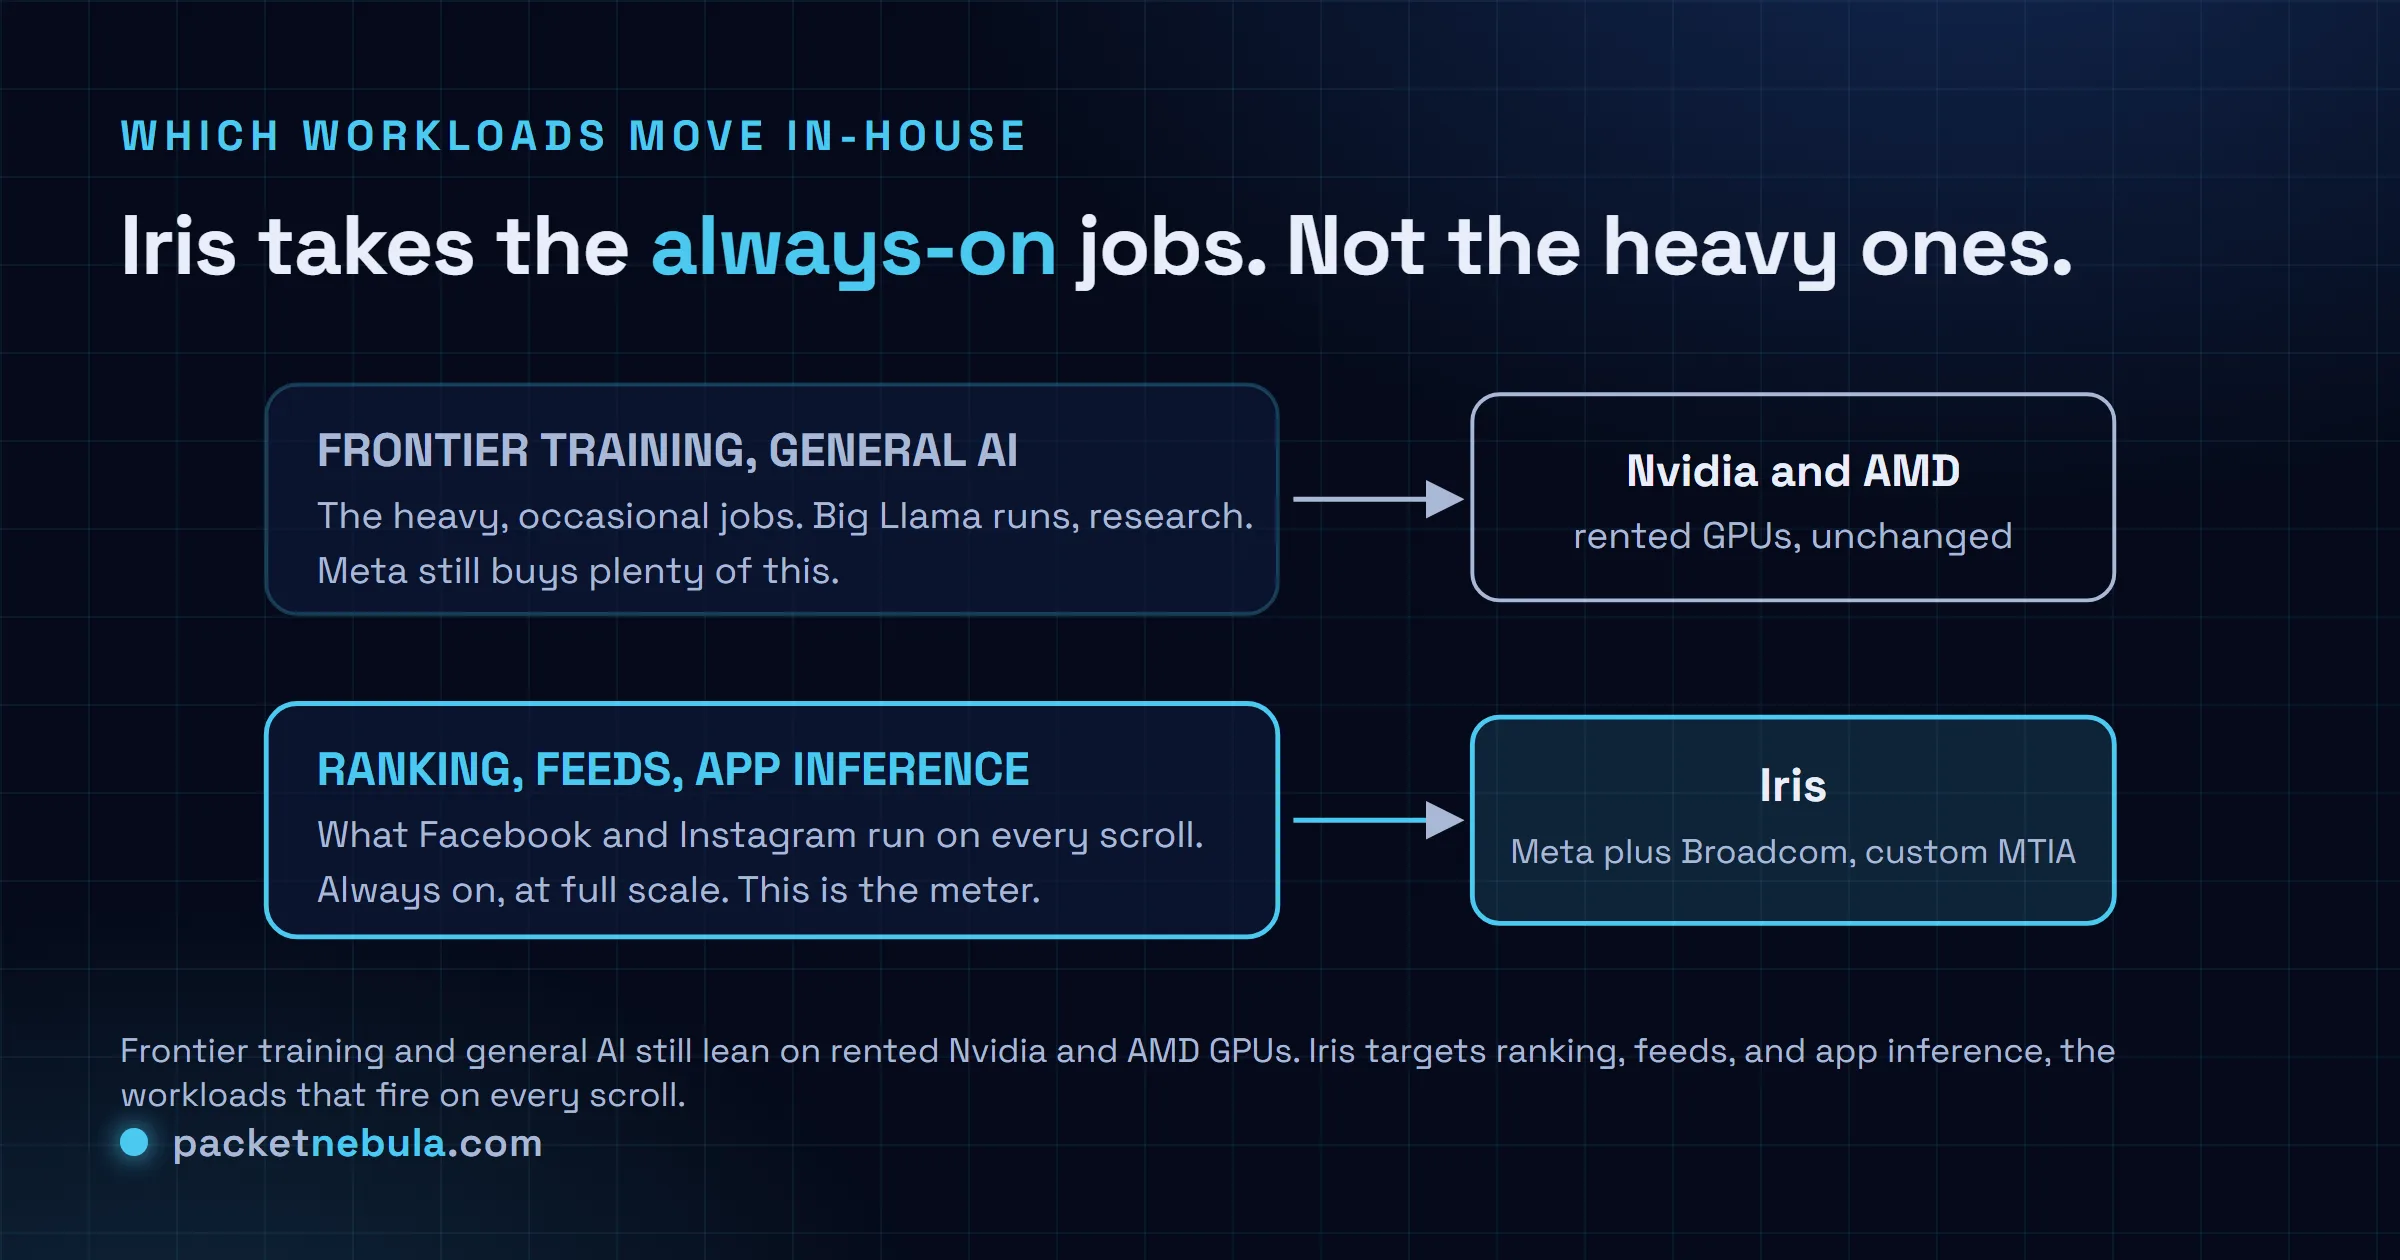
The frontier stuff, the big training runs and general research, still leans on rented Nvidia and AMD hardware, and Meta was blunt that it expects to keep buying plenty of it. So Iris isn’t a Nvidia killer. It’s Meta carving off the one slice of its workload that’s constant enough to justify its own chip, and letting the GPUs handle the spiky, experimental rest. Every recommendation query Facebook and Instagram serve on Meta’s own metal is a query that doesn’t pay Nvidia’s margin. That, is the whole point.
If this pattern feels familiar, it should. OpenAI told almost the same story a couple of weeks back with its Jalapeño inference chip, also built with Broadcom, also aimed at the serving side rather than training. Two of the biggest AI spenders, same playbook, same silicon partner. That’s not a coincidence, it’s the shape of the whole market right now.
Does it change your day? Mostly no
Let’s be honest about the reach here. You can’t buy an Iris, you can’t rent one, and it doesn’t touch the quality of anything you use. The Meta apps stay the apps. If you build on Llama or Meta’s API, the models don’t change because the chip underneath them did. This isn’t hardware headed for your homelab, and nothing on the roadmap pretends otherwise.
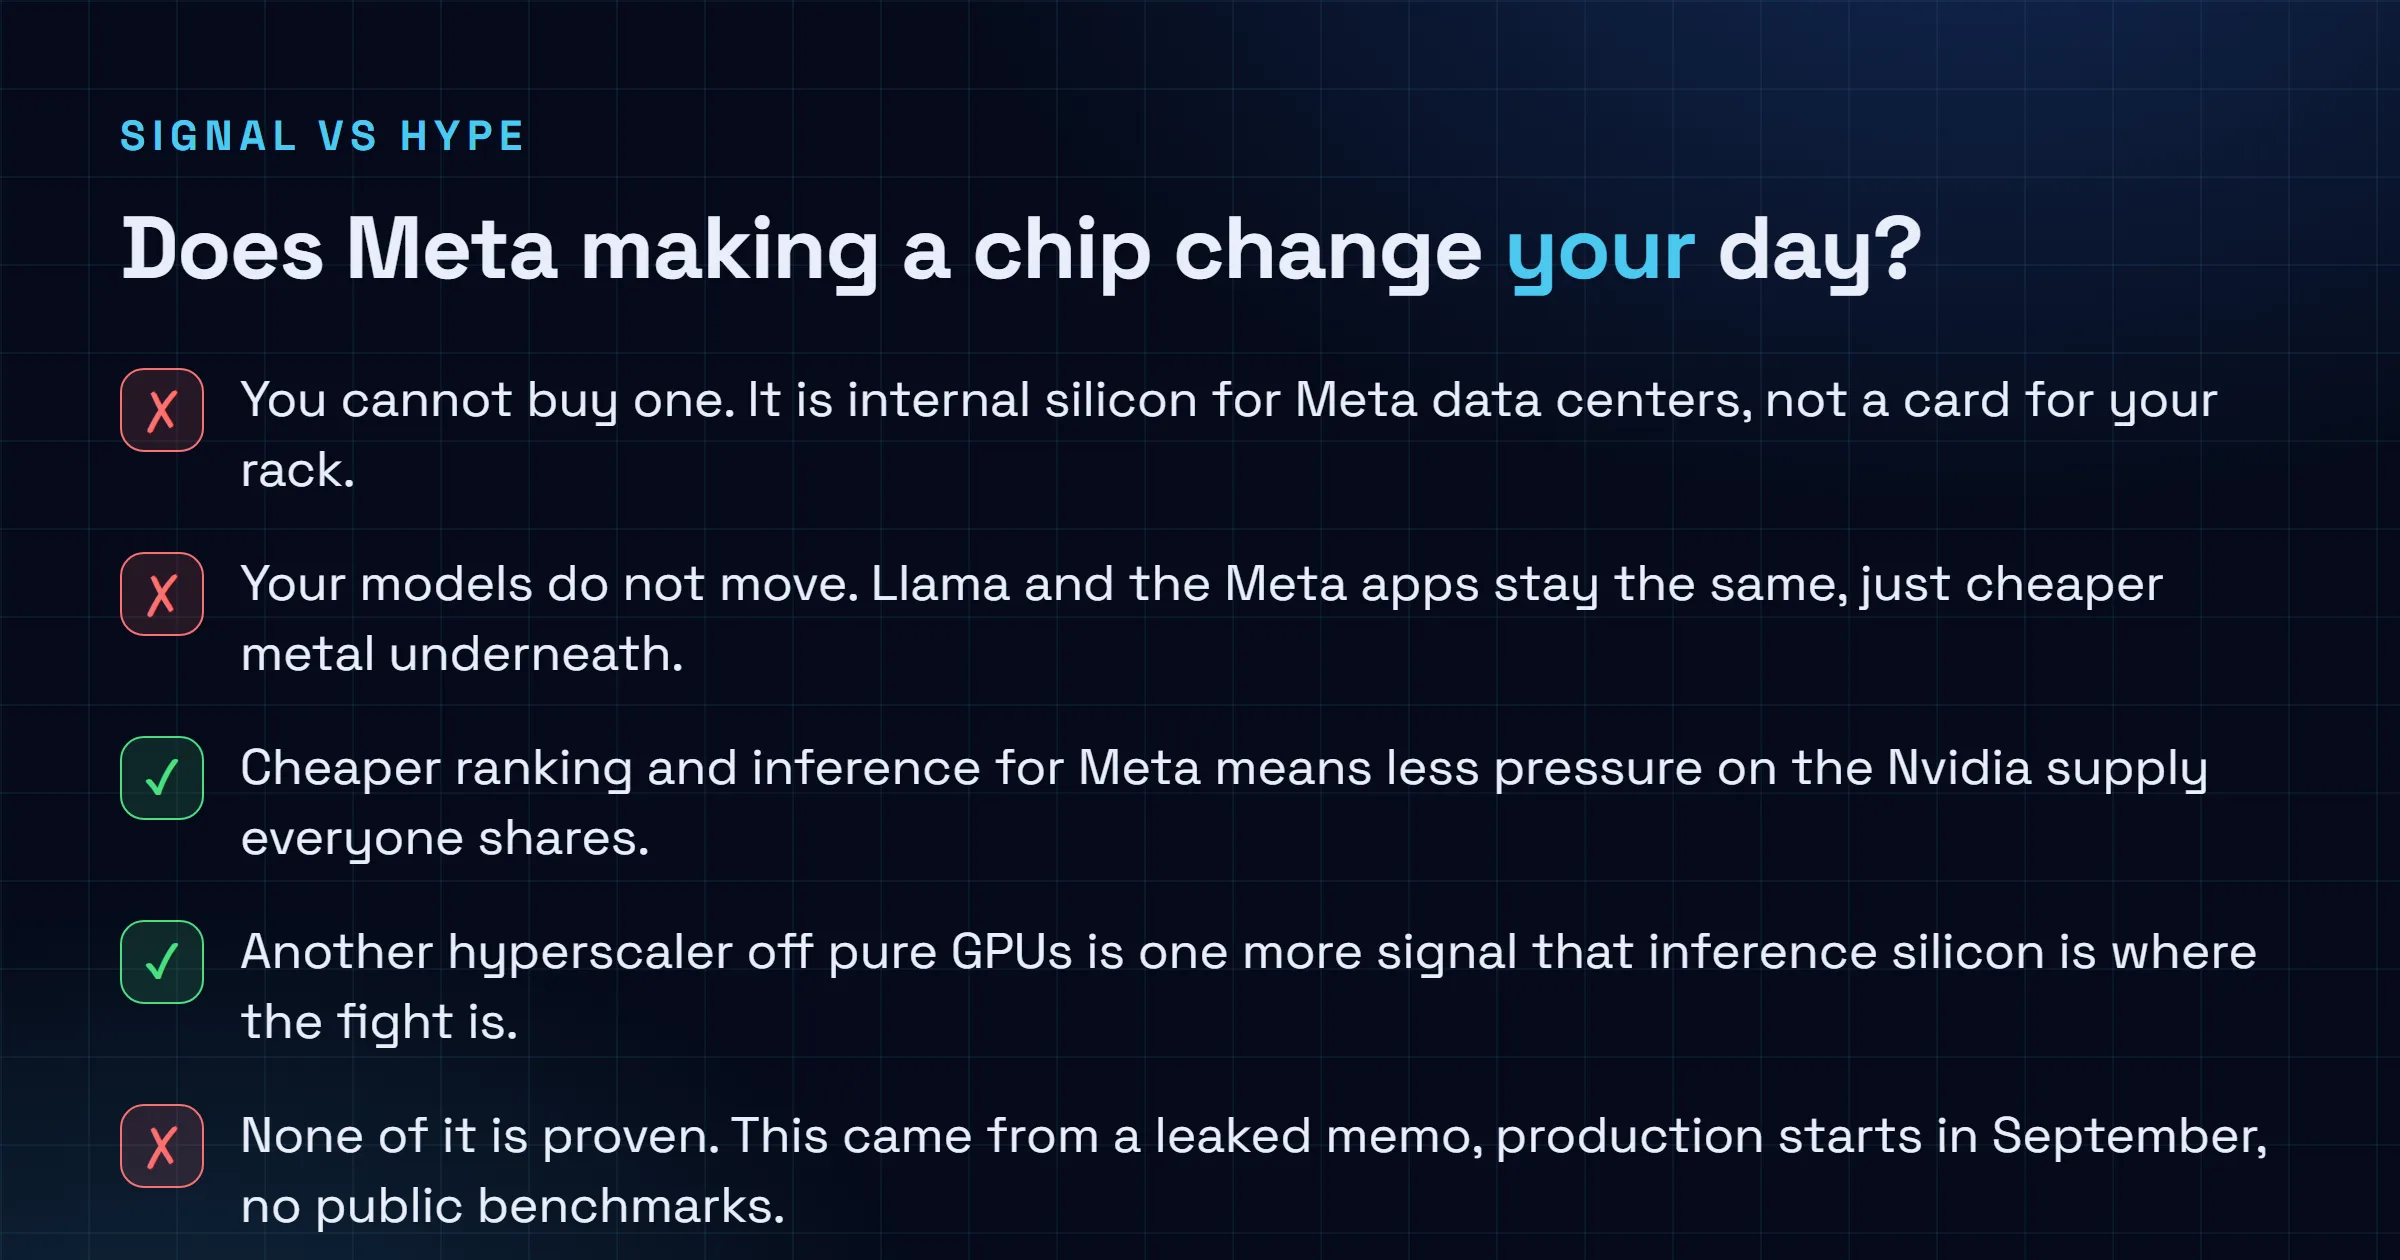
Where it could matter, slowly, is upstream of you. Every workload a hyperscaler moves off rented GPUs is a bit less demand on the same Nvidia and AMD supply that your cloud bill and your GPU lead times ride on. It’s indirect, it’s diffuse, and you’ll never see a line item for it. But when Meta, OpenAI and the rest each peel their steady inference load onto custom chips, the GPU crunch everyone complains about gets a little less brutal at the margin. That’s a 2027 story at the earliest, and it depends on Iris actually shipping in volume. Still, the direction is real.
The honest read
Iris is a supply-chain move wearing a chip’s clothes. Meta wants to own more of its own stack, spend a little less renting Nvidia’s, and it’s doing what the big clouds have quietly done for years: build custom silicon for the one workload that’s constant enough to pay for itself. Real strategy. Just not a product, and not yours to touch. So don’t re-plan anything around it, don’t read the “six weeks” or the gigawatt targets as gospel from a leaked memo, and don’t expect an Iris instance to show up in any console. Watch whether September’s production date actually holds. That’s where this either becomes a thing or stays a memo.
Sources: Reuters’ exclusive on the Iris production plan, reported via CNBC, and reporting and context from TechCrunch, July 2026. The details here come from an internal Meta memo, not a public announcement, and the timing, capacity and spending figures are not independently verified.
Frequently asked questions
What is Meta's Iris chip?
Iris is the newest chip in Meta's in-house silicon line, known internally as MTIA (Meta Training and Inference Accelerator). Broadcom is the design partner and TSMC handles fabrication. It is built mainly for Meta's ranking and recommendation systems and app inference, the always-on workloads behind Facebook and Instagram, rather than the heavy frontier-model training that still runs on Nvidia and AMD GPUs.
Can I buy a Meta Iris chip?
No. Iris is internal silicon for Meta's own data centers, not a card you can put in a server or a cloud instance you can rent. There is no consumer or enterprise product, and Meta has not announced one.
When does Iris go into production?
According to the memo reported by Reuters, volume production starts in September 2026, after one chip cleared validation testing in about six weeks with no major design issue. That is a manufacturing milestone, not live traffic, so treat deployment timing as still in progress.
Does Iris replace Nvidia GPUs?
Not really. Meta frames Iris as a complement, not a replacement, and says it still expects to spend heavily with Nvidia and AMD. The goal is to move the constant ranking and inference load onto cheaper in-house silicon while frontier training stays on rented GPUs.
How is Iris different from OpenAI's Jalapeño chip?
Both are hyperscalers building custom silicon with Broadcom to lean on Nvidia less. OpenAI's Jalapeño is a pure inference accelerator for serving its models. Meta's Iris is aimed more squarely at ranking and recommendation plus app inference, the workloads that drive its feeds. Same strategy, different target workload.


