
• Latest
  • Trending
  • All
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.

Qwen-Image-2.1 brings the weights back, but not the Apache licence

21 September 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
Answer card stating that Jev 1.13 from TypeSafe AI is a decision model in early access since 15 September 2026 that returns typed probabilities instead of text, priced at 42 dollars per billion input tokens with output tokens free, answering in 70 to 500 milliseconds, with a 64K token request budget, text input only, and a documented list of things it does badly, including counting and dates.

Jev 1.13 bills $42 a billion tokens, and it can’t count

19 September 2026
Answer card stating that Qwen3.8-Omni-Flash launched on 17 September 2026 as an API only model on Alibaba Cloud Model Studio, taking text, images, audio and video in a 1M token context and returning text only, priced at 0.15 dollars per million input tokens for every modality and 0.47 dollars per million output tokens in the international regions, with no open weights published and the Qwen-Live Harness GitHub repository returning 404.

Qwen3.8-Omni-Flash bills audio at $0.15 and ships no weights

18 September 2026
Answer card stating that on 15 September 2026 AWS said it is unable to restore access to resources and data hosted exclusively in the Middle East Bahrain region me-south-1 and in the mec1-az2 zone of the UAE region, because the damage spanned multiple Availability Zones and exceeded what multi-AZ services are designed to withstand.

AWS can’t restore me-south-1, six months after the drone strikes

17 September 2026
Answer card stating that Google released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking on 15 September 2026 at 3 dollars per million audio input tokens and 12 dollars out, that the thinking model requires asynchronous tools, and that Artificial Analysis scores it 82.6 on its Speech to Speech Quality Index.

Gemini 3.8 Live Extended Thinking rejects any tool that blocks

16 September 2026
Answer card summarising the Atria Dawn Preview release: 744B GLM-5.2 base, MIT licence, 1.5 TB BF16 and 756 GB FP8 checkpoints, 256K context, top on five of sixteen benchmark rows and trailing on SWE-bench Pro.

Atria Dawn Preview is 744B under MIT, and the BF16 weighs 1.5 TB

15 September 2026
Answer card stating that OpenAI released the Agents API in public beta on 10 September 2026 with no separate fee, billed through model tokens, tool calls and hosted sandbox time, with a choice of OpenAI hosted, self hosted or partner sandboxes, US only data residency and no Zero Data Retention support.

OpenAI’s Agents API has no fee, no ZDR and a one hour sandbox clock

14 September 2026
Answer card: Sakana Fugu Max at $2 and $6 per million tokens, Fugu Ultra v2 unchanged at $5 and $30, and Sakana saying Ultra v2 scores without Fable 5 or GPT-6 Astra in its pool.

Fugu Max costs $2 and $6 while Fugu Ultra v2 runs without Fable 5

13 September 2026
Answer card stating that DeepSeek released DeepSeek-V4.1-Flash on 10 September 2026 as a 552 billion parameter mixture of experts model with a new causal encoder decoder architecture that activates 8 billion parameters on input and 16 billion on output, with native vision, a one million token context and MIT licensed weights, that the API model name is now deepseek-flash at 0.15 dollars per million input tokens and 0.60 dollars per million output tokens off peak, and that DeepSeek announced V4 Pro would be routed to V4.1-Flash from 14 September and reversed that on 11 September.

DeepSeek V4.1-Flash arrived, and the V4 Pro retirement lasted a day

12 September 2026
Answer card stating that Cognition released SWE-2 on 10 September 2026, a coding model post-trained from Kimi K3, scoring 50.0 percent on FrontierCode 1.1 Main against 50.9 percent for Claude Fable 5.1 and 27.3 percent on Terminal-Bench 4 against 55.8 percent, available only inside Devin.

SWE-2 trails Fable 5.1 by one point, and by 28 on Terminal-Bench 4

11 September 2026
Answer card for Meta Muse, free to 100 million tokens a week then $20 a month, launched 8 September 2026 for United States adults only, running in a dedicated per user virtual machine.

Does Meta Muse do enough to earn your inbox and a card on file?

9 September 2026
Answer card stating that the public download pages for the VMware Virtual Disk Development Kit on developer.broadcom.com began returning 404 errors on 25 August 2026 with no announcement or deprecation notice, that Broadcom support tells customers the kit is no longer available for use or download, and that release lines 7.0.3.1, 8.x and 9.x are all affected.

Broadcom pulled VDDK 8.0 and 9.0, and the 404 is the only notice

8 September 2026
  • About
  • Contact
  • Privacy
  • Legal
Monday, September 21, 2026
  • Login
Packet Nebula
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About
No Result
View All Result
Packet Nebula
No Result
View All Result
Home Dev

Qwen-Image-2.1 brings the weights back, but not the Apache licence

by stephane
21 September 2026
in Dev
0
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.
491
SHARES
1.4k
VIEWS
Share on FacebookShare on Twitter

In July we wrote that Qwen-Image-3.0 was a hosted demo with no weights and no numbers, and that the whole reason anyone cared about this model line was that you could run it yourself. On 20 September 2026 the Qwen team put files back on Hugging Face. Qwen-Image-2.1 is a 7B diffusion transformer with a Qwen3-VL 8B text encoder and an RGBA autoencoder, about 33 GB in BF16, and it does text-to-image and editing in one checkpoint. So the download's back. The Apache 2.0 licence that came with Qwen-Image 1.0 isn't, and that's the part we'd read before pulling 33 GB.

The short answer

Qwen-Image-2.1 shipped on 20 September 2026 with open weights on Hugging Face and ModelScope: a 7B single-stream DiT (32 layers), a Qwen3-VL 8B encoder and a 64-channel RGBA VAE with 16x compression, native 2K output, up to 10 reference images and real transparent PNGs. Diffusers, ComfyUI, vLLM-Omni, SGLang and LightX2V supported it on day zero. The licence is the Qwen Research License Agreement: "research or evaluation purposes only", with commercial use by a separate licence you request by email. Every earlier Qwen-Image release with weights was Apache 2.0. There's no benchmark table in the model card or README, and no independent test yet.
7Bin the image transformer, 8B more in the text encoder
33 GBon disk in BF16, about 14 GB with the INT8 and W4A8 repacks
0benchmark rows in the model card, README or LICENSE
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.
Files you can download, and a licence that decides what you're allowed to do with the output.

What's actually in the 33 GB

Three parts, and the biggest one isn't the image model. The transformer is 7B parameters in 32 single-stream DiT layers, 14.2 GB in BF16 across two safetensors shards. The text encoder is a full Qwen3-VL 8B, 36 layers with a vision tower, and it's 17.5 GB on its own. It does double duty: it reads your prompt and it encodes the reference images you pass in, so there's no separate image encoder. Then a 1.35 GB VAE with a 64-channel latent, 16x spatial compression and four input channels, which is how the alpha channel gets in and out without a matting step. Add it up and you're at roughly 33 GB before you've generated anything.

For scale, the transformer in Qwen-Image 1.0 was 20B and 40.9 GB by itself. This one's a third of that. The Comfy-Org repack goes further: an INT8 transformer at 7.3 GB, an INT8 encoder at 9.4 GB or a W4A8 encoder at 6.3 GB, and a 0.7 GB VAE. Pick the small ones and the whole thing sits around 14 GB on disk. Disk isn't VRAM, though. The vLLM-Omni recipe measured 34 GB peak in BF16 at 1024x1024 and 40 steps on a single data-centre GPU, and 3.3 to 4.5 seconds an image at that size. Qwen's blog says a 3090 will run it (that's a 24 GB card, so with offload), and Diffusers ships enable_model_cpu_offload() for exactly that. One early reviewer reported about 13.9 GB peak on a 16 GB card at 1024 square with offload. We haven't reproduced that, so treat it as one data point.
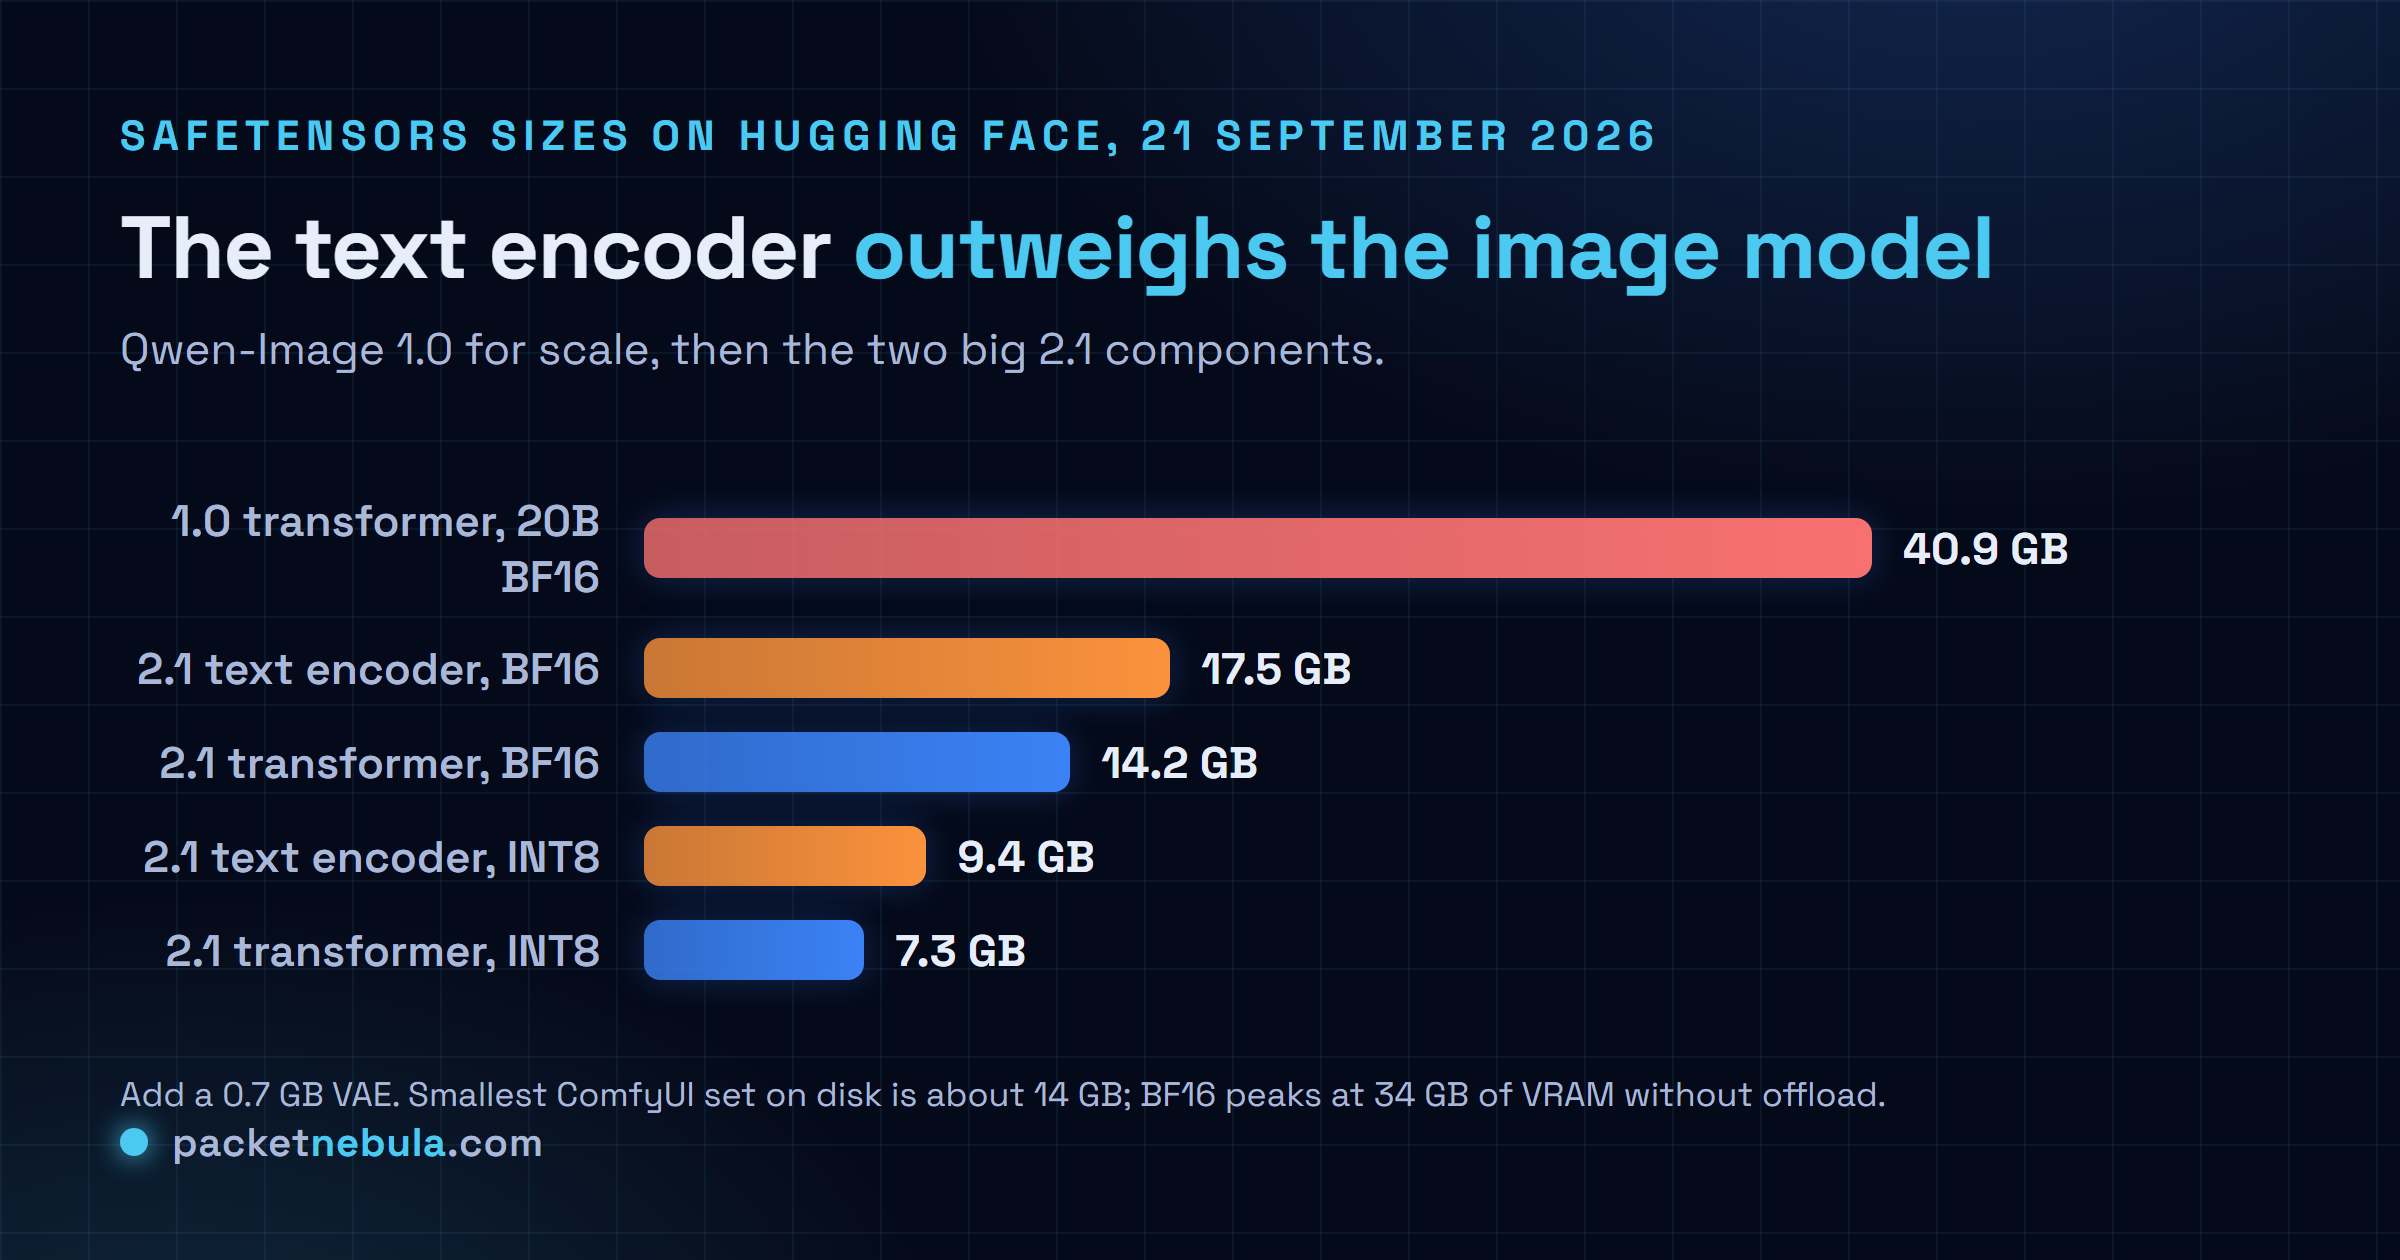
Horizontal bar chart of on-disk file sizes in gigabytes: Qwen-Image 1.0's 20B transformer at 40.9 in BF16, Qwen-Image-2.1's Qwen3-VL 8B text encoder at 17.5 in BF16, its 7B transformer at 14.2 in BF16, the text encoder at 9.4 in INT8 and the transformer at 7.3 in INT8.
The text encoder is the heavy file. Quantise that first if you're short on memory.

The features are the ones the card leads with. Native 2K, meaning 2048x2048 by default and seven fixed aspect ratios up to 2752x1536. Up to 10 reference images in one call, with local edits guided by a drawn circle or a separate mask. Transparent output from a prompt, using a slightly odd recommended phrasing ("This is an RGBA image with transparency. ... The image has alpha channel and the background is transparent."). And prefix KV cache reuse: because the attention is block-causal, the text and the reference images get encoded once at the first denoising step and reused for the other 39. The vLLM recipe puts a repeated prompt at about a third of the first submission's cost, and says four reference images leave roughly a fifth of the sequence to recompute. That's the real engineering in this release, honestly, more than the parameter count.

The licence is the story

Every Qwen-Image checkpoint we've pulled before this one was Apache 2.0. Qwen-Image (August 2025), Qwen-Image-Edit-2511 and Qwen-Image-2512 (December 2025), all of them. Qwen-Image-2.0 in February and 3.0 in July never got weights at all. So 2.1 is the first open release in the line under something else, and that something is the Qwen Research License Agreement, dated 20 September 2026 in the file itself.

The wording matters. Section 1 defines "Non-Commercial" as "for research or evaluation purposes only". Section 2 grants you the weights "FOR NON-COMMERCIAL PURPOSES ONLY" and says that if you want to use them commercially you request a separate licence at a qwencloud.com address. There's no revenue threshold, no monthly-user cutoff like the licences some other labs use. It's binary: research and evaluation, or a deal with Hangzhou Tongyi Laboratory. Section 4 adds the usual "Built with Qwen" notice if you fine-tune and redistribute, and section 8 puts disputes under Chinese law in the courts of Hangzhou. The Comfy-Org repack and the two prompt-rewriter models carry the same licence.

For a lab or a hobby box, none of that bites. For anyone who wanted to swap this into a product, it does. I might be wrong about the intent here, but the pattern reads like a lab that's decided the small open model is a funnel and the API is the product, and that's a different relationship from the one Qwen3.8-27B under Apache 2.0 offers on the language side of the same company. If you're evaluating it for commercial use, the evaluation itself is covered. Shipping it isn't, until someone writes back.
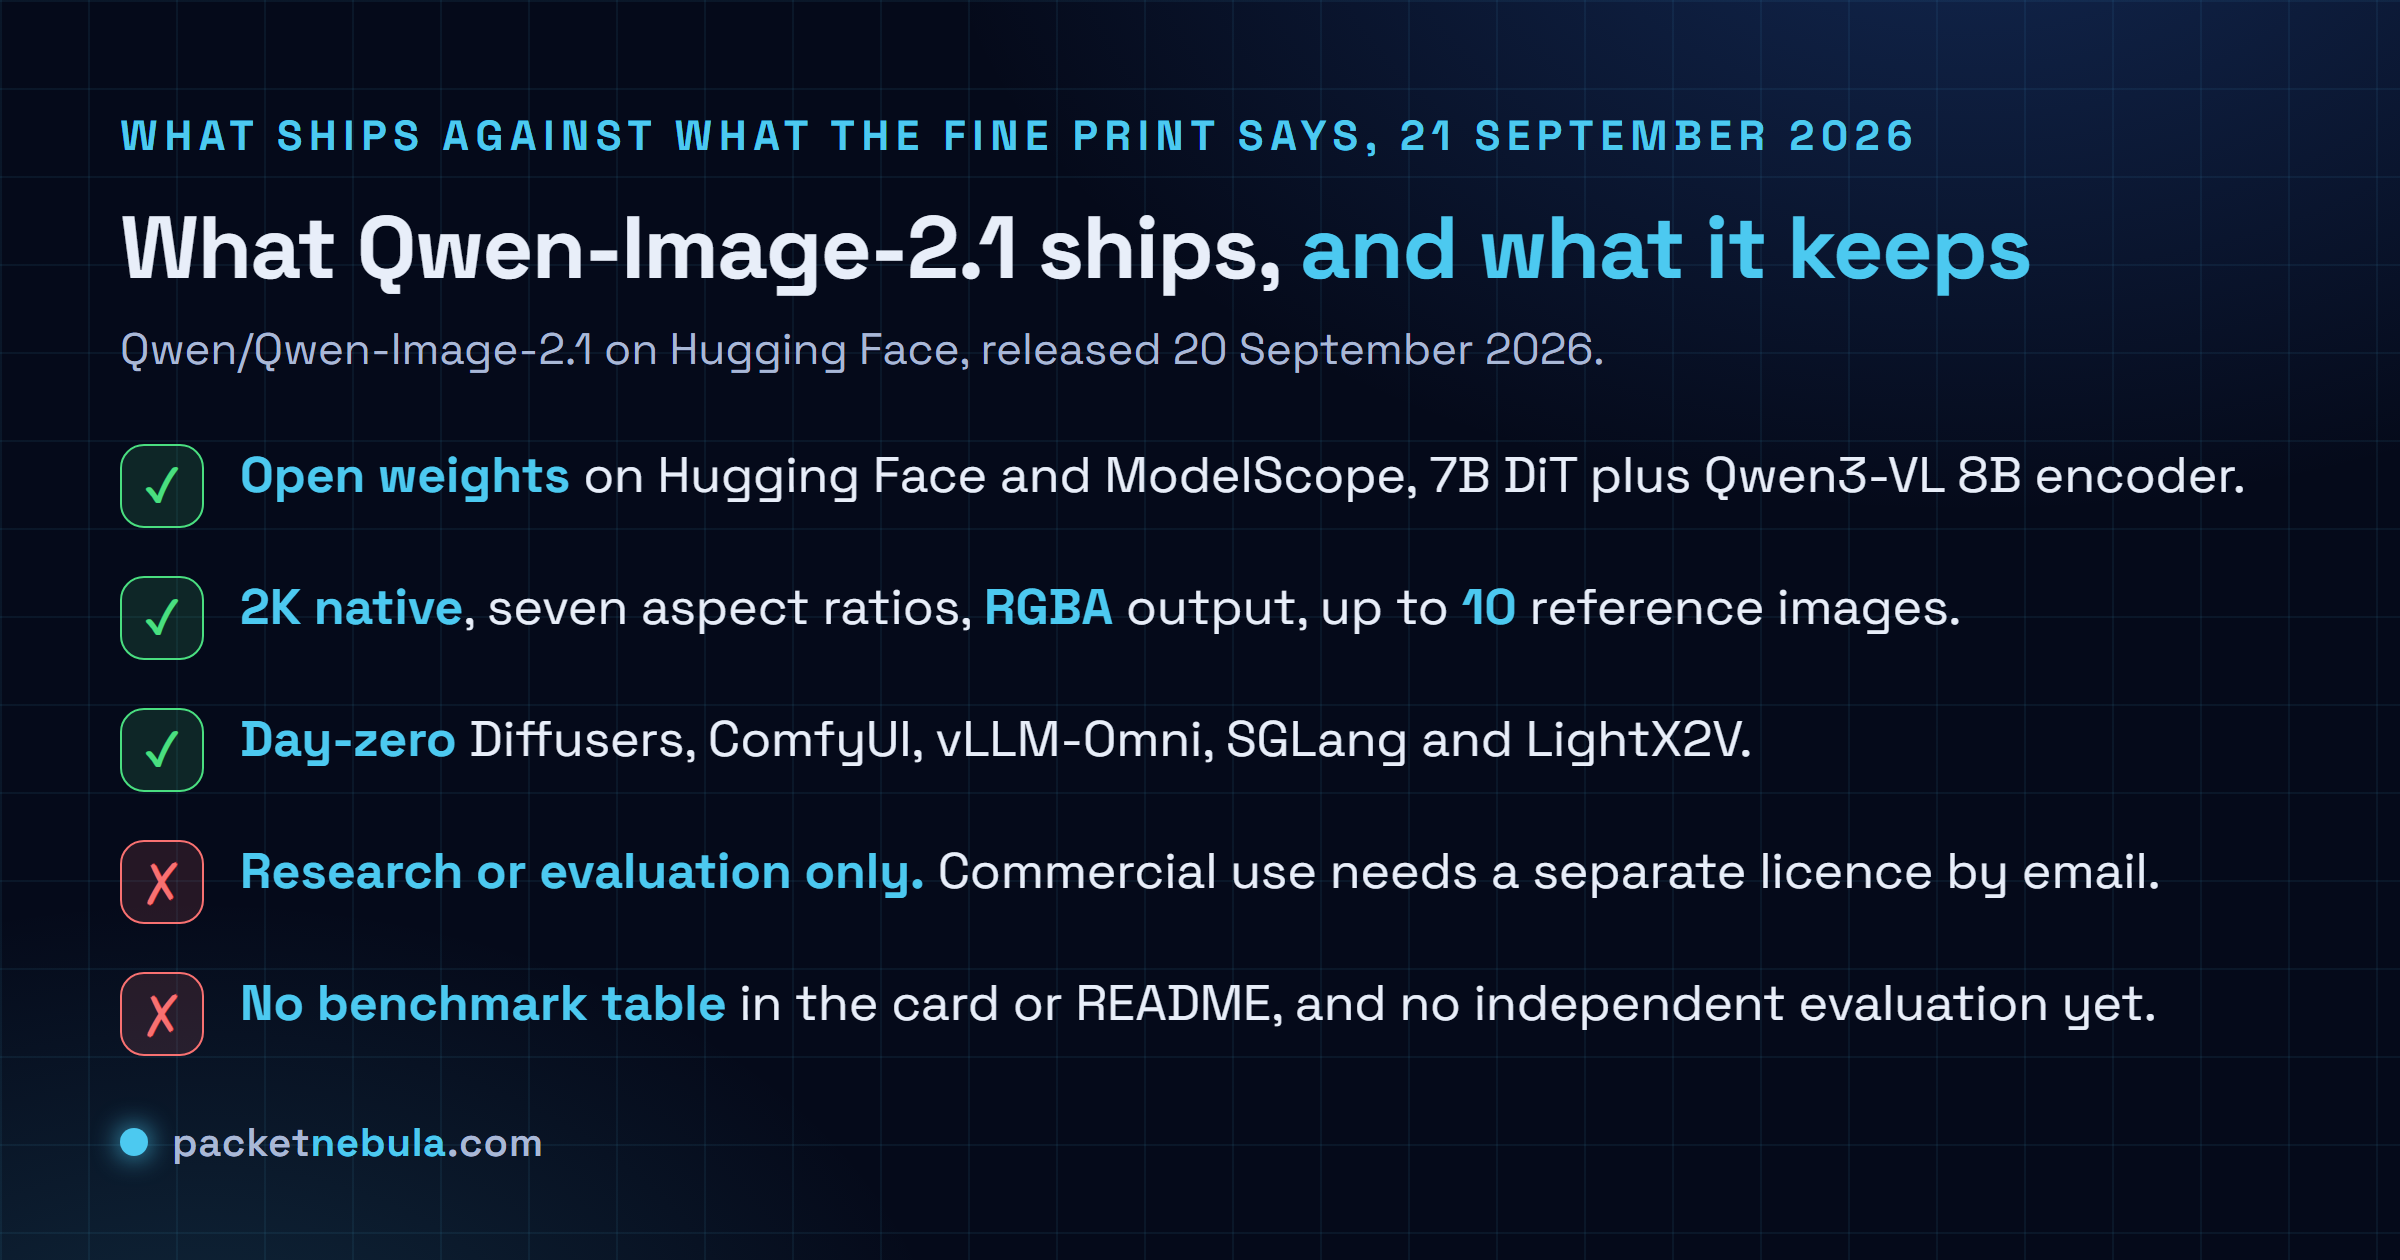
Checklist of what Qwen-Image-2.1 ships and what it withholds as of 21 September 2026: open weights on Hugging Face and ModelScope, native 2K output with seven aspect ratios and RGBA transparency, up to ten reference images, day-zero support in Diffusers, ComfyUI, vLLM-Omni, SGLang and LightX2V, against a research-only licence with commercial use by separate agreement and no benchmark table or independent evaluation yet.
Three rows from the model card and README, two from the LICENSE file and what isn't in either.

Running it, and what nobody's measured yet

Day-zero support is unusually broad. Diffusers merged a QwenImage21Pipeline (PR 14804), ComfyUI has native nodes and two template workflows, vLLM-Omni serves it behind an OpenAI-style /v1/images/generations endpoint with FP8 and prefix caching, SGLang has a cookbook, and LightX2V has a script folder. The pinned requirements are PyTorch 2.4 or newer and Transformers 5.17 or newer, with Diffusers installed from git for now.

bash
pip install "torch>=2.4.0" "transformers>=5.17" accelerate pillow && pip install git+https://github.com/huggingface/diffusers
bash
vllm serve Qwen/Qwen-Image-2.1 --omni --port 8091

The default is 40 steps at 2048x2048, which is where the 2K claim comes from. Drop to 1024 for testing, it's four times fewer latent tokens. The RGBA path saves a real four-channel PNG when the model decides the image has transparency, so check the mode of what comes back rather than assuming.

What's missing is any number you can check. The model card has no benchmark table. The GitHub README has none either. The claim that it "beats most closed models" lives in the blog post and is scored on Qwen's own benchmark, which is the same self-graded setup we flagged when 3.0 ranked itself. One day in, nobody independent has published an evaluation. Early hands-on reports mention a yellow cast and detail drift on edits, and I'd expect that to be prompt-rewriter dependent, since Qwen ships two fine-tuned 9B rewriters and clearly expects you to use them. We'll run it against the 2512 Apache build ourselves before we say anything about quality. The weights being back is good news. The licence is the thing to read first.

Sources

Hugging Face, Qwen/Qwen-Image-2.1 model card and LICENSE, read 21 September 2026 (the 7B and 32-layer figures, the aspect ratio table, the RGBA prompt format, the shard sizes, the config files for the Qwen3-VL encoder and the 64-channel VAE, the full licence text). GitHub, QwenLM/Qwen-Image-2.1 README, 20 September 2026 (the release date, the architecture section, the day-zero integrations and PR numbers, the prompt rewriters, the vLLM and SGLang commands). Hugging Face, Comfy-Org/Qwen-Image-2.1, read 21 September 2026 (the INT8 and W4A8 file sizes). vLLM, Qwen-Image-2.1 recipe, September 2026 (the 34 GB peak, the per-image timings, the prefix cache figures). The Decoder, Alibaba's open-weight Qwen-Image-2.1 claims to beat closed models, 20 September 2026 (the blog's benchmark claim and the 3090 line). Hugging Face, Qwen/Qwen-Image, Qwen-Image-2512 and Qwen-Image-Edit-2511, read 21 September 2026 (the Apache 2.0 licences and the 1.0 transformer size).

Frequently asked questions

Can we use Qwen-Image-2.1 commercially?

Not under the licence as shipped. The Qwen Research License Agreement defines non-commercial as "research or evaluation purposes only" and requires a separate commercial licence, requested by email, for anything else. There's no user or revenue threshold below which commercial use is allowed. The Comfy-Org repack and the prompt-rewriter models carry the same terms.

How much VRAM does Qwen-Image-2.1 need?

In BF16 without offload, the vLLM-Omni recipe measured 34 GB peak at 1024x1024 and 40 steps. Qwen says a 3090 (24 GB) runs it, which implies CPU offload, and Diffusers exposes enable_model_cpu_offload(). The INT8 and W4A8 repacks for ComfyUI bring the files to about 14 GB on disk. One early report puts a 16 GB card at roughly 13.9 GB peak with offload at 1024 square; we haven't confirmed that.

Is Qwen-Image-2.1 better than Qwen-Image-3.0?

Nobody outside Qwen can say yet. 3.0 is hosted-only with no weights and no published scores. 2.1 has weights but no benchmark table in its card or README; the comparison claim sits in the blog and uses Qwen's own benchmark. What's clear is that 2.1 is the one you can run, at 7B plus an 8B encoder, and 3.0 isn't.

Does it really output transparent PNGs?

Yes. The VAE has four input and output channels and a 64-channel latent, so the alpha channel is generated, not cut out afterwards. The card recommends a specific prompt wrapper ("This is an RGBA image with transparency ... the background is transparent") and the Diffusers pipeline saves RGBA when the model produces it. Semi-transparent edges are where we'd look first for artefacts.

Tags: ComfyUIimage-generationlicensingnewsopen-weightsqwenvLLM
Share196Tweet123
stephane

stephane

  • Trending
  • Comments
  • Latest
Answer card: Proton Lumo 2.0 is private by policy, not by locality. Saved history is locked so even Proton cannot read it, but the prompt is decrypted on a Proton EU server to answer it, then forgotten.

Proton Lumo 2.0 review: how private is it, really?

3 September 2026
The Agentic Coding section of the official Hy4 preview benchmark appendix published by Tencent, a table comparing Hy3 and Hy4 preview against DeepSeek V4 Pro 0813, Qwen 3.8 Max, GLM 5.3, Kimi K3, GPT 5.6 Sol and Claude Opus 5 across SWE-bench Multilingual, SWE-bench Pro, DeepSWE, three SWE Atlas tasks, SWE-Marathon, Terminal-Bench 2.1, NL2Repo-Bench, CyberGym, ProgramBench, PostTrainBench and Harbor-Index.

Tencent’s 770B Hy4 tops one benchmark row in 46

3 September 2026
Answer card: Qwen 3.7 Max is API-only and cannot run locally yet; the open Qwen models (Qwen 3.6 27B, qwen3:8b to 32b) run offline via Ollama.

Qwen 3.7 local: what you can actually run offline

22 June 2026
Answer card: JWTs are not encrypted, anyone can read them; the signature proves who issued the token, not who may read it.

Are JWTs encrypted? No, and the difference will bite you

0
Answer card: a random 8 character password falls in under 2 hours offline, while 16 random characters hold for 1.4 trillion years at the same speed.

How long does it take to crack a password in 2026?

0
Answer card: three DNS records decide if your mail lands or bounces; SPF lists allowed senders, DKIM signs messages, DMARC sets the failure policy.

SPF, DKIM and DMARC explained: the records your email needs

0
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.

Qwen-Image-2.1 brings the weights back, but not the Apache licence

21 September 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
Answer card stating that Jev 1.13 from TypeSafe AI is a decision model in early access since 15 September 2026 that returns typed probabilities instead of text, priced at 42 dollars per billion input tokens with output tokens free, answering in 70 to 500 milliseconds, with a 64K token request budget, text input only, and a documented list of things it does badly, including counting and dates.

Jev 1.13 bills $42 a billion tokens, and it can’t count

19 September 2026
  • About
  • Contact
  • Privacy
  • Legal

Copyright © 2026 Stephane Cardon.

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About

Copyright © 2026 Stephane Cardon.