
• Latest
  • Trending
  • All
Answer card: NVIDIA unveiled two new Jetson Thor modules on July 16, the T3000 at 865 FP4 teraflops with 32GB and the T2000 at 400 FP4 teraflops with 16GB, same Blackwell architecture as the T5000 at about half the size and power, both shipping in the first quarter of 2027 with no price posted.

NVIDIA Jetson T3000 and T2000: Thor for mainstream robots

17 July 2026
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.

Qwen-Image-2.1 brings the weights back, but not the Apache licence

21 September 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
Answer card stating that Jev 1.13 from TypeSafe AI is a decision model in early access since 15 September 2026 that returns typed probabilities instead of text, priced at 42 dollars per billion input tokens with output tokens free, answering in 70 to 500 milliseconds, with a 64K token request budget, text input only, and a documented list of things it does badly, including counting and dates.

Jev 1.13 bills $42 a billion tokens, and it can’t count

19 September 2026
Answer card stating that Qwen3.8-Omni-Flash launched on 17 September 2026 as an API only model on Alibaba Cloud Model Studio, taking text, images, audio and video in a 1M token context and returning text only, priced at 0.15 dollars per million input tokens for every modality and 0.47 dollars per million output tokens in the international regions, with no open weights published and the Qwen-Live Harness GitHub repository returning 404.

Qwen3.8-Omni-Flash bills audio at $0.15 and ships no weights

18 September 2026
Answer card stating that on 15 September 2026 AWS said it is unable to restore access to resources and data hosted exclusively in the Middle East Bahrain region me-south-1 and in the mec1-az2 zone of the UAE region, because the damage spanned multiple Availability Zones and exceeded what multi-AZ services are designed to withstand.

AWS can’t restore me-south-1, six months after the drone strikes

17 September 2026
Answer card stating that Google released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking on 15 September 2026 at 3 dollars per million audio input tokens and 12 dollars out, that the thinking model requires asynchronous tools, and that Artificial Analysis scores it 82.6 on its Speech to Speech Quality Index.

Gemini 3.8 Live Extended Thinking rejects any tool that blocks

16 September 2026
Answer card summarising the Atria Dawn Preview release: 744B GLM-5.2 base, MIT licence, 1.5 TB BF16 and 756 GB FP8 checkpoints, 256K context, top on five of sixteen benchmark rows and trailing on SWE-bench Pro.

Atria Dawn Preview is 744B under MIT, and the BF16 weighs 1.5 TB

15 September 2026
Answer card stating that OpenAI released the Agents API in public beta on 10 September 2026 with no separate fee, billed through model tokens, tool calls and hosted sandbox time, with a choice of OpenAI hosted, self hosted or partner sandboxes, US only data residency and no Zero Data Retention support.

OpenAI’s Agents API has no fee, no ZDR and a one hour sandbox clock

14 September 2026
Answer card: Sakana Fugu Max at $2 and $6 per million tokens, Fugu Ultra v2 unchanged at $5 and $30, and Sakana saying Ultra v2 scores without Fable 5 or GPT-6 Astra in its pool.

Fugu Max costs $2 and $6 while Fugu Ultra v2 runs without Fable 5

13 September 2026
Answer card stating that DeepSeek released DeepSeek-V4.1-Flash on 10 September 2026 as a 552 billion parameter mixture of experts model with a new causal encoder decoder architecture that activates 8 billion parameters on input and 16 billion on output, with native vision, a one million token context and MIT licensed weights, that the API model name is now deepseek-flash at 0.15 dollars per million input tokens and 0.60 dollars per million output tokens off peak, and that DeepSeek announced V4 Pro would be routed to V4.1-Flash from 14 September and reversed that on 11 September.

DeepSeek V4.1-Flash arrived, and the V4 Pro retirement lasted a day

12 September 2026
Answer card stating that Cognition released SWE-2 on 10 September 2026, a coding model post-trained from Kimi K3, scoring 50.0 percent on FrontierCode 1.1 Main against 50.9 percent for Claude Fable 5.1 and 27.3 percent on Terminal-Bench 4 against 55.8 percent, available only inside Devin.

SWE-2 trails Fable 5.1 by one point, and by 28 on Terminal-Bench 4

11 September 2026
Answer card for Meta Muse, free to 100 million tokens a week then $20 a month, launched 8 September 2026 for United States adults only, running in a dedicated per user virtual machine.

Does Meta Muse do enough to earn your inbox and a card on file?

9 September 2026
  • About
  • Contact
  • Privacy
  • Legal
Monday, September 21, 2026
  • Login
Packet Nebula
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About
No Result
View All Result
Packet Nebula
No Result
View All Result
Home Dev

NVIDIA Jetson T3000 and T2000: Thor for mainstream robots

by stephane
17 July 2026
in Dev
0
Answer card: NVIDIA unveiled two new Jetson Thor modules on July 16, the T3000 at 865 FP4 teraflops with 32GB and the T2000 at 400 FP4 teraflops with 16GB, same Blackwell architecture as the T5000 at about half the size and power, both shipping in the first quarter of 2027 with no price posted.
496
SHARES
1.4k
VIEWS
Share on FacebookShare on Twitter

So Jensen Huang stands on a stage in Japan holding a module smaller than a paperback, and that's the actual news. On July 16 NVIDIA added two chips to its Jetson Thor line, the T3000 and the T2000, and they're the cheap seats. Same Blackwell architecture as last year's flagship T5000, scaled down hard. The T2000 does 400 FP4 teraflops in 16GB of memory. The T3000 doubles that to 865 in 32GB, and both drop to about half the size and power of the top module. The pitch is putting Thor-class robot brains into machines that could never justify a 3,499 dollar dev kit. Here's the catch we'd lead with, though. Neither one ships until the first quarter of 2027, and NVIDIA hasn't posted a price. So this is a roadmap you can plan against, not a module you can order tonight.

The short answer

NVIDIA added two cheaper, smaller modules to its Jetson Thor robotics line, the T3000 and the T2000. Same Blackwell architecture as the flagship, roughly half the size and power. They target robots that could never fit the top module. The near-term effect on your work is zero: nothing ships before Q1 2027, and there’s no price yet. The real signal is Thor-class compute heading downmarket.
July 16announced in Japan
865 / 400T3000 / T2000 FP4 TFLOPS
Q1 2027availability, price TBD
Answer card: NVIDIA unveiled two new Jetson Thor modules on July 16, the T3000 at 865 FP4 teraflops with 32GB and the T2000 at 400 FP4 teraflops with 16GB, same Blackwell architecture as the T5000 at about half the size and power, both shipping in the first quarter of 2027 with no price posted.
The one-card version. Two shrunk-down Thor modules, a Q1 2027 date, and a price NVIDIA hasn't named.

What NVIDIA actually shipped (on paper)

Let’s be precise about what got announced, because “new Jetson” covers a lot of ground. This isn’t a new architecture. It’s the same Thor generation and the same Blackwell GPU that landed in the T5000 and T4000 modules back in August 2025, cut down into two smaller parts. NVIDIA is calling them the mainstream tier.
Two green industrial robotic arms reach in from the edges of a bright frame, one gripper holding up a small NVIDIA Jetson module against a soft backlit background.
Image: NVIDIA

Here are the numbers that matter. The T3000 runs a 1536-core Blackwell GPU paired with an 8-core Arm Neoverse-V3AE CPU, 32GB of LPDDR5X at 273 GB/s, and 25GbE networking, for 865 FP4 teraflops. The T2000 steps down to a 1024-core GPU, a 6-core CPU, 16GB of LPDDR5X at 137 GB/s, and dual 10GbE, landing at 400 FP4 teraflops. Both come in a module roughly half the physical size of the T4000 and T5000, and NVIDIA says the T3000 draws about half the power of the flagship.

The headline claim is the interesting one. NVIDIA says the T3000 reaches similar inference performance to the T5000 on multimodal workloads, despite having a fraction of the raw teraflops and a quarter of the memory. That’s plausible for the right models. It’s also NVIDIA’s own claim with no benchmark table attached yet, so file it under “promising, unverified.”
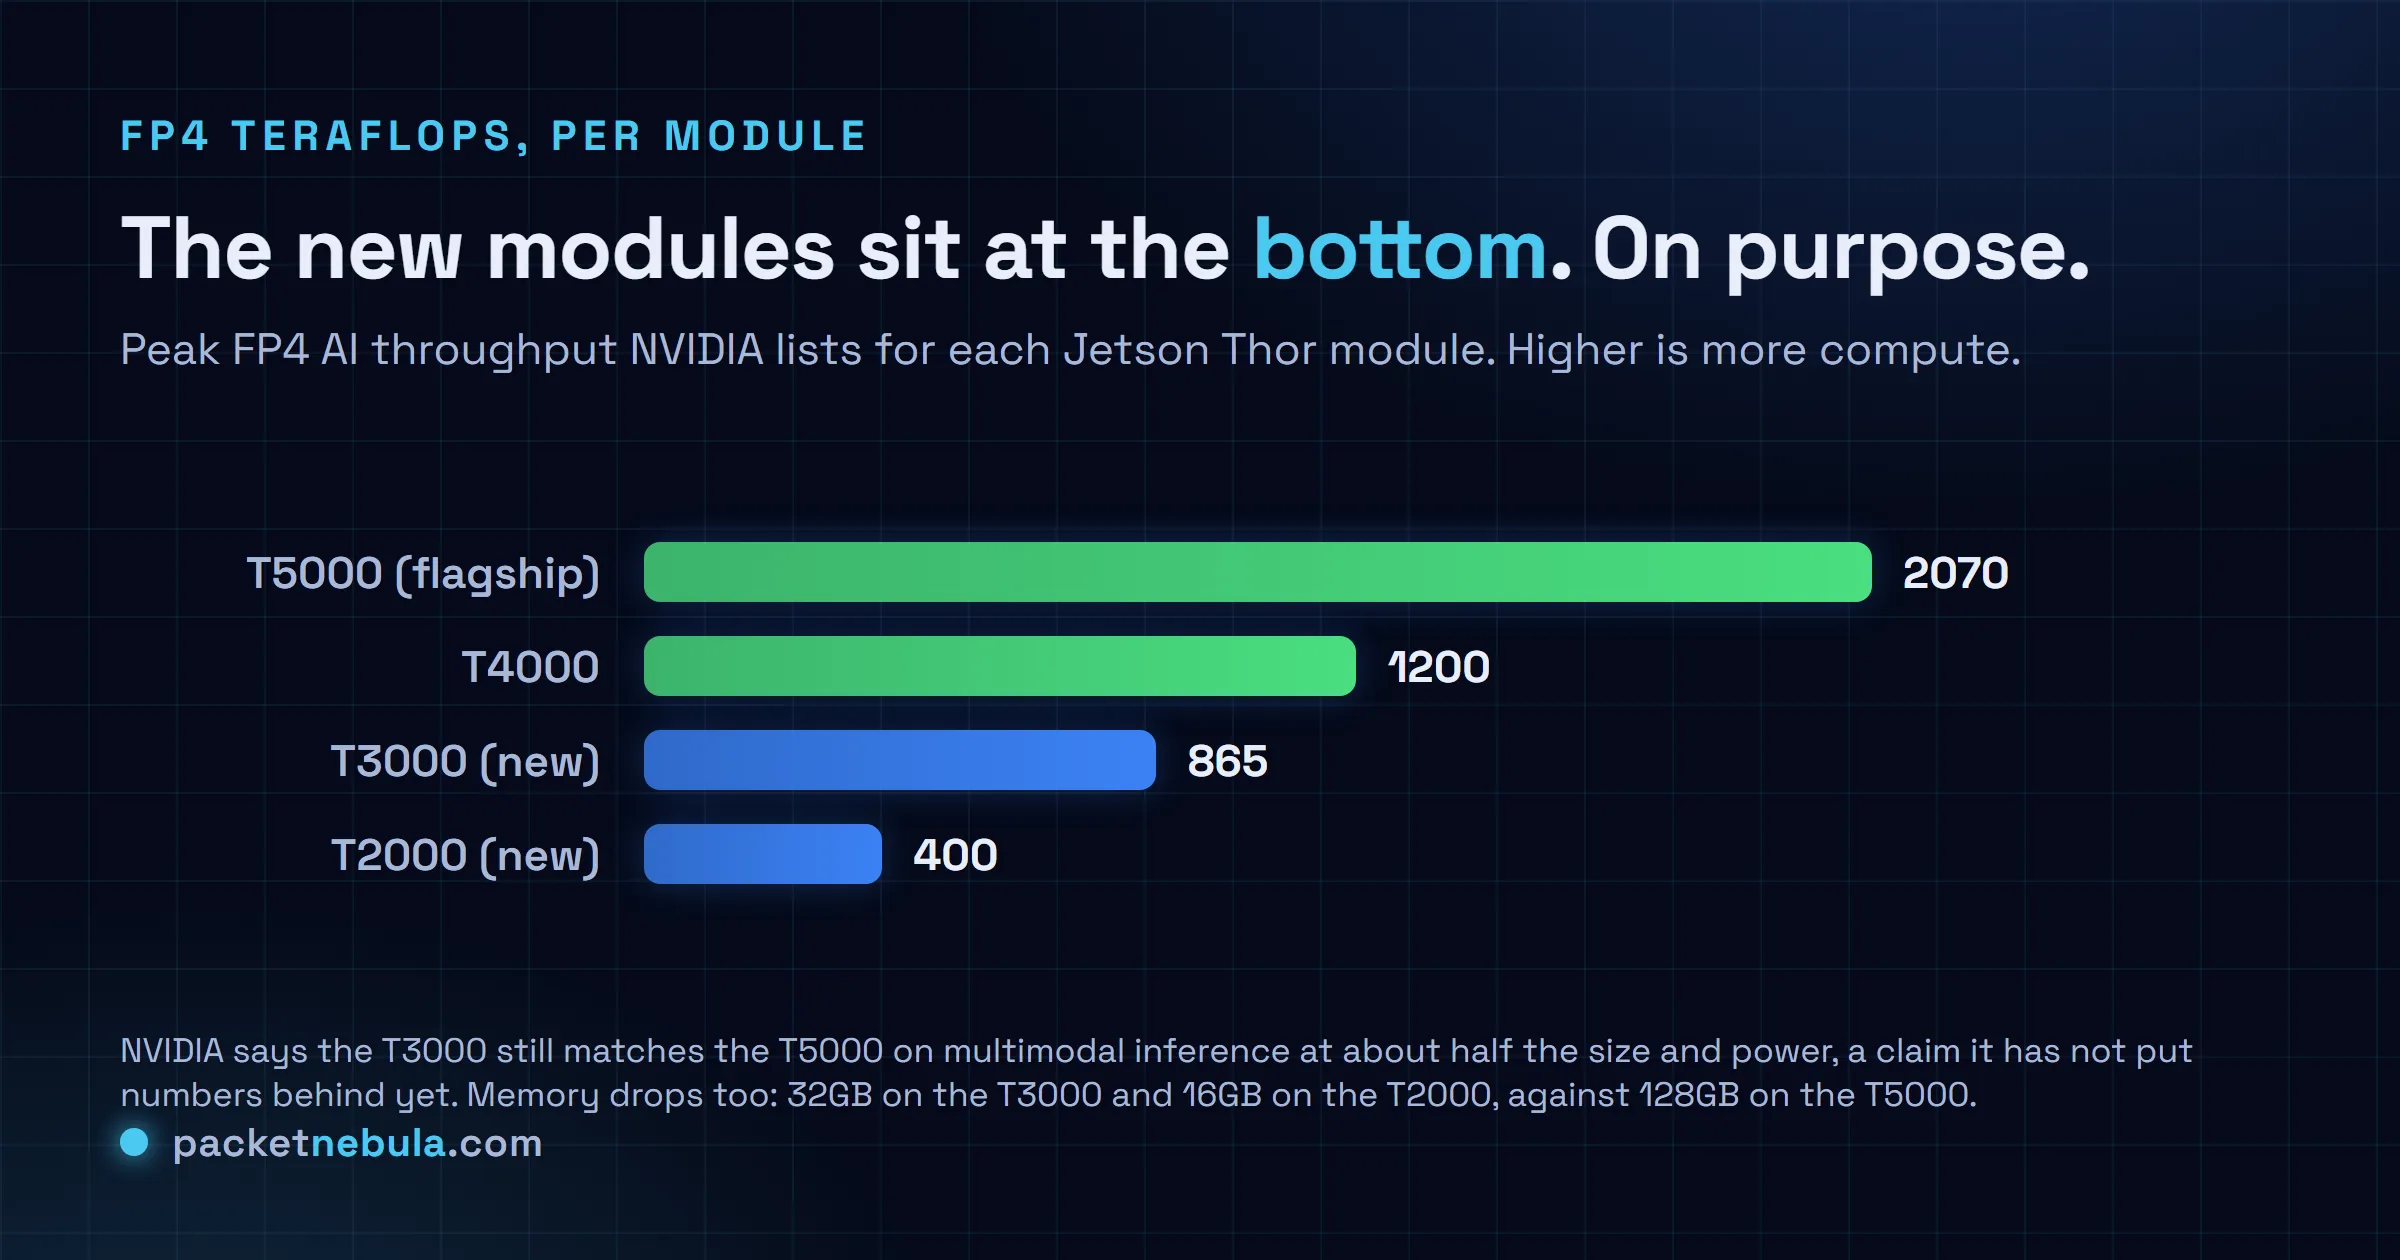
Bar chart of the Jetson Thor lineup by FP4 teraflops: T5000 at 2070, T4000 at 1200, T3000 at 865, T2000 at 400. The two new mainstream modules sit at the bottom of the throughput range.
Raw throughput across the Thor family. The two new modules sit at the bottom on purpose.

Look at where the new parts fall and the strategy reads itself. On raw FP4 throughput they’re the bottom of the range. That’s the whole design goal. NVIDIA says the Jetson portfolio now spans from about 70 TOPS on the old Orin Nano up to 2,000 teraflops on the T5000, and the T2000 and T3000 fill the fat middle where most actual robots live. Not every autonomous mobile robot or inspection drone needs a 128GB, 2070-teraflop brain. Most of them, honestly, can’t fit one or power it.

The catch: Q1 2027, and no price

Now the part the excitement tends to skip. Neither module ships until the first quarter of 2027. This is a preview, not a product on a shelf. And NVIDIA didn’t publish a price for either the T3000 or the T2000, which is a strange gap for a launch whose entire story is “cheaper.”

That price silence matters more than it looks. The word “mainstream” is doing heavy lifting in every writeup, this one included, and it’s a promise about cost that NVIDIA hasn’t put a number on. The T5000-class dev kit runs 3,499 dollars today. A mainstream module needs to land well under that to mean anything to the robotics shops NVIDIA is courting. Until we see the sticker, “affordable Thor” is a direction, not a fact.

There’s a bridge for builders, at least. NVIDIA says you can use the existing Jetson AGX Thor developer kit, on sale since last summer, to emulate the T2000 and T3000 and start writing software now. The whole Jetson line shares one CUDA and software stack, so the work isn’t wasted while you wait out the calendar. If you’re prototyping a robot that ships in 2027 anyway, that lines up.

What it changes for you

Depends who you are, and the honest answer for most readers is “not much this year.”
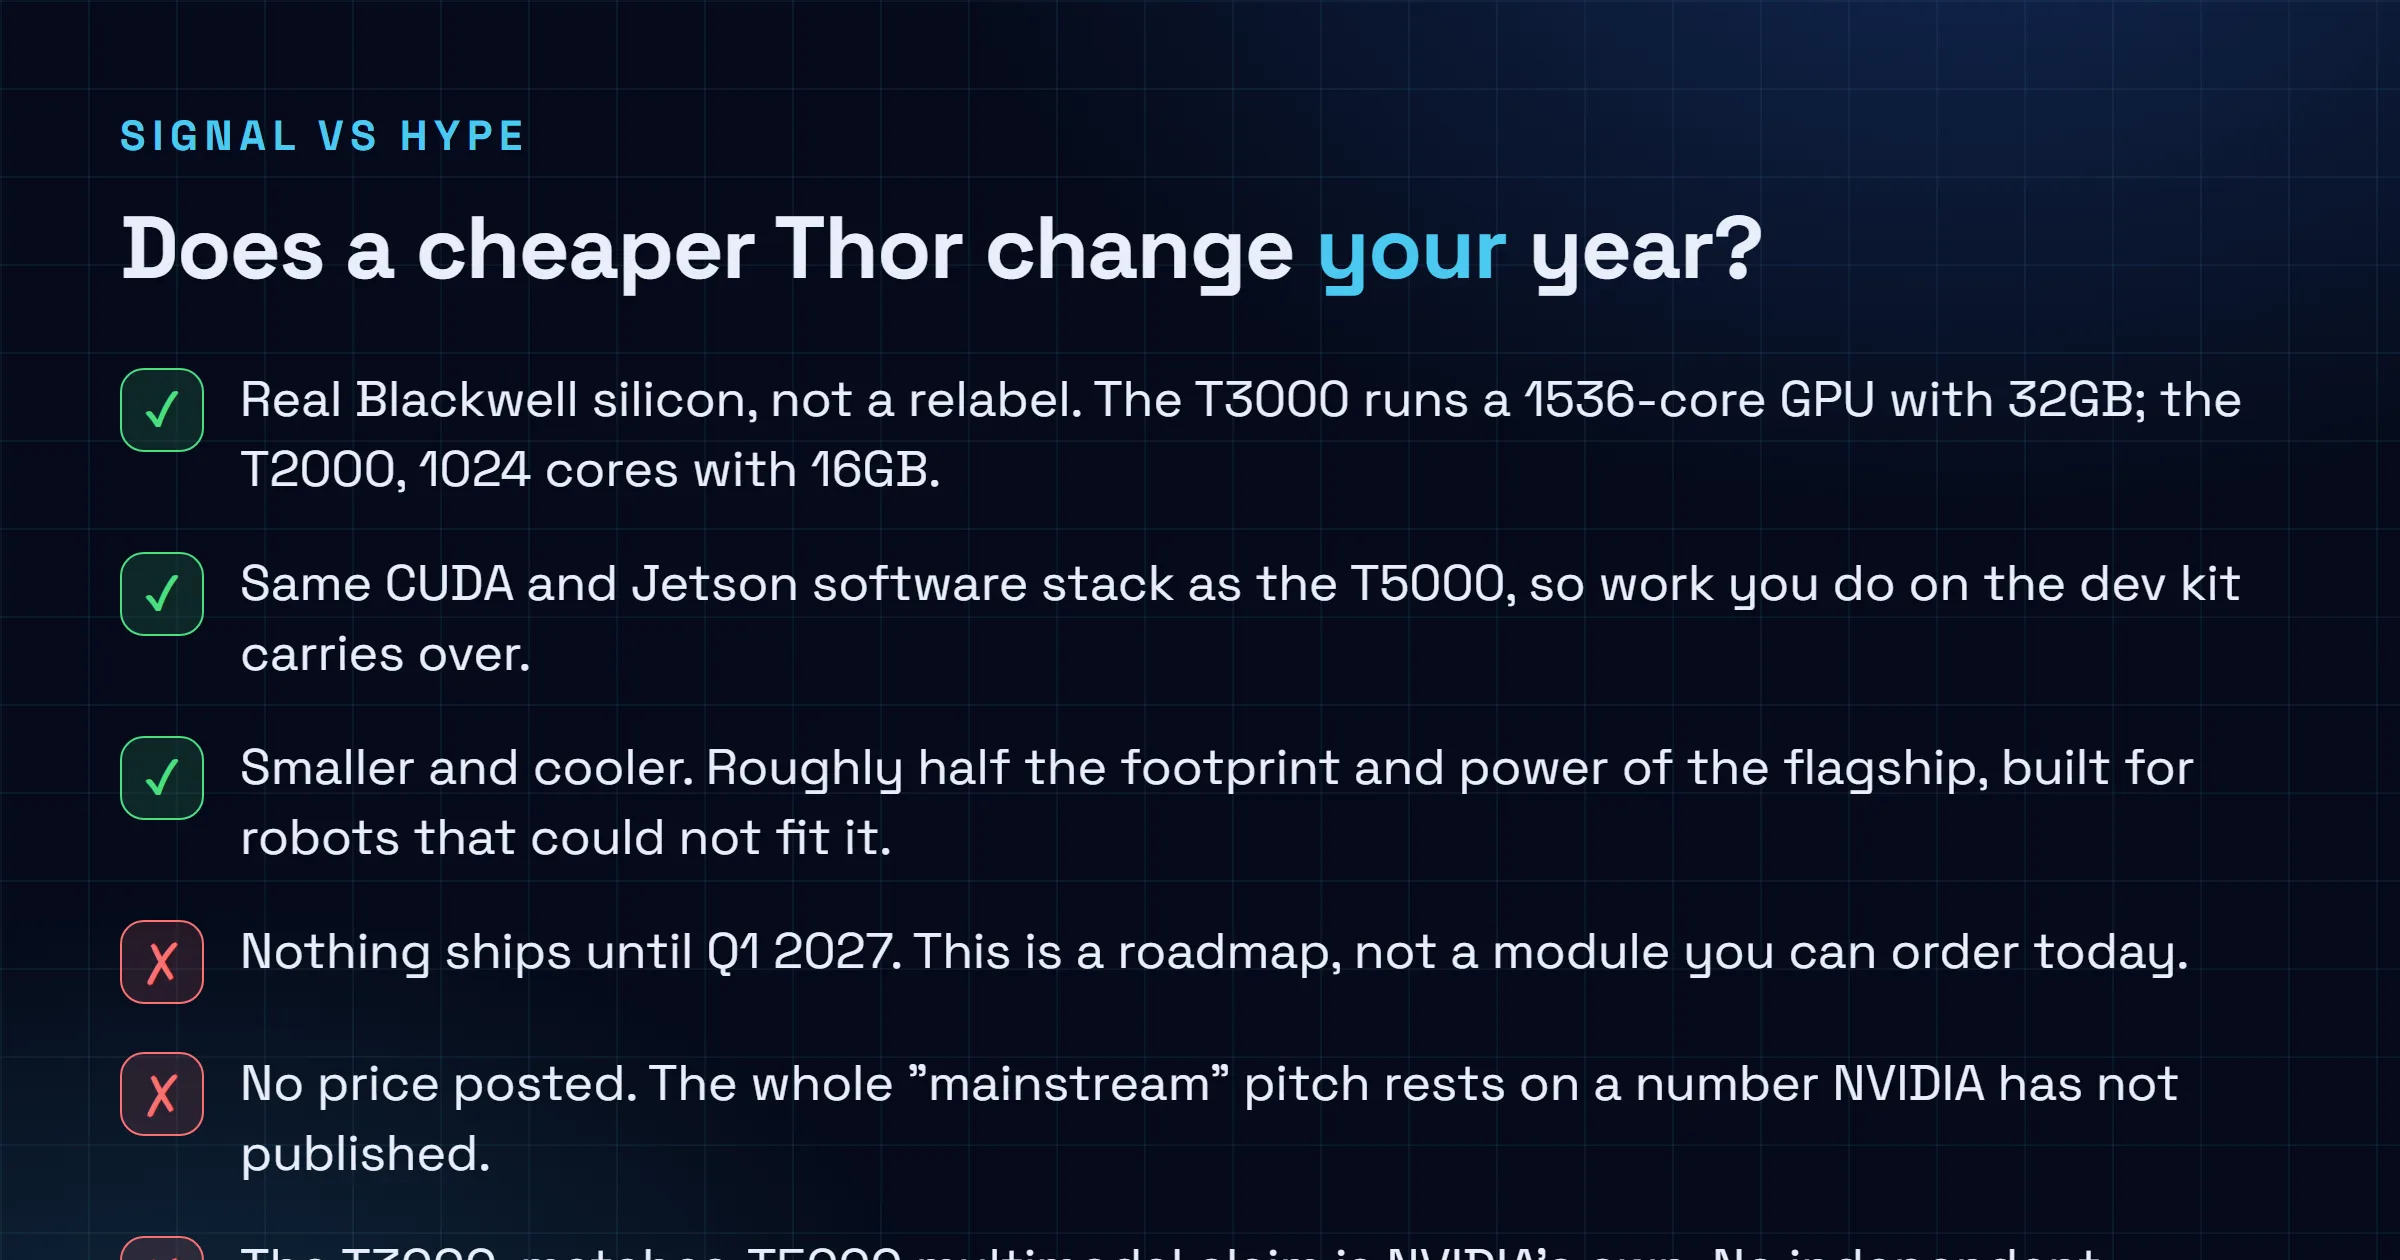
Checklist of what NVIDIA's mainstream Jetson modules change: real Blackwell silicon and the same software stack are wins you can build on, but nothing ships before Q1 2027, no price is posted, and the T3000-matches-T5000 claim is unverified.
The split between what's solid here and what stays hype until the modules ship with a price.

If you build robots or edge vision systems, this is a genuine plan-ahead signal. Thor-class multimodal inference is coming to a smaller, cooler, presumably cheaper package, and you can start on the dev kit today. That’s real, and it’s the kind of thing that changes a 2027 bill of materials. If you don’t build hardware, this is upstream weather. It’s the same trend we’ve tracked with hyperscalers moving inference onto custom silicon like Meta’s Iris chip: compute getting cheaper and more specialized at every tier, which eventually softens the GPU supply crunch that inflates everyone’s cloud costs. Diffuse, slow, but real.

One caveat worth sitting with. The memory numbers are the quiet ceiling. 16GB on the T2000 and 32GB on the T3000 are healthy for an edge device, but on-robot vision-language-action models are hungry, and 16GB fills up fast once you’re running perception and a language model together. The T3000’s 32GB is the more comfortable target for anything ambitious. Spec for the model you actually want to run, not the teraflops headline.

The honest read

The T3000 and T2000 are NVIDIA doing the obvious, sensible thing: taking a flagship robot chip and shrinking it until it fits the market that’s actually buying robots. No new magic, no new architecture, just Thor scaled down to where the volume is. That’s a good move, and the demand is clearly there.

Just don’t confuse a slide with a shipment. There’s no price, nothing ships for two quarters, and the one bold performance claim doesn’t have numbers behind it yet. If you’re building physical AI, grab the dev kit and start now. Everyone else can note the direction and check back when NVIDIA finally tells us what “mainstream” costs. That’s the number that turns this from a keynote into a product.

Sources: NVIDIA’s own announcement, reported on the NVIDIA blog, with the full spec breakdown from CNX Software and ServeTheHome, July 2026. Availability and specs come from NVIDIA; pricing was not disclosed, and the T3000-versus-T5000 multimodal claim has not been independently benchmarked.

Frequently asked questions

What are the NVIDIA Jetson T3000 and T2000?

They are two new modules in NVIDIA's Jetson Thor family for robotics and edge AI, announced on July 16, 2026. Both use the same Blackwell GPU architecture as the existing T4000 and T5000 but in a smaller, lower-power package. The T3000 delivers 865 FP4 teraflops with a 1536-core GPU and 32GB of LPDDR5X memory. The T2000 delivers 400 FP4 teraflops with a 1024-core GPU and 16GB. NVIDIA positions them as the mainstream tier, meant to put Thor-class compute into robots that could not fit or afford the flagship.

When are the Jetson T3000 and T2000 available, and how much do they cost?

NVIDIA says both modules are scheduled for the first quarter of 2027. As of the July 16 announcement, no price has been published for either one. Since the entire mainstream pitch rests on cost, that missing number is the single biggest open question. Until it lands, treat the launch as a roadmap, not a buying decision.

How do the T3000 and T2000 compare to the T4000 and T5000?

On raw throughput they sit lower: 2070 FP4 teraflops on the T5000, 1200 on the T4000, 865 on the T3000, 400 on the T2000. Memory drops too, from 128GB on the T5000 to 32GB on the T3000 and 16GB on the T2000. The trade is size and power. NVIDIA says the T3000 is roughly half the footprint and power of the T5000 while claiming similar multimodal inference performance, though it has not published numbers behind that claim yet.

Can I build for the Jetson T3000 and T2000 before they ship?

Yes. NVIDIA says developers can use the existing Jetson AGX Thor developer kit, which has been on sale since August 2025 at 3,499 dollars, to emulate the performance of the new modules. Because the whole Jetson line shares one CUDA and software stack, code and models you build on the dev kit are meant to carry over to the T3000 and T2000 when they arrive.

What are these modules actually for?

Physical AI at the edge. NVIDIA names humanoid robots, autonomous mobile robots, industrial arms and visual AI agents as the targets. The idea is to run vision-language-action models and multimodal inference on the robot itself, without a tether to a data center. The mainstream modules exist so that use case does not require the biggest, most expensive Jetson.

Tags: aiedge-aihardwarejetsonnewsnvidiarobotics
Share198Tweet124
stephane

stephane

  • Trending
  • Comments
  • Latest
Answer card: Proton Lumo 2.0 is private by policy, not by locality. Saved history is locked so even Proton cannot read it, but the prompt is decrypted on a Proton EU server to answer it, then forgotten.

Proton Lumo 2.0 review: how private is it, really?

3 September 2026
The Agentic Coding section of the official Hy4 preview benchmark appendix published by Tencent, a table comparing Hy3 and Hy4 preview against DeepSeek V4 Pro 0813, Qwen 3.8 Max, GLM 5.3, Kimi K3, GPT 5.6 Sol and Claude Opus 5 across SWE-bench Multilingual, SWE-bench Pro, DeepSWE, three SWE Atlas tasks, SWE-Marathon, Terminal-Bench 2.1, NL2Repo-Bench, CyberGym, ProgramBench, PostTrainBench and Harbor-Index.

Tencent’s 770B Hy4 tops one benchmark row in 46

3 September 2026
Answer card: Qwen 3.7 Max is API-only and cannot run locally yet; the open Qwen models (Qwen 3.6 27B, qwen3:8b to 32b) run offline via Ollama.

Qwen 3.7 local: what you can actually run offline

22 June 2026
Answer card: JWTs are not encrypted, anyone can read them; the signature proves who issued the token, not who may read it.

Are JWTs encrypted? No, and the difference will bite you

0
Answer card: a random 8 character password falls in under 2 hours offline, while 16 random characters hold for 1.4 trillion years at the same speed.

How long does it take to crack a password in 2026?

0
Answer card: three DNS records decide if your mail lands or bounces; SPF lists allowed senders, DKIM signs messages, DMARC sets the failure policy.

SPF, DKIM and DMARC explained: the records your email needs

0
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.

Qwen-Image-2.1 brings the weights back, but not the Apache licence

21 September 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
Answer card stating that Jev 1.13 from TypeSafe AI is a decision model in early access since 15 September 2026 that returns typed probabilities instead of text, priced at 42 dollars per billion input tokens with output tokens free, answering in 70 to 500 milliseconds, with a 64K token request budget, text input only, and a documented list of things it does badly, including counting and dates.

Jev 1.13 bills $42 a billion tokens, and it can’t count

19 September 2026
  • About
  • Contact
  • Privacy
  • Legal

Copyright © 2026 Stephane Cardon.

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About

Copyright © 2026 Stephane Cardon.