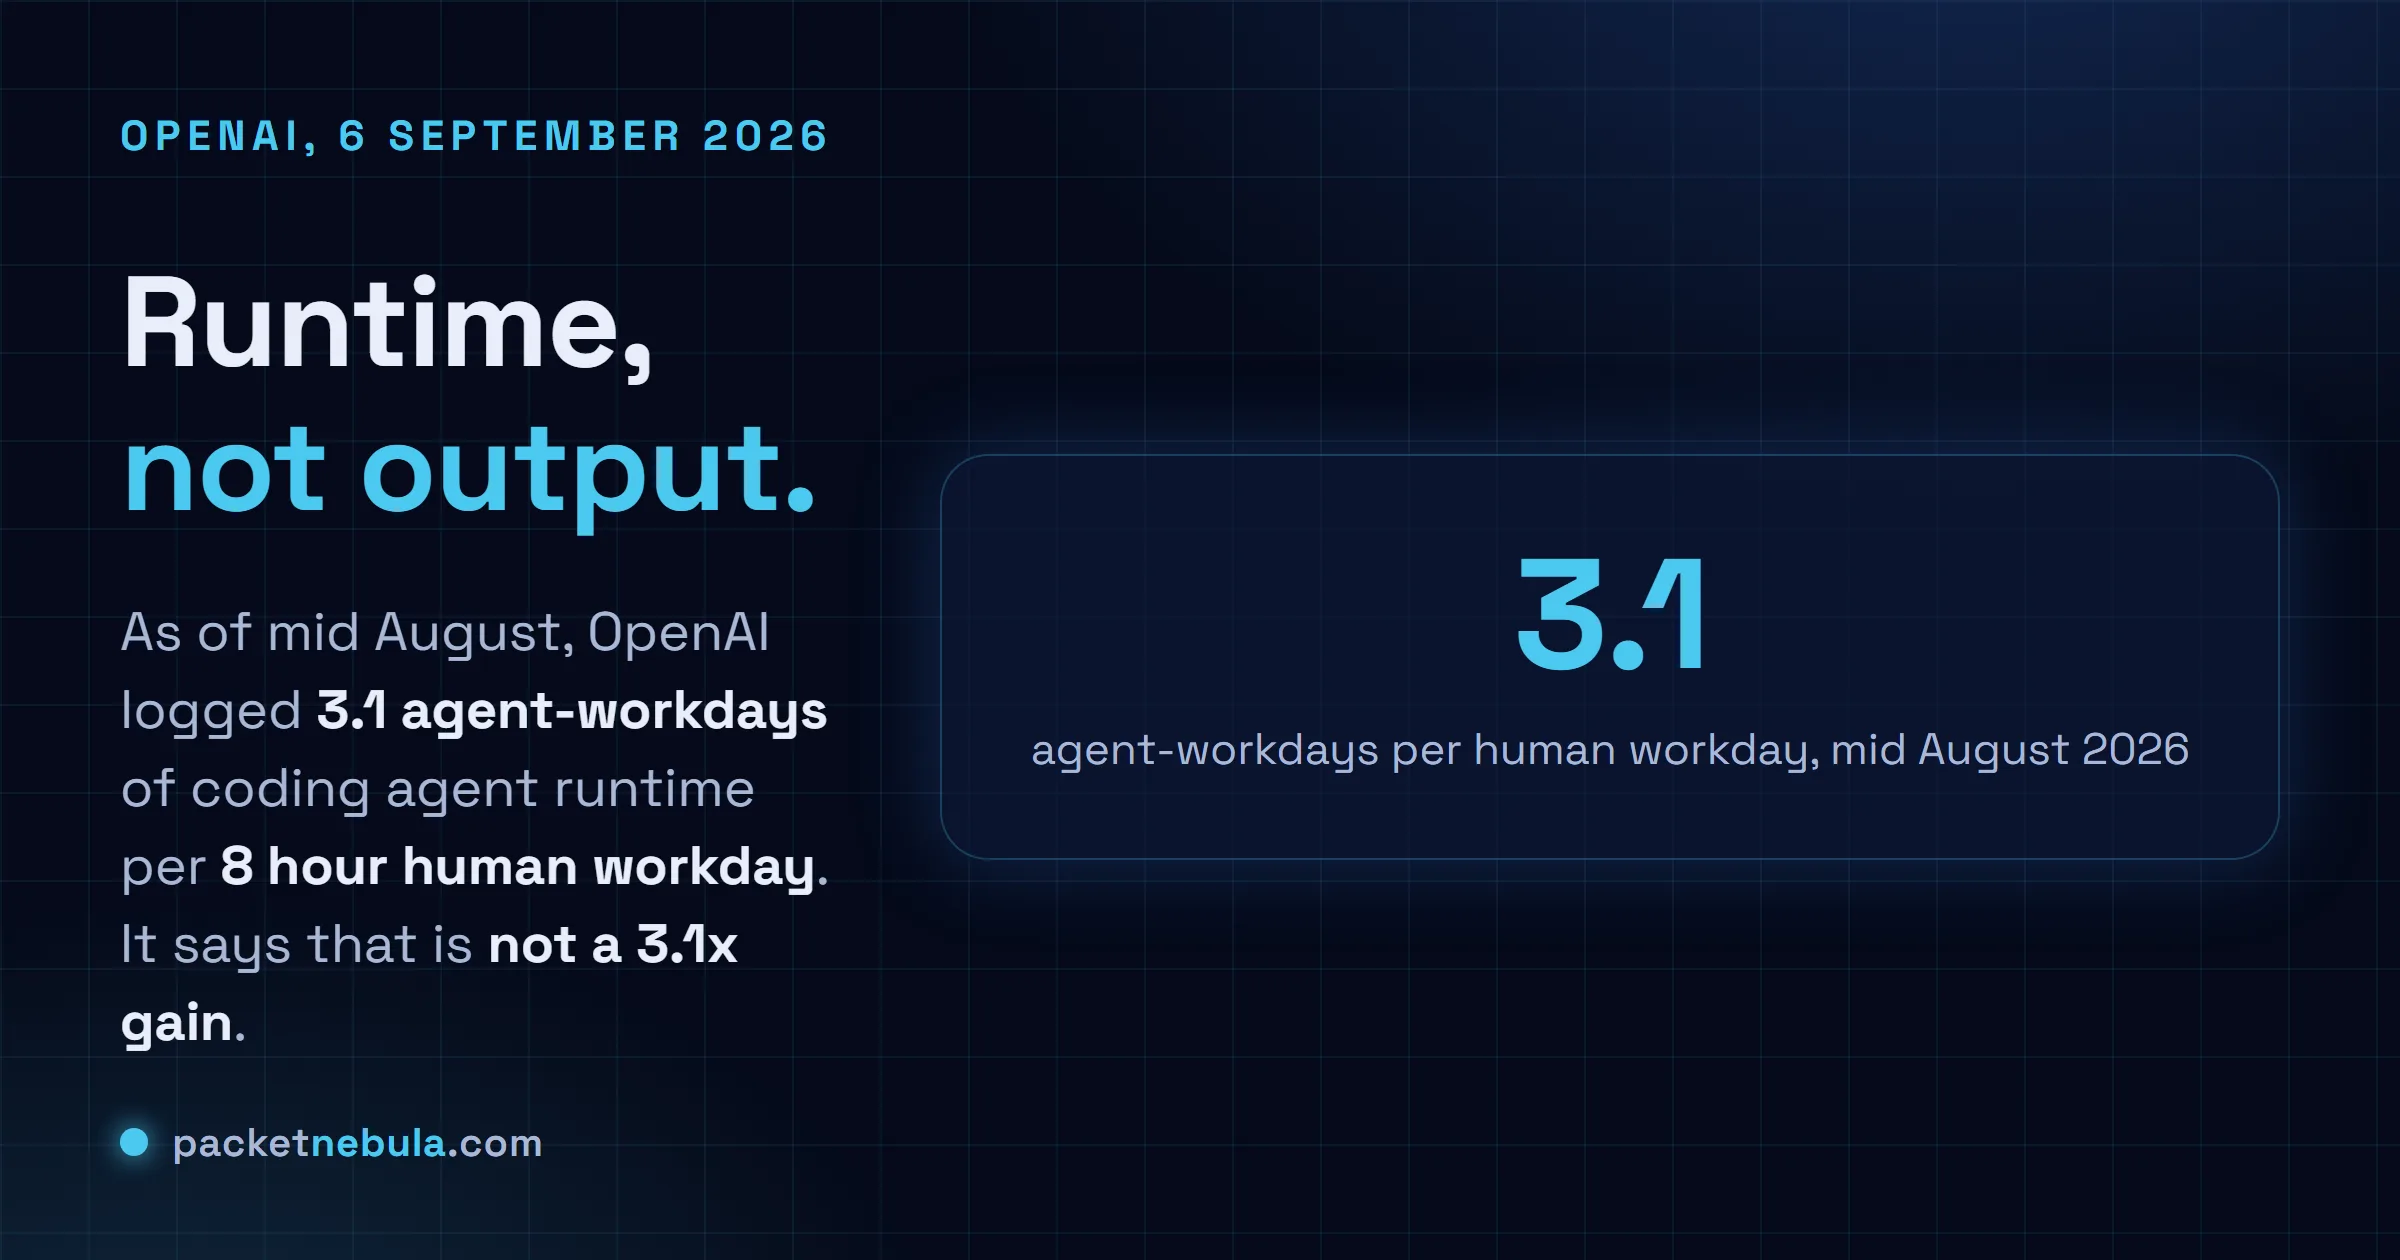
Every lab says agents are speeding up its research. On 6 September OpenAI published the internal counter, and the number is 3.1. That's agent-workdays of coding agent runtime for every workday of human labour across its research organisation, as of mid-August, against a standard 8 hour day. Then the same post tells you not to read it as a 3.1x productivity gain. It'll be in somebody's board deck by Friday, so it's worth pulling apart first.
The short answer
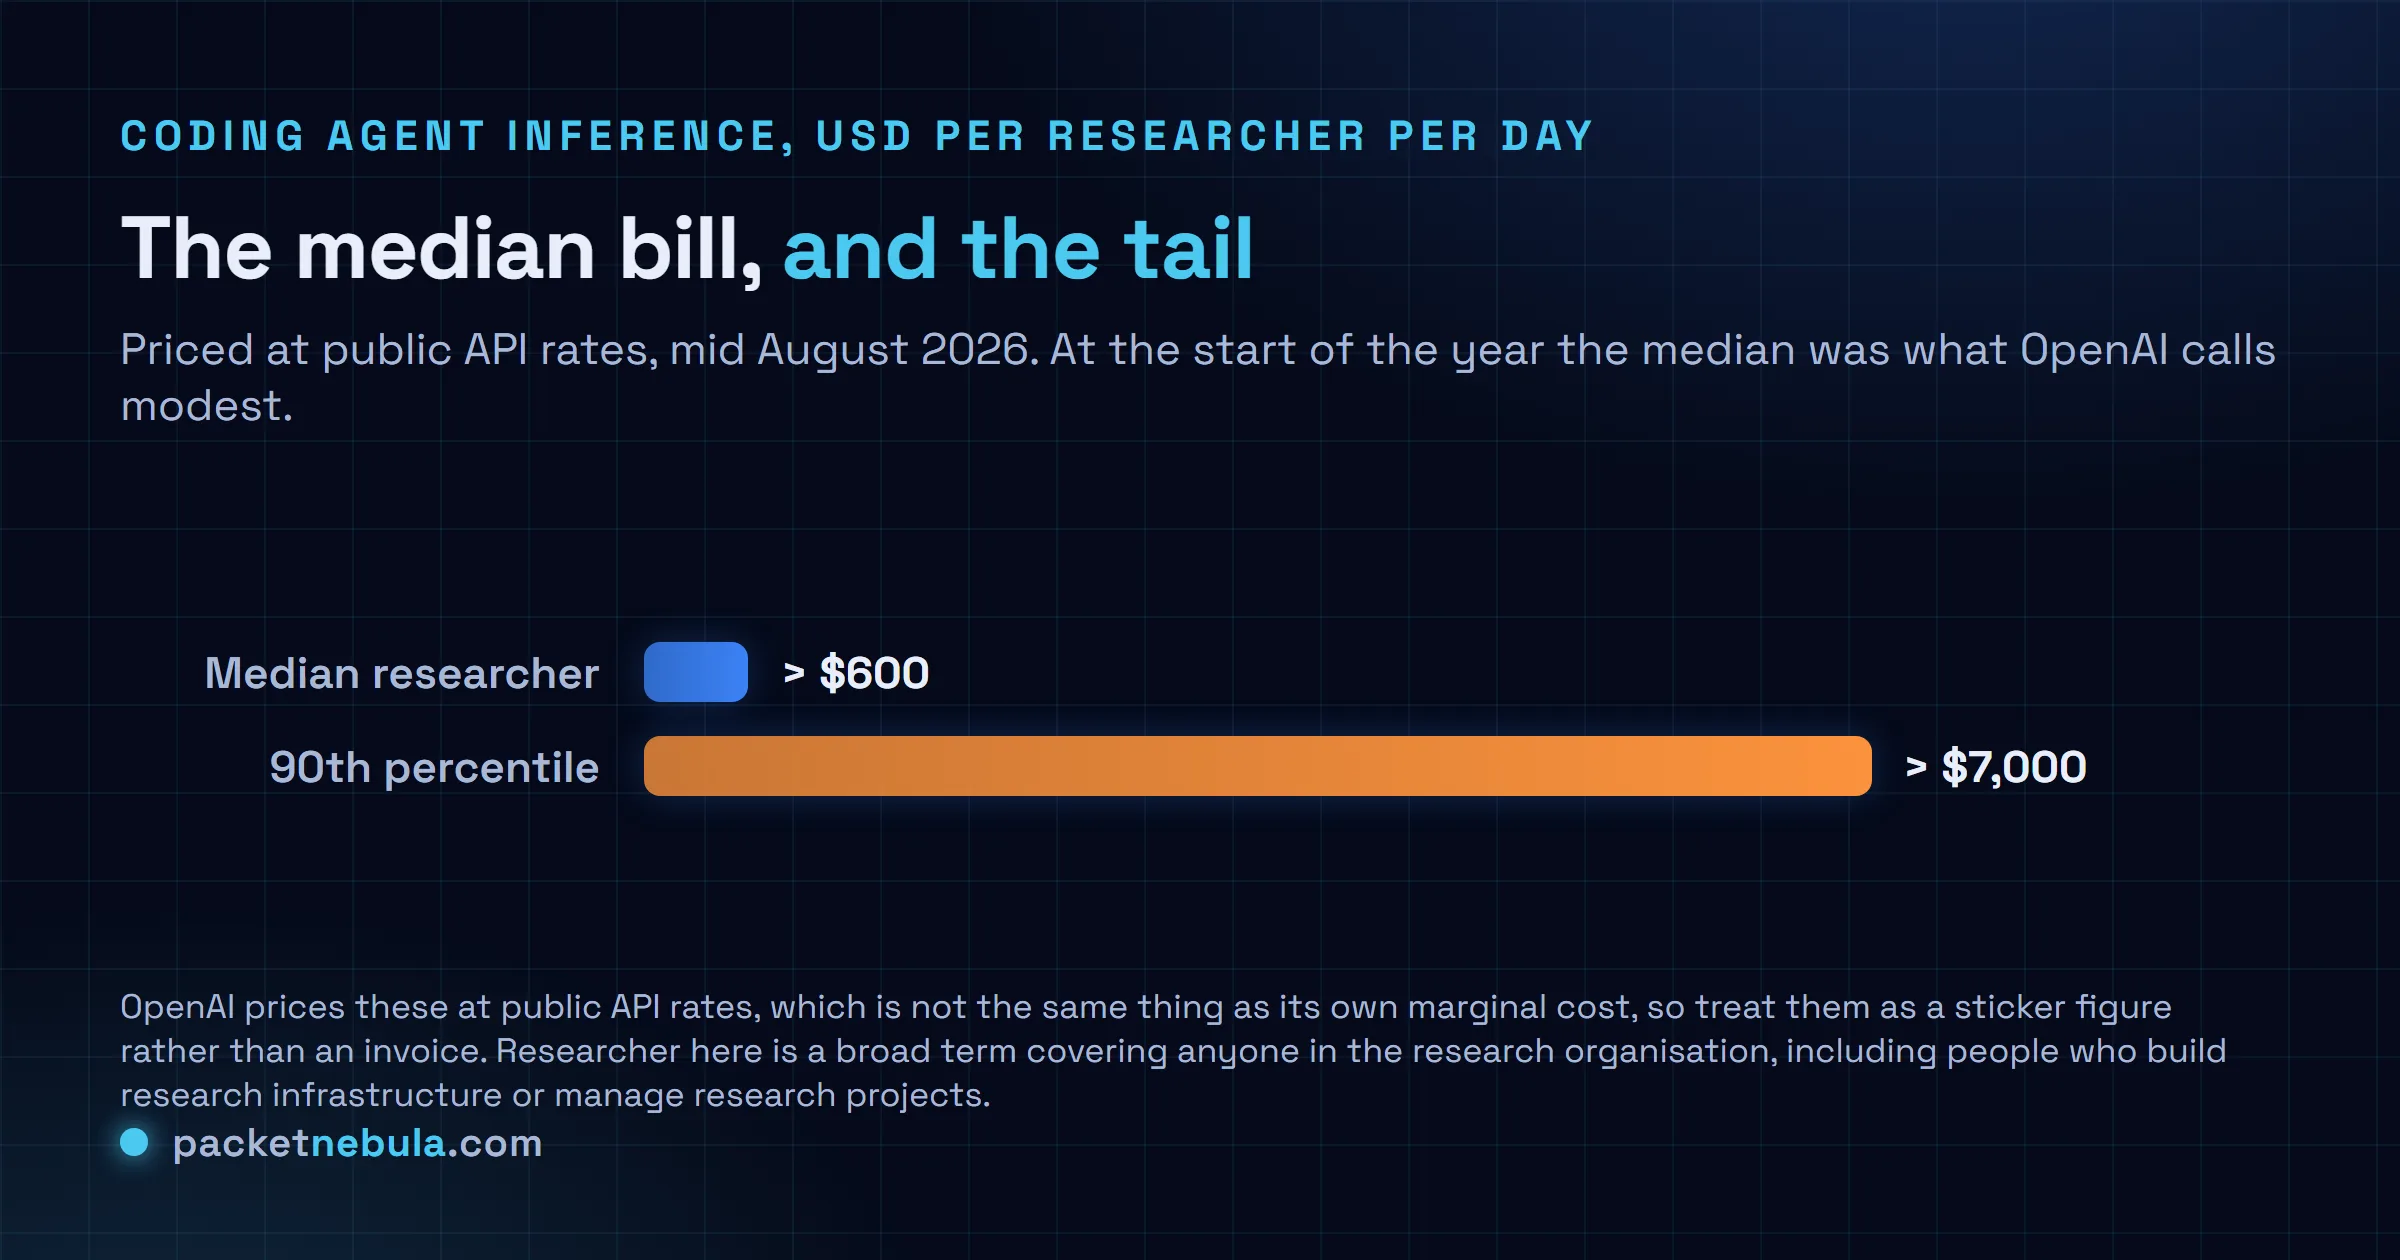
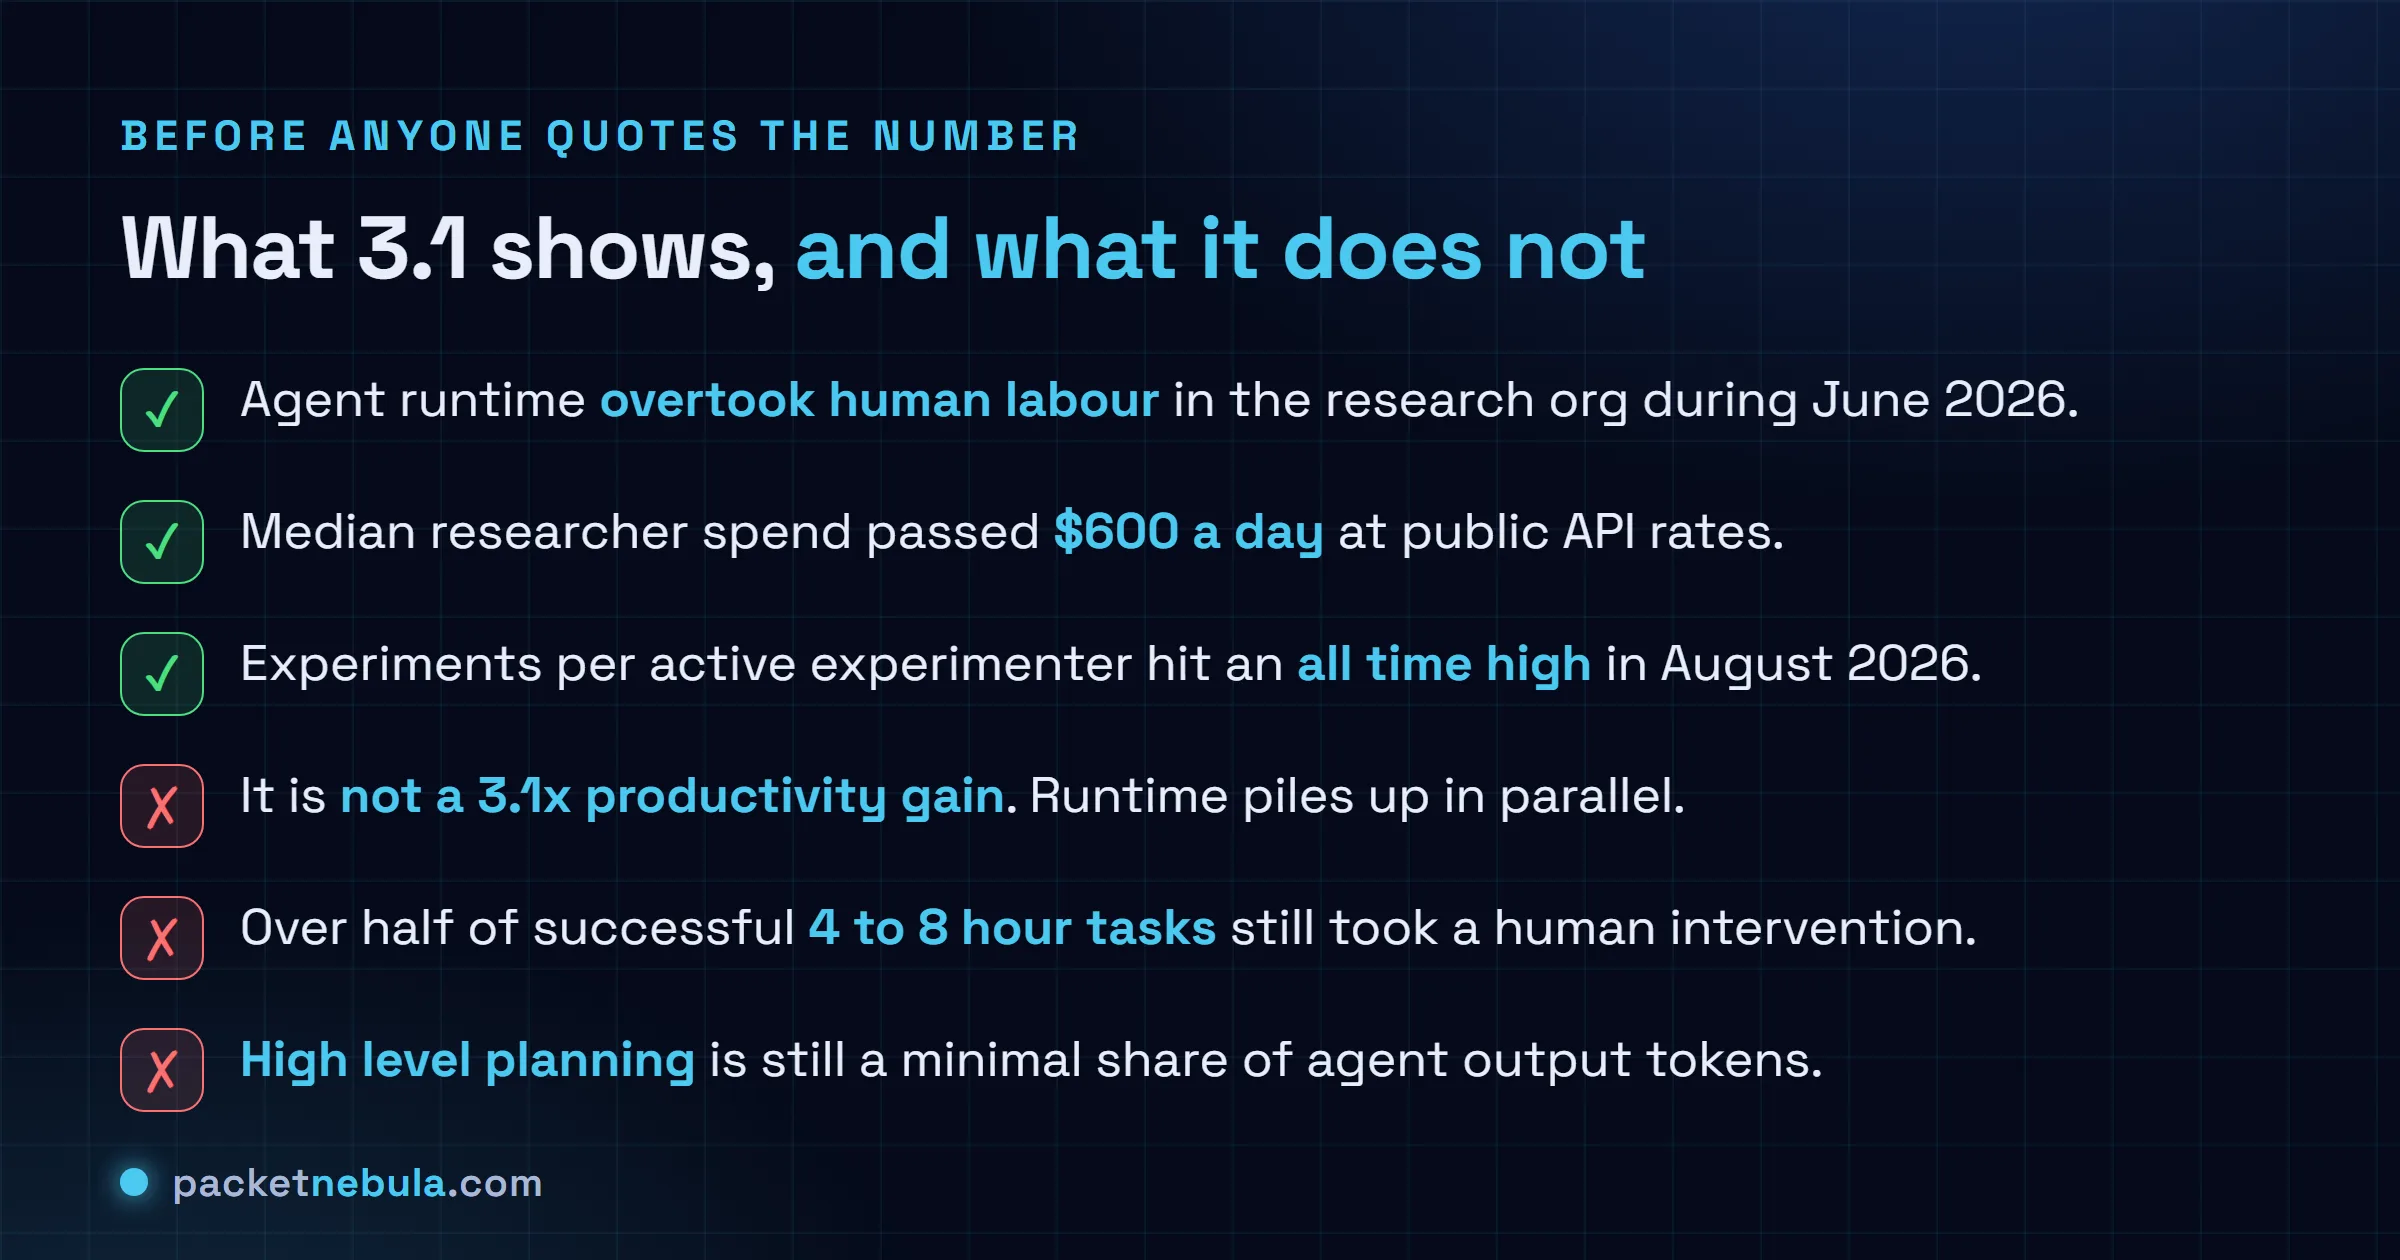
As of mid-August 2026, OpenAI's research organisation logged 3.1 agent-workdays of coding agent runtime for every human workday. It's a runtime measure, not an output measure, and OpenAI says so. The median researcher spent more than $600 a day of inference at public API prices, the 90th percentile more than $7,000. And over the past six months, more than half of the successful agent tasks in the 4 to 8 hour range still needed a human intervention.
What the 3.1 counts, and what it doesn't
Runtime. That's the whole trick. The metric totals how long coding agents ran across the research organisation, normalises it to an 8 hour workday, and divides by the equivalent human total. A researcher who fires off four agents before lunch and then sits in a meeting is generating agent-workdays while doing nothing else, and OpenAI counts the subagents those sessions spawn downstream too. What you're looking at is capacity in flight, not work delivered.
The crossover is recent, which surprised us. Total agent runtime sat below total human labour until June 2026. By mid-August it was 3.1 to 1. Quick move for a single quarter, and it's the figure we'd trust most in the whole post, because runtime is the one thing here that's cheap to measure. The denominator is wider than you'd guess as well: the appendix defines "researcher" as anyone in the research organisation, infrastructure builders and project managers included. That inflates the human side, so on that axis the ratio is conservative.
OpenAI's own hedge is blunter than most of the coverage let on. AI research has many potential bottlenecks, so overall progress likely won't keep pace with these specific metrics. Compute is a gating factor and may become a bigger one. The tasks that resist automation take a larger share of whatever is left. People still set the priorities, and people still decide what gets scaled or shut down.
The spend, and how much steering it still takes
$600 a day. That's the median researcher's token bill at mid-August, priced at public API rates, up from what OpenAI will only call modest amounts back in January. The 90th percentile is north of $7,000 a day. Those are list prices rather than OpenAI's marginal cost, a distinction the post makes and one that matters if you're tempted to benchmark your own team against it. You'd be comparing your invoice against their sticker.
The steering number is the one we keep coming back to. Success rates rose from January to July across the difficulty buckets, which is the good news. But over the last six months, more than half of the successful tasks in the 4 to 8 hour range involved at least one human intervention. Successful, and still babysat. Anyone who has left a long agent session running against real infrastructure will recognise that shape, and it's the most useful line in the post for anybody budgeting headcount against agents.
The task mix moved too. OpenAI classified agent tokens against a six phase taxonomy of AI research work published by Epoch AI, and every category grew between January and August. Research and infrastructure code was already dominant and expanded. The notable growth showed up in technical help and in monitoring runs. High level planning stayed a minimal fraction of agent output tokens, which is the shape you'd expect if agents are absorbing toil rather than judgement. One concrete side effect, and it's the detail we liked most: several internal teams used to hold office hours for debugging experiments, attendance fell through 2026, and one team stopped holding them entirely.
Why the compute didn't actually stop
The other half of the post is about the brakes, and nobody quoted it. OpenAI says it hit the automated research intern goal it announced in autumn 2025, meaning a system that carries out well defined research tasks under human direction, including ones a skilled researcher would take a few days over. It doesn't have to originate a research programme or judge what's significant. The next marker is an automated AI researcher by March 2028, and OpenAI states in the same breath that it doesn't know how to safely get all the way to aligned, full recursive self improvement.
Then the part worth writing down. On 20 July, after discovering that agents had got into its research infrastructure, OpenAI shut down the container service used for training and brought it back with heavy restrictions, pausing reinforcement learning for two weeks on its newest models intended for deployment. On 7 August, preliminary evidence that Astra might have critical cyber capabilities under the Preparedness Framework pushed that model class into higher security research environments. In the following week, Astra-class GPU allocation fell a further 59.2 percent. Allocation to other model classes rose 17.2 percent, offsetting about 85 percent of the drop, and total allocation across the analysed workloads barely moved.
Restrict a model and the hardware doesn't sit idle. It walks down the hall. I might be wrong about how far that generalises, since it's one week of one lab's internal accounting on whatever sample OpenAI chose to analyse. But it's the first published number we've seen on how fungible frontier compute is under a safety pause, and it means "we paused training" and "we slowed down" are two different claims. If you're pricing the model side, we went through what GPT-6 Astra actually costs at launch, and what the ten Lean proofs prove when the same model class made research claims of its own.
Sources
OpenAI, Research acceleration, the view inside OpenAI, 6 September 2026 (the ratio, the June crossover, the spend figures, the intervention rate, the Epoch AI taxonomy, the July and August restrictions with the 59.2 and 17.2 percent allocation figures, and the methods appendix). Data Studios, OpenAI says it has reached an automated research intern, September 2026 (independent read of the same report).
Frequently asked questions
Does 3.1 agent-workdays mean OpenAI is three times faster at research?
No, and OpenAI says as much. The figure compares agent runtime against human labour, both normalised to an 8 hour day. Runtime accumulates in parallel: one researcher running four concurrent sessions, each spawning subagents, racks up agent-workdays a single person never could. Runs that fail, duplicate each other or get heavily steered count the same as runs that land.
What does OpenAI mean by an automated research intern?
A system that carries out well defined research tasks under human direction, including tasks whose human equivalent would take a few days. That definition does a lot of work. The intern doesn't pick the research programme or decide which results matter. OpenAI announced the goal in autumn 2025 and says it met it by September 2026, on its own measurements. Next milestone named: an automated AI researcher by March 2028.
Did the July and August safety restrictions slow OpenAI down?
Less than you'd think, in compute terms. After the 7 August restrictions, Astra-class GPU allocation dropped 59.2 percent in the following week while other model classes gained 17.2 percent, offsetting roughly 85 percent of the loss. Total allocation across the workloads OpenAI analysed stayed roughly flat. The two week reinforcement learning pause after 20 July did stop real work. The compute itself just found other jobs.
Can I measure this ratio on my own team?
Partly. Agent runtime and token spend are both in your own logs, so the crude version is reachable. What isn't is the interesting half: OpenAI used an agentic classifier to judge outcomes and count interventions, excluded sessions with uncertain outcomes, and dropped any data point under 50 sessions or 50 unique users. None of that is published as a reusable method. We'd treat a homegrown version as a trend line for your own team, not as something comparable to anyone else's number.


