
• Latest
  • Trending
  • All
Answer card stating that OpenAI released the Agents API in public beta on 10 September 2026 with no separate fee, billed through model tokens, tool calls and hosted sandbox time, with a choice of OpenAI hosted, self hosted or partner sandboxes, US only data residency and no Zero Data Retention support.

OpenAI’s Agents API has no fee, no ZDR and a one hour sandbox clock

14 September 2026
Answer card: Sakana Fugu Max at $2 and $6 per million tokens, Fugu Ultra v2 unchanged at $5 and $30, and Sakana saying Ultra v2 scores without Fable 5 or GPT-6 Astra in its pool.

Fugu Max costs $2 and $6 while Fugu Ultra v2 runs without Fable 5

13 September 2026
Answer card stating that DeepSeek released DeepSeek-V4.1-Flash on 10 September 2026 as a 552 billion parameter mixture of experts model with a new causal encoder decoder architecture that activates 8 billion parameters on input and 16 billion on output, with native vision, a one million token context and MIT licensed weights, that the API model name is now deepseek-flash at 0.15 dollars per million input tokens and 0.60 dollars per million output tokens off peak, and that DeepSeek announced V4 Pro would be routed to V4.1-Flash from 14 September and reversed that on 11 September.

DeepSeek V4.1-Flash arrived, and the V4 Pro retirement lasted a day

12 September 2026
Answer card stating that Cognition released SWE-2 on 10 September 2026, a coding model post-trained from Kimi K3, scoring 50.0 percent on FrontierCode 1.1 Main against 50.9 percent for Claude Fable 5.1 and 27.3 percent on Terminal-Bench 4 against 55.8 percent, available only inside Devin.

SWE-2 trails Fable 5.1 by one point, and by 28 on Terminal-Bench 4

11 September 2026
Answer card for Meta Muse, free to 100 million tokens a week then $20 a month, launched 8 September 2026 for United States adults only, running in a dedicated per user virtual machine.

Does Meta Muse do enough to earn your inbox and a card on file?

9 September 2026
Answer card stating that the public download pages for the VMware Virtual Disk Development Kit on developer.broadcom.com began returning 404 errors on 25 August 2026 with no announcement or deprecation notice, that Broadcom support tells customers the kit is no longer available for use or download, and that release lines 7.0.3.1, 8.x and 9.x are all affected.

Broadcom pulled VDDK 8.0 and 9.0, and the 404 is the only notice

8 September 2026
Answer card stating that OpenAI published its research acceleration measurements on 6 September 2026, that as of mid August 2026 its research organisation logged 3.1 agent workdays of coding agent runtime for every workday of human labour normalised to a standard eight hour day, and that OpenAI states this should not be read as a 3.1 times productivity gain because it measures runtime rather than delivered output.

OpenAI’s 3.1 agent-workdays per human day is not a 3.1x gain

7 September 2026
Answer card stating that Mullvad announced on 3 September 2026 that it is shutting down its public encrypted domain name system servers on 2 November 2026 and sponsoring the Quad9 Foundation instead, with 194.242.2.2 and its five sibling addresses all going away, and virtual private network customers unaffected.

Mullvad’s DNS servers go dark on 2 November, and Quad9 blocks no ads

5 September 2026
OpenAI announcement image for GPT-6 Astra, a spiral galaxy of white, blue and amber points of light curling around a bright core on a near black star field.

GPT-6 Astra lists at $10 and $50, 2.5x what GPT-5.6 Sol costs

6 September 2026
Google's official announcement image for the release, reading Introducing Gemini 3.8 Flash and 3.8 Flash Cyber in black type over a pale blue background with a blurred white chevron and the four colour Gemini spark below.

Gemini 3.8 Flash keeps the price and the 1 January cliff

3 September 2026
Answer card stating that Anthropic announced Enterprise Frontier Safeguards on 1 September 2026, that activity data used for misuse monitoring moves into cloud storage the customer controls under the customer own encryption keys, that Anthropic charges nothing for the feature while the cloud provider bills storage and egress, and that the phased rollout starts later in autumn 2026 with interim zero data retention on Fable 5 and Fable 5.1 for eligible customers.

Anthropic moves retention into your own cloud, for 30 days

3 September 2026
Official Google diagram of a client connection in three numbered steps: a DNS lookup with a query and an address, a TLS ClientHello and ServerHello, then a content exchange with a website. A callout on the DNS step reads 25% of global web traffic is now protected by encrypted DNS, and a callout beside an Android phone on the ClientHello step reads Android 17 supports ECH GREASE by default.

Android 17 hides the SNI, not your DNS or destination

3 September 2026
Still frame from the Claude Fable 5.1 launch video showing model-designed protein binders in orange docked against twelve grey target proteins, rendered as ESMFold2 structure predictions.

Claude Fable 5.1 breaks forced tool use, cuts cache 75%

1 September 2026
  • About
  • Contact
  • Privacy
  • Legal
Tuesday, September 15, 2026
  • Login
Packet Nebula
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About
No Result
View All Result
Packet Nebula
No Result
View All Result
Home Dev

OpenAI’s Agents API has no fee, no ZDR and a one hour sandbox clock

by stephane
14 September 2026
in Dev
0
Answer card stating that OpenAI released the Agents API in public beta on 10 September 2026 with no separate fee, billed through model tokens, tool calls and hosted sandbox time, with a choice of OpenAI hosted, self hosted or partner sandboxes, US only data residency and no Zero Data Retention support.
492
SHARES
1.4k
VIEWS
Share on FacebookShare on Twitter

Somewhere in your repo there's a 400 line agent loop that compacts context and babysits a container, and it's the file nobody wants to open. On 10 September OpenAI put that loop behind an API. The Agents API is the Codex harness sold as a managed service, in public beta for every developer, with no fee of its own. You pay for tokens and tool calls, plus sandbox minutes if OpenAI hosts the box. We spent a morning in the docs rather than the launch post, and that's where the interesting parts are.

The short answer

Since 10 September 2026, one call to POST /v1/agents/sessions with the OpenAI-Beta: agents=v1 header gives you a Codex-style agent that OpenAI runs for you: context compaction, tool search, subagents, resume. The sandbox can be OpenAI hosted, your own machine running codex exec-server, or one of nine partners. There's no separate API fee. Hosted sandboxes bill at container rates from $0.03 per 20 minutes for 1 GB, and an idle one is deleted after an hour. Data residency is US only, and Zero Data Retention isn't supported, self-hosted sandbox or not.
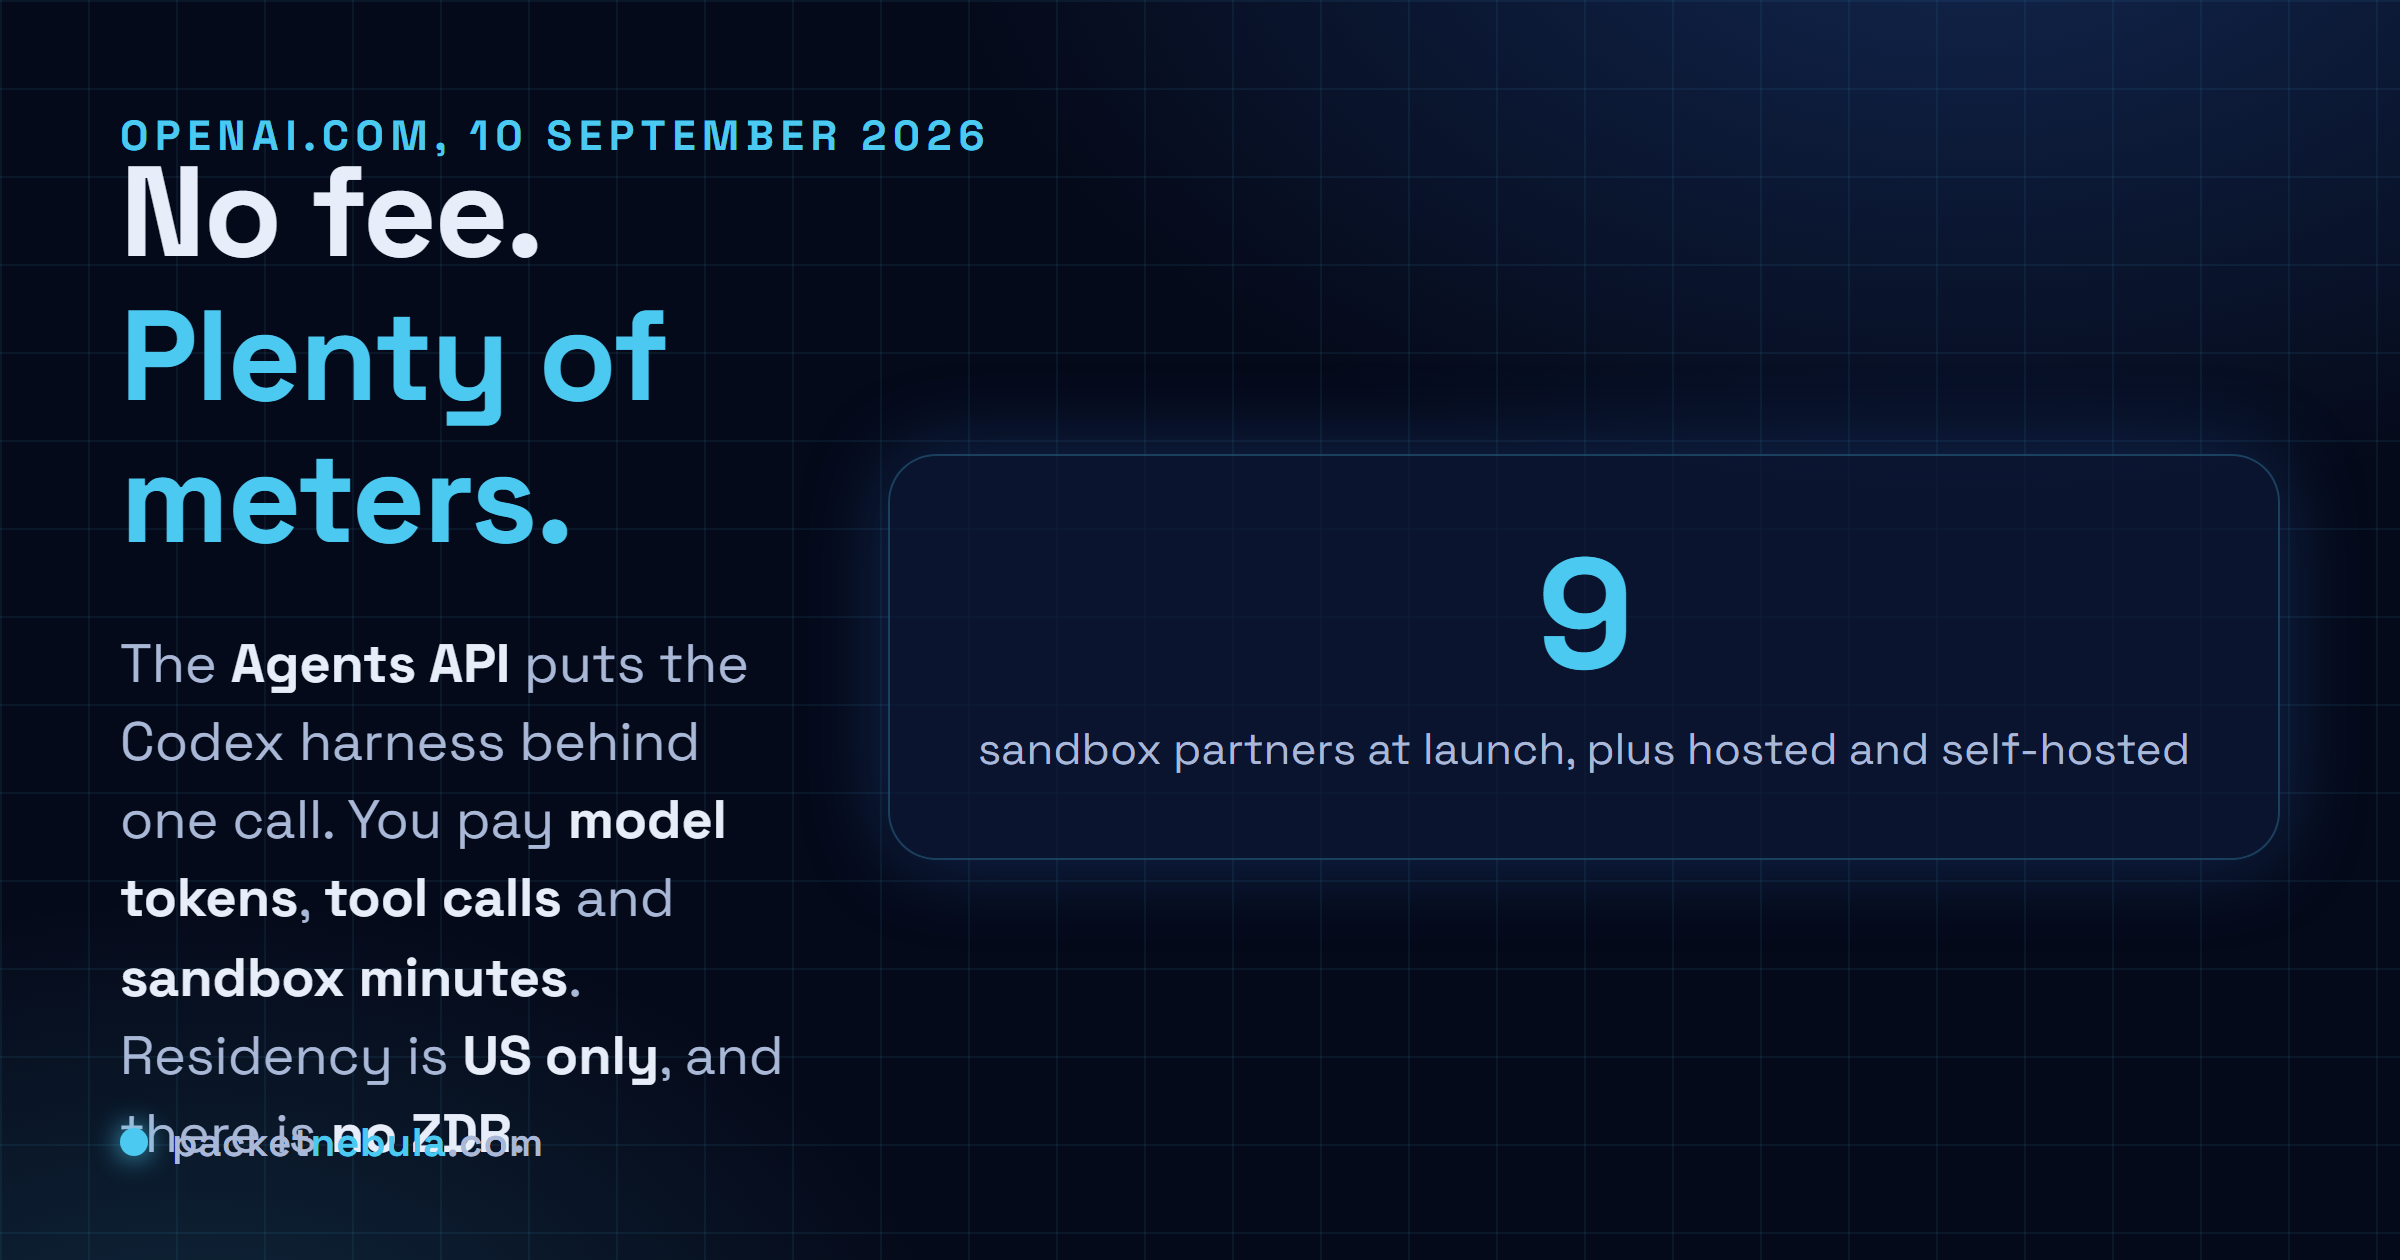
$0separate fee for the Agents API itself
9sandbox partners at launch, plus hosted and self-hosted
1 hourbefore an idle hosted sandbox is deleted, not configurable
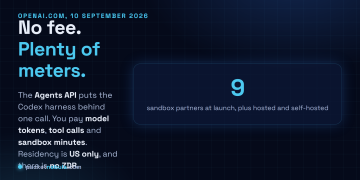
Answer card stating that OpenAI released the Agents API in public beta on 10 September 2026, that it exposes the managed Codex harness through a single session create call, that there is no separate fee and usage is billed through model tokens, tool calls and hosted sandbox container time, that the sandbox can be OpenAI hosted, self hosted or run at one of nine partners, and that data residency is United States only with no Zero Data Retention support.
No fee on the API. Three meters underneath it.

What one session create actually buys you

Four nouns. An agent is the model, instructions, tools and MCP servers. An environment is the optional sandbox where it reads files and runs commands. A session is a durable instance of that agent, and events and items are what goes in and what comes out. You create a session with the agent config and an input, then stream events or wait on a webhook. Send another input to the same session and the agent picks up where it stopped, with OpenAI holding the state.

The harness is the part we'd have paid for. It compacts earlier context automatically as a session nears its limit, so a job can span several context windows without you writing the summariser. Tool search loads tool definitions on demand instead of stuffing them all into the prompt, and programmatic tool calling lets the model filter results in code before they touch the context. Subagents are a flag: multi_agent.enabled with max_concurrent_subagents, which defaults to 6, not counting the coordinator. Honestly, that default feels high to us for anything billed per token, and we'd set it to 2 or 3 until we'd seen a bill.

The default model in every example is gpt-6-astra. The harness is the open source Codex one, so you can read the coordination logic even though OpenAI runs it. Your key needs api.agents.read, api.agents.write and api.responses.write, and it stays out of the sandbox. The docs repeat that three times. They're right to.

Three places the sandbox can live, and what each one costs

Option one is openai_hosted. You get a Linux workspace at /workspace with Python and Node.js, pinned packages if you list them, setup commands that run before the agent starts, and input files inline as base64 or by Files API ID. Network access has three modes: enabled (the default), disabled, or restricted to a list of 1 to 100 exact hostnames, no wildcards, no ports, and every subdomain and redirect target needs its own entry. Anything written under /workspace/outputs becomes an immutable artifact when the turn completes, and those copies survive the sandbox. The sandbox itself doesn't. An hour without activity or keep-alives and it can be deleted, and you can't change that timeout.
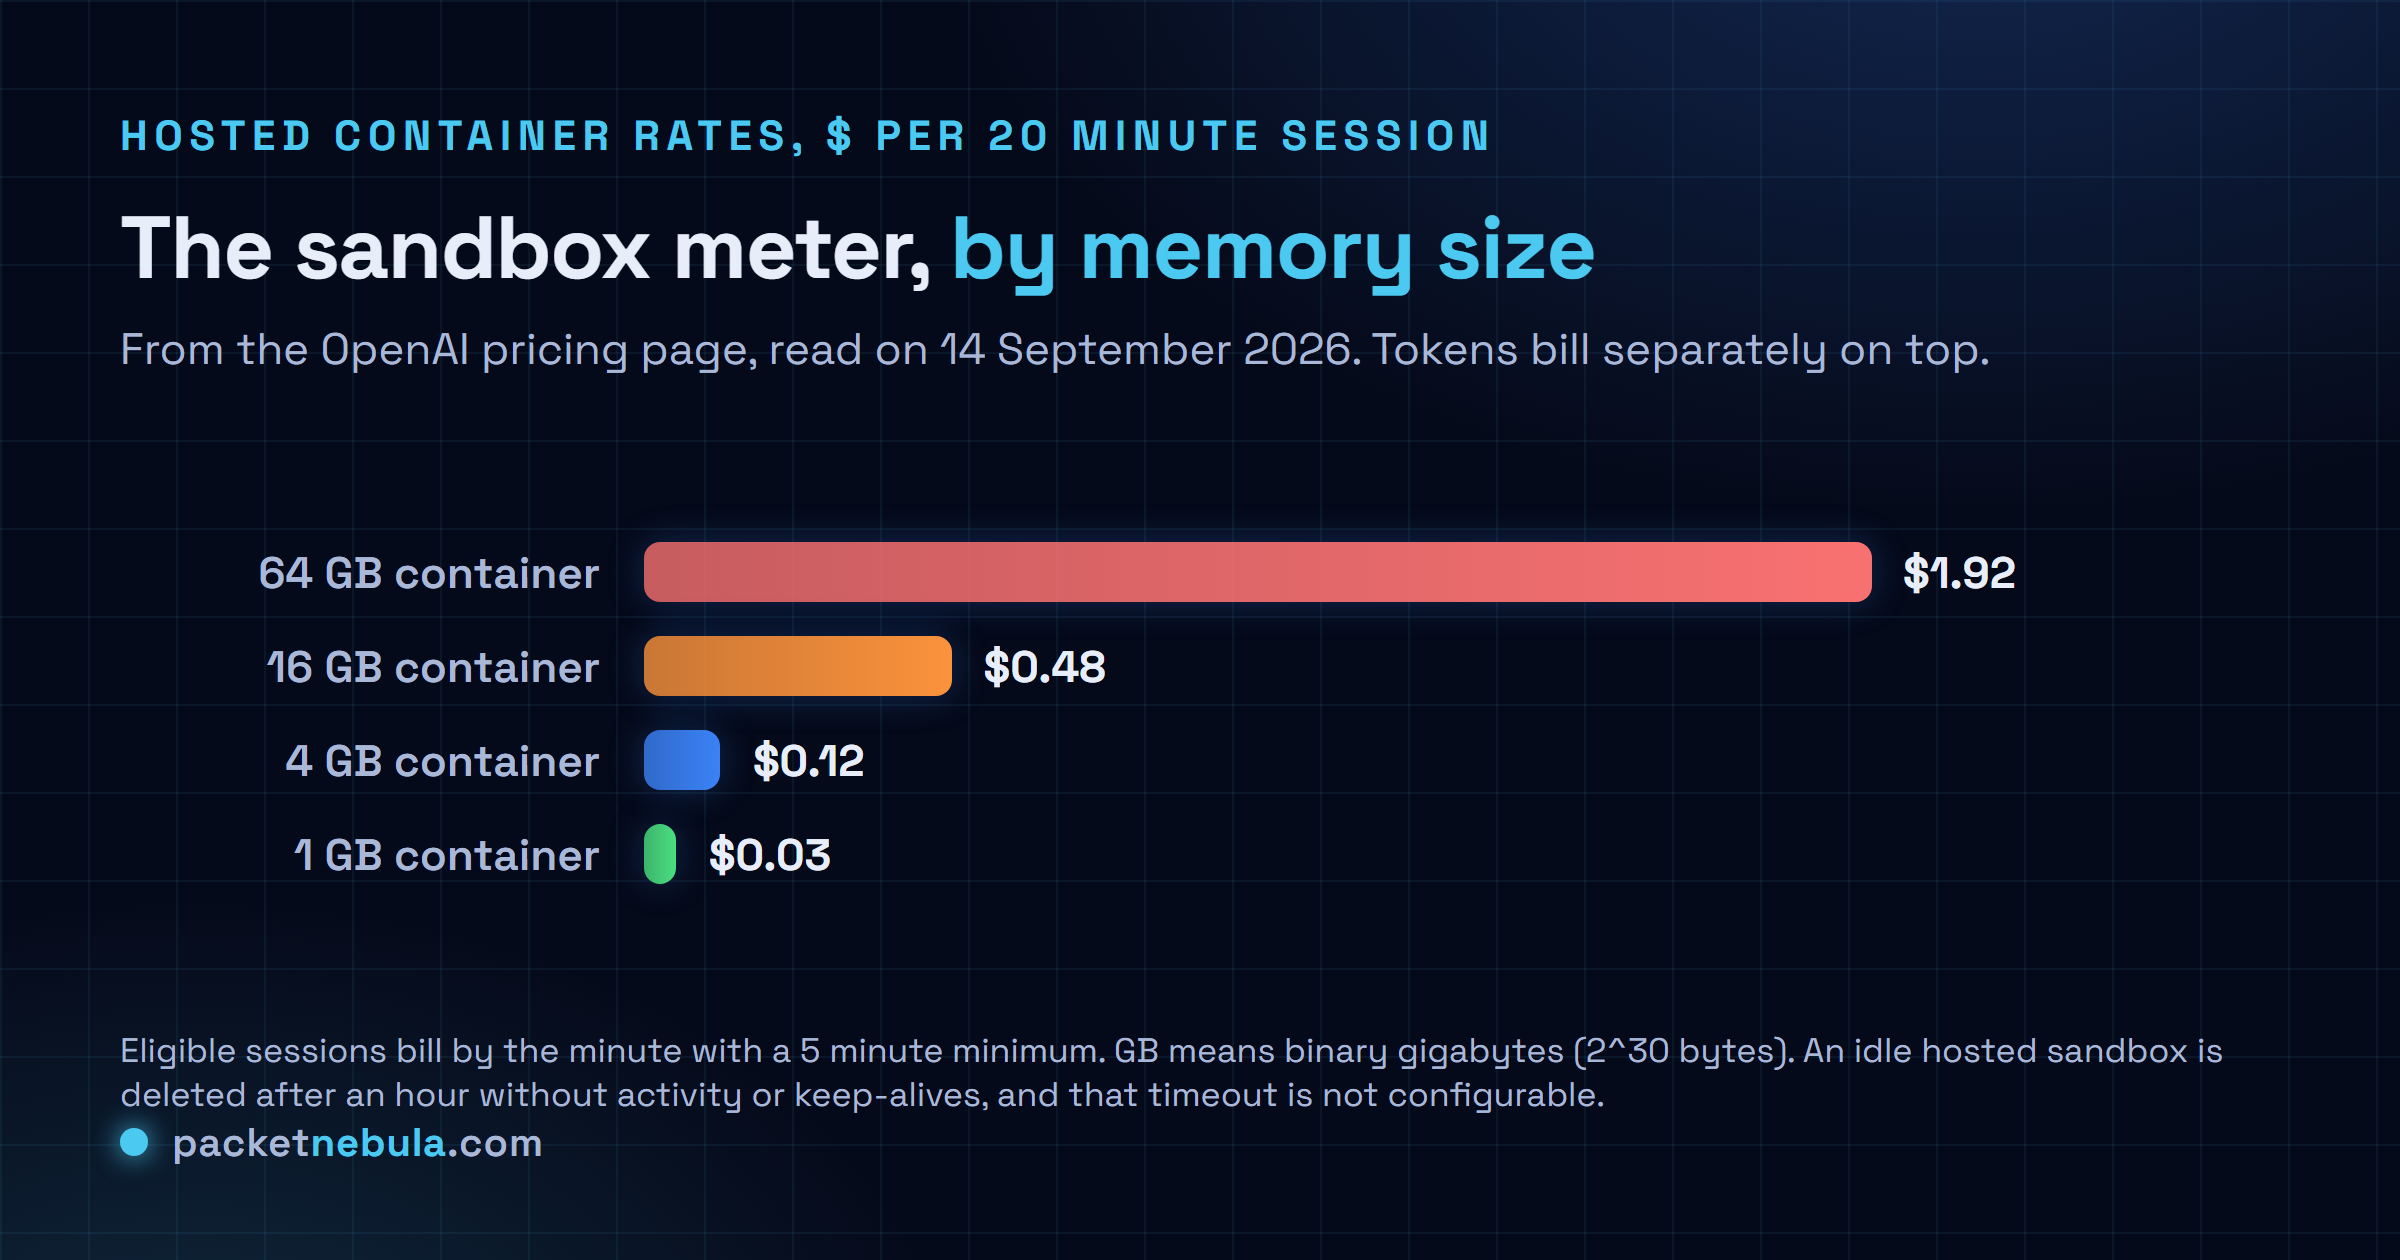
Horizontal bar chart of OpenAI hosted container rates as listed on the OpenAI pricing page on 14 September 2026, per 20 minute session per container, showing 1 gigabyte at 3 cents, 4 gigabytes at 12 cents, 16 gigabytes at 48 cents and 64 gigabytes at 1 dollar 92, with the note that eligible sessions bill by the minute with a five minute minimum and that model tokens are billed separately.
The container meter. Tokens are a second meter on top.

The price for that hosted box is the standard container rate on the pricing page: $0.03 per 20 minute session for 1 GB, $0.12 for 4 GB, $0.48 for 16 GB and $1.92 for 64 GB, with eligible sessions billed by the minute and a 5 minute minimum. Cheap, until you remember the keep-alives run between turns too, so a session you forgot to delete is a sandbox you're paying for. We'd put the delete in a finally block.

Option two is self_hosted, and it's the one we like. OpenAI still runs the harness, but the executor is a process you start inside an environment you trust, a laptop or a container:

Linux
npm install -g @openai/codex@alpha

Then codex exec-server registers with the API using the session's environment ID and a restricted key you create on the Agents tab with every other permission set to None, supplied as CODEX_API_KEY. All connections are outbound, to two hosts: HTTPS to api.openai.com for registration, then a WebSocket to codex-cloud-environments.chatgpt.com for commands and results. That's the whole firewall conversation, which is more than we can say for most agent products. Two caveats from the lifecycle page. The API waits up to five minutes for the executor to connect when input arrives, then fails the submission. And deleting a session neither stops your compute nor sends a webhook, so cleanup is yours. Option three is a partner sandbox: Modal, Cloudflare, Vercel, Daytona, Blaxel, E2B, Runloop, DigitalOcean and Oracle Cloud each have a setup guide, and they're all option two with someone else's provisioning.

The fine print for anyone outside the US

Two lines in the overview undo a lot of enterprise conversations. The Agents API currently supports data residency only in the United States, and it does not support Zero Data Retention. Running the sandbox on your own hardware doesn't change that; the docs say a self-hosted sandbox does not make the API ZDR-eligible, since the session state and artifacts live with OpenAI wherever the commands execute. If you built a compliance story on Private Safety Processing keeping ZDR alive, it stops at this endpoint for now. Beta, so this may move. Today it hasn't.
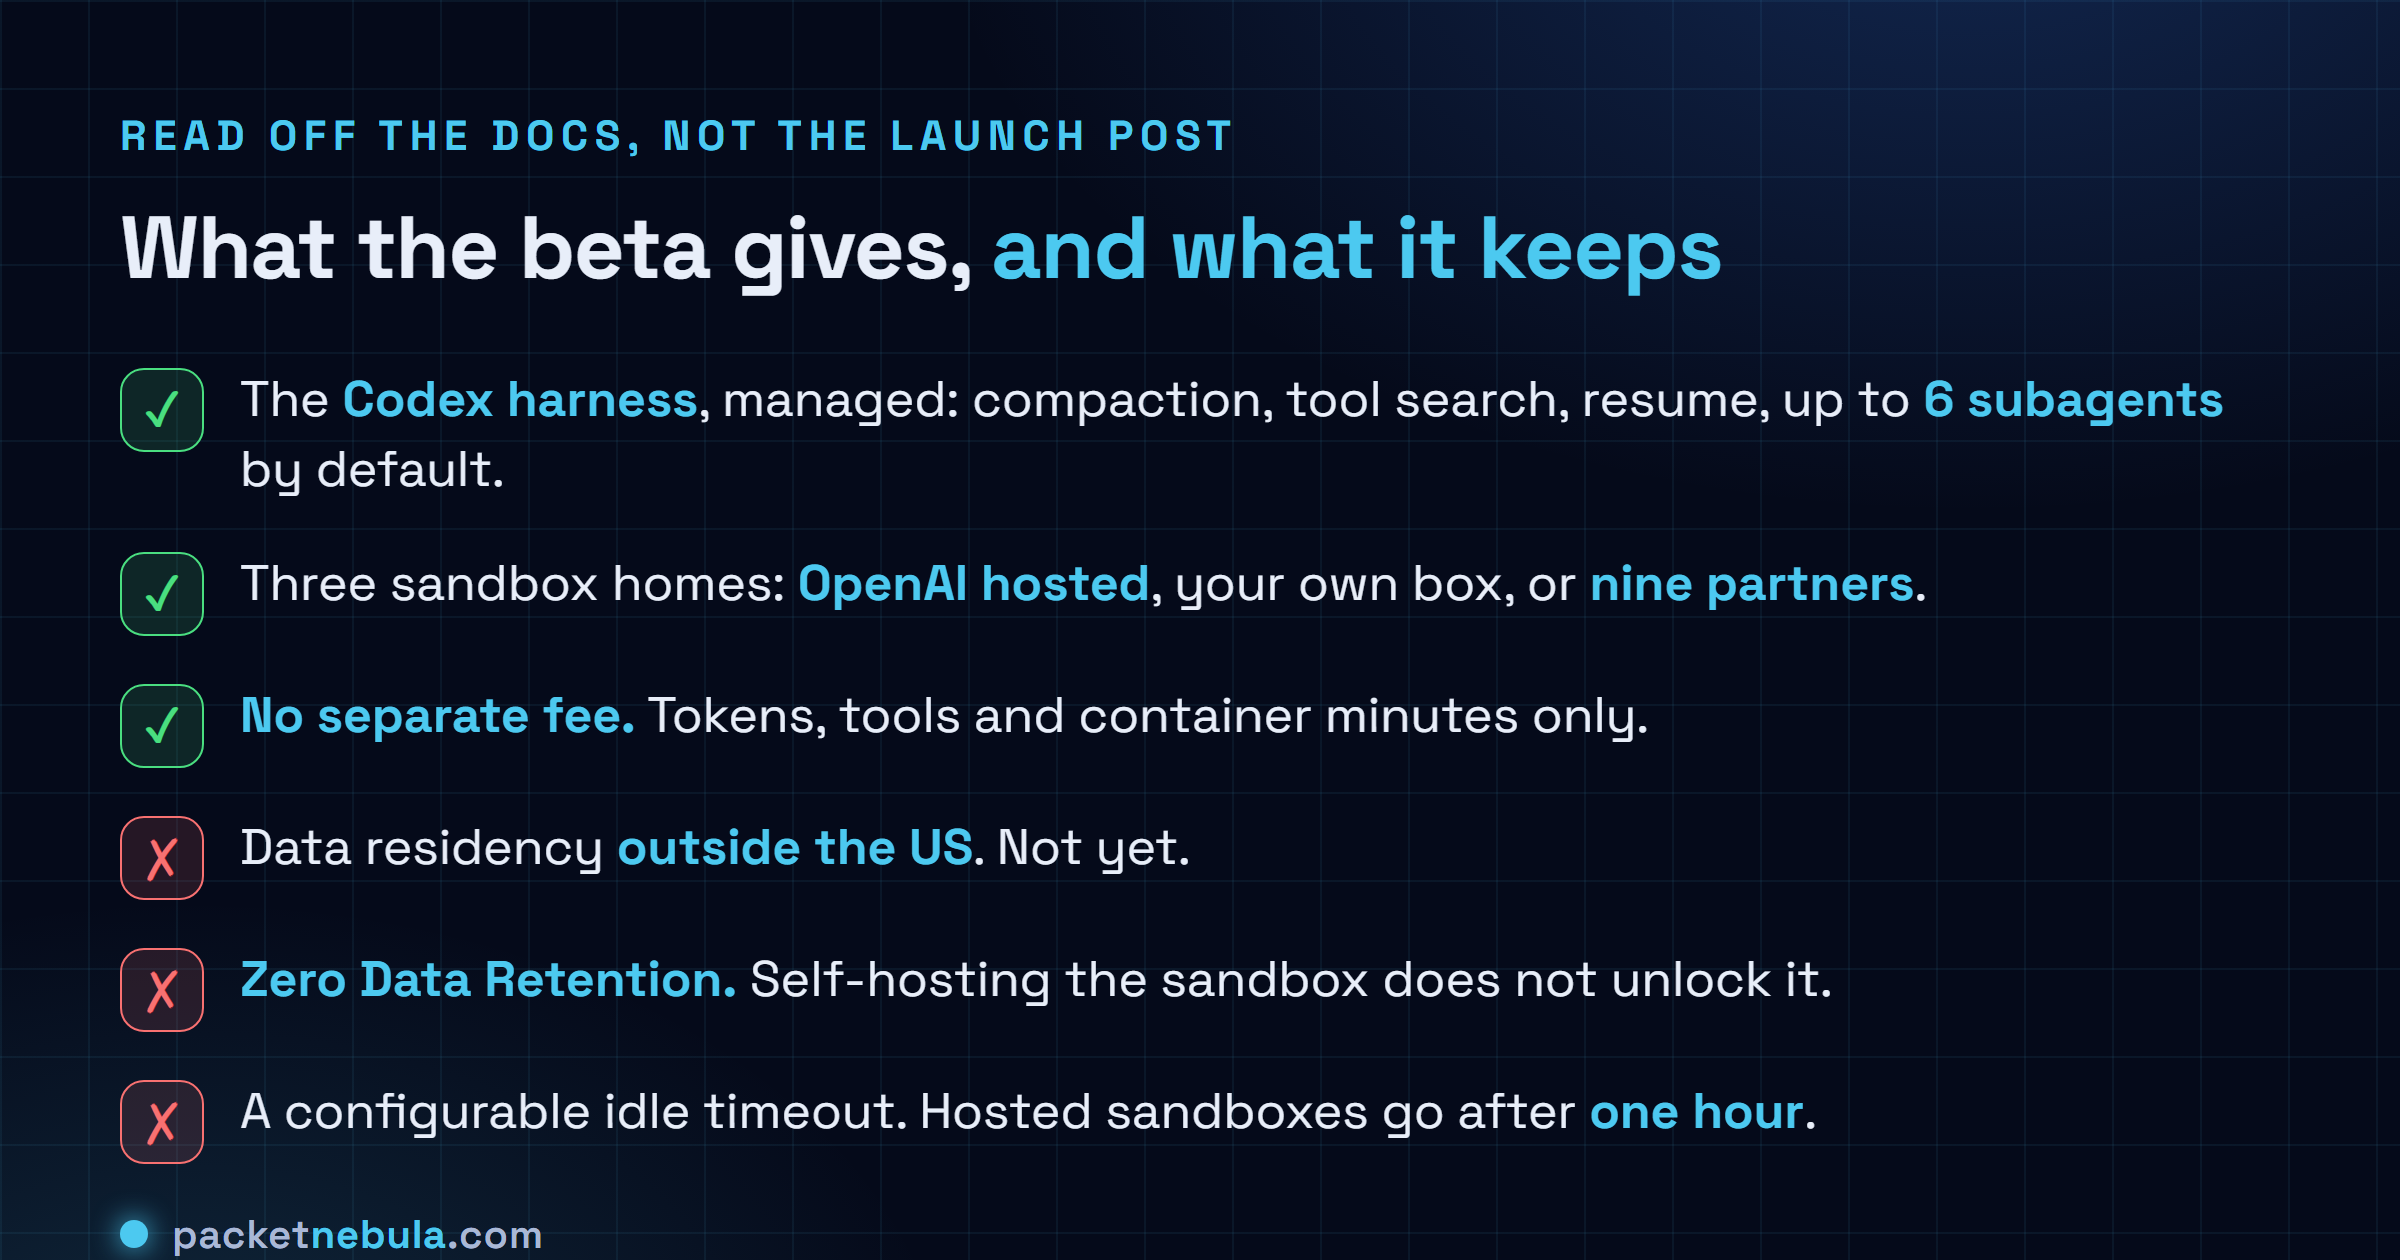
Checklist separating what the OpenAI Agents API public beta gives you from what it withholds, the included items being the managed Codex harness with compaction, tool search and up to six concurrent subagents by default, a choice of OpenAI hosted, self hosted or partner sandboxes, and no separate API fee, and the withheld items being data residency outside the United States, Zero Data Retention even with a self hosted sandbox, and a configurable idle timeout for hosted sandboxes which is fixed at one hour.
Three things you get on day one, three you don't.

The token side is the bigger bill. GPT-6 Astra lists at $10 in and $50 out per million tokens on short context, and $20 and $75 once you cross into long context. A harness that keeps an agent working for hours pushes you toward that cliff, and compaction is supposed to pull you back from it. Whether a compacted session actually stays on the short context rate isn't spelled out anywhere we could find, and there's no worked bill in the docs. I might be wrong about how much that matters, but we'd run the first week on gpt-5.6-terra at $2 and $12 and read the usage page before switching. The customer numbers in the launch post, a 4x latency drop, 60 percent lower cost per case, 86 percent fewer failed responses, all come from the customers themselves. Nobody outside those companies has re-run them.

Sources

OpenAI, Introducing the Agents API, 10 September 2026 (the public beta, the harness features, the partner list, the no-fee statement and the customer quotes). OpenAI developer docs, Agents API overview, OpenAI-hosted sandboxes, Self-hosted sandboxes and Pricing, read 14 September 2026 (the four concepts, the residency and ZDR note, the network modes, the one hour expiry, the executor hosts, the subagent default and the container rates). MarkTechPost, OpenAI launches the Agents API in public beta, 10 September 2026 (independent read of the launch, including the residency and ZDR limits).

Frequently asked questions

Is the OpenAI Agents API free?

The API itself carries no fee. You're billed for the model tokens each session uses at that model's API rate, for OpenAI tools such as web search at their standard rates, and for hosted sandbox time at container rates, from $0.03 per 20 minute session for a 1 GB container up to $1.92 for 64 GB. A self-hosted or partner sandbox moves the compute bill to you or the partner instead.

Can I run the Agents API sandbox on my own servers?

Yes. Set the environment type to self_hosted, install the Codex CLI in your environment and run codex exec-server with a restricted environment key. The executor makes outbound connections only, to api.openai.com and codex-cloud-environments.chatgpt.com. OpenAI still runs the harness and stores the session state; only the commands and files live on your side.

Does the Agents API support Zero Data Retention or EU data residency?

Not in the public beta. The overview states that data residency is supported only in the United States and that Zero Data Retention isn't supported, and it says explicitly that a self-hosted sandbox doesn't make the API ZDR-eligible. If either is a hard requirement, you're still on the Responses API for now.

How long does an OpenAI-hosted sandbox last?

While it's connected it receives keep-alives, including between turns. Once activity and keep-alives stop for an hour the sandbox can be deleted, and that timeout isn't configurable. Files under /workspace/outputs are published as immutable artifacts at the end of each turn and stay downloadable after the sandbox is gone; anything else in the workspace goes with it.

Tags: Agents APIAI agentsCodexGPT-6 Astramcpnewsopenaisandbox
Share197Tweet123
stephane

stephane

  • Trending
  • Comments
  • Latest
Answer card: Proton Lumo 2.0 is private by policy, not by locality. Saved history is locked so even Proton cannot read it, but the prompt is decrypted on a Proton EU server to answer it, then forgotten.

Proton Lumo 2.0 review: how private is it, really?

3 September 2026
The Agentic Coding section of the official Hy4 preview benchmark appendix published by Tencent, a table comparing Hy3 and Hy4 preview against DeepSeek V4 Pro 0813, Qwen 3.8 Max, GLM 5.3, Kimi K3, GPT 5.6 Sol and Claude Opus 5 across SWE-bench Multilingual, SWE-bench Pro, DeepSWE, three SWE Atlas tasks, SWE-Marathon, Terminal-Bench 2.1, NL2Repo-Bench, CyberGym, ProgramBench, PostTrainBench and Harbor-Index.

Tencent’s 770B Hy4 tops one benchmark row in 46

3 September 2026
Answer card: Qwen 3.7 Max is API-only and cannot run locally yet; the open Qwen models (Qwen 3.6 27B, qwen3:8b to 32b) run offline via Ollama.

Qwen 3.7 local: what you can actually run offline

22 June 2026
Answer card: JWTs are not encrypted, anyone can read them; the signature proves who issued the token, not who may read it.

Are JWTs encrypted? No, and the difference will bite you

0
Answer card: a random 8 character password falls in under 2 hours offline, while 16 random characters hold for 1.4 trillion years at the same speed.

How long does it take to crack a password in 2026?

0
Answer card: three DNS records decide if your mail lands or bounces; SPF lists allowed senders, DKIM signs messages, DMARC sets the failure policy.

SPF, DKIM and DMARC explained: the records your email needs

0
Answer card stating that OpenAI released the Agents API in public beta on 10 September 2026 with no separate fee, billed through model tokens, tool calls and hosted sandbox time, with a choice of OpenAI hosted, self hosted or partner sandboxes, US only data residency and no Zero Data Retention support.

OpenAI’s Agents API has no fee, no ZDR and a one hour sandbox clock

14 September 2026
Answer card: Sakana Fugu Max at $2 and $6 per million tokens, Fugu Ultra v2 unchanged at $5 and $30, and Sakana saying Ultra v2 scores without Fable 5 or GPT-6 Astra in its pool.

Fugu Max costs $2 and $6 while Fugu Ultra v2 runs without Fable 5

13 September 2026
Answer card stating that DeepSeek released DeepSeek-V4.1-Flash on 10 September 2026 as a 552 billion parameter mixture of experts model with a new causal encoder decoder architecture that activates 8 billion parameters on input and 16 billion on output, with native vision, a one million token context and MIT licensed weights, that the API model name is now deepseek-flash at 0.15 dollars per million input tokens and 0.60 dollars per million output tokens off peak, and that DeepSeek announced V4 Pro would be routed to V4.1-Flash from 14 September and reversed that on 11 September.

DeepSeek V4.1-Flash arrived, and the V4 Pro retirement lasted a day

12 September 2026
  • About
  • Contact
  • Privacy
  • Legal

Copyright © 2026 Stephane Cardon.

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About

Copyright © 2026 Stephane Cardon.