
• Latest
  • Trending
  • All
Official Cohere key art for the Parse 5 launch: the Cohere mark and the wordmark Parse with a superscript 5 in white, centred on a soft out of focus gradient of deep blue, violet and amber curves.

Cohere Parse 5 is $1.50 per 1,000 pages, on three of five dimensions

3 September 2026
The official xAI announcement card for Grok 4.7, white type on a dark grey and navy gradient.

Grok 4.7 keeps $2 and $6, and its gains over 4.6 are xhigh versus high

22 September 2026
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.

Qwen-Image-2.1 brings the weights back, but not the Apache licence

21 September 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
Answer card stating that Jev 1.13 from TypeSafe AI is a decision model in early access since 15 September 2026 that returns typed probabilities instead of text, priced at 42 dollars per billion input tokens with output tokens free, answering in 70 to 500 milliseconds, with a 64K token request budget, text input only, and a documented list of things it does badly, including counting and dates.

Jev 1.13 bills $42 a billion tokens, and it can’t count

19 September 2026
Answer card stating that Qwen3.8-Omni-Flash launched on 17 September 2026 as an API only model on Alibaba Cloud Model Studio, taking text, images, audio and video in a 1M token context and returning text only, priced at 0.15 dollars per million input tokens for every modality and 0.47 dollars per million output tokens in the international regions, with no open weights published and the Qwen-Live Harness GitHub repository returning 404.

Qwen3.8-Omni-Flash bills audio at $0.15 and ships no weights

18 September 2026
Answer card stating that on 15 September 2026 AWS said it is unable to restore access to resources and data hosted exclusively in the Middle East Bahrain region me-south-1 and in the mec1-az2 zone of the UAE region, because the damage spanned multiple Availability Zones and exceeded what multi-AZ services are designed to withstand.

AWS can’t restore me-south-1, six months after the drone strikes

17 September 2026
Answer card stating that Google released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking on 15 September 2026 at 3 dollars per million audio input tokens and 12 dollars out, that the thinking model requires asynchronous tools, and that Artificial Analysis scores it 82.6 on its Speech to Speech Quality Index.

Gemini 3.8 Live Extended Thinking rejects any tool that blocks

16 September 2026
Answer card summarising the Atria Dawn Preview release: 744B GLM-5.2 base, MIT licence, 1.5 TB BF16 and 756 GB FP8 checkpoints, 256K context, top on five of sixteen benchmark rows and trailing on SWE-bench Pro.

Atria Dawn Preview is 744B under MIT, and the BF16 weighs 1.5 TB

15 September 2026
Answer card stating that OpenAI released the Agents API in public beta on 10 September 2026 with no separate fee, billed through model tokens, tool calls and hosted sandbox time, with a choice of OpenAI hosted, self hosted or partner sandboxes, US only data residency and no Zero Data Retention support.

OpenAI’s Agents API has no fee, no ZDR and a one hour sandbox clock

14 September 2026
Answer card: Sakana Fugu Max at $2 and $6 per million tokens, Fugu Ultra v2 unchanged at $5 and $30, and Sakana saying Ultra v2 scores without Fable 5 or GPT-6 Astra in its pool.

Fugu Max costs $2 and $6 while Fugu Ultra v2 runs without Fable 5

13 September 2026
Answer card stating that DeepSeek released DeepSeek-V4.1-Flash on 10 September 2026 as a 552 billion parameter mixture of experts model with a new causal encoder decoder architecture that activates 8 billion parameters on input and 16 billion on output, with native vision, a one million token context and MIT licensed weights, that the API model name is now deepseek-flash at 0.15 dollars per million input tokens and 0.60 dollars per million output tokens off peak, and that DeepSeek announced V4 Pro would be routed to V4.1-Flash from 14 September and reversed that on 11 September.

DeepSeek V4.1-Flash arrived, and the V4 Pro retirement lasted a day

12 September 2026
Answer card stating that Cognition released SWE-2 on 10 September 2026, a coding model post-trained from Kimi K3, scoring 50.0 percent on FrontierCode 1.1 Main against 50.9 percent for Claude Fable 5.1 and 27.3 percent on Terminal-Bench 4 against 55.8 percent, available only inside Devin.

SWE-2 trails Fable 5.1 by one point, and by 28 on Terminal-Bench 4

11 September 2026
  • About
  • Contact
  • Privacy
  • Legal
Wednesday, September 23, 2026
  • Login
Packet Nebula
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About
No Result
View All Result
Packet Nebula
No Result
View All Result
Home Dev

Cohere Parse 5 is $1.50 per 1,000 pages, on three of five dimensions

by stephane
3 September 2026
in Dev
0
Official Cohere key art for the Parse 5 launch: the Cohere mark and the wordmark Parse with a superscript 5 in white, centred on a soft out of focus gradient of deep blue, violet and amber curves.
496
SHARES
1.4k
VIEWS
Share on FacebookShare on Twitter

A finance team handed us forty thousand scanned PDFs last spring and asked for clean Markdown. We priced the job against a frontier model, then quietly closed the spreadsheet. Cohere's Parse 5 is aimed at exactly that flinch: generally available since 27 August 2026, $1.50 per 1,000 pages, a 2.3B vision model that reads one page and returns Markdown with bounding boxes. It is not the best parser on the board and Cohere does not pretend otherwise. What we want to flag is the 79.2 ParseBench figure in the launch post. It averages three of the benchmark's five dimensions, and the two left out are the two where models of this shape usually fall over.

The short answer

Parse 5 turns a document page into Markdown with bounding boxes, cheaply and fast. The benchmark number Cohere leads with is a partial average, and the parts it skips are charts and visual grounding. Useful model, read the footnote before you promise anyone accuracy.
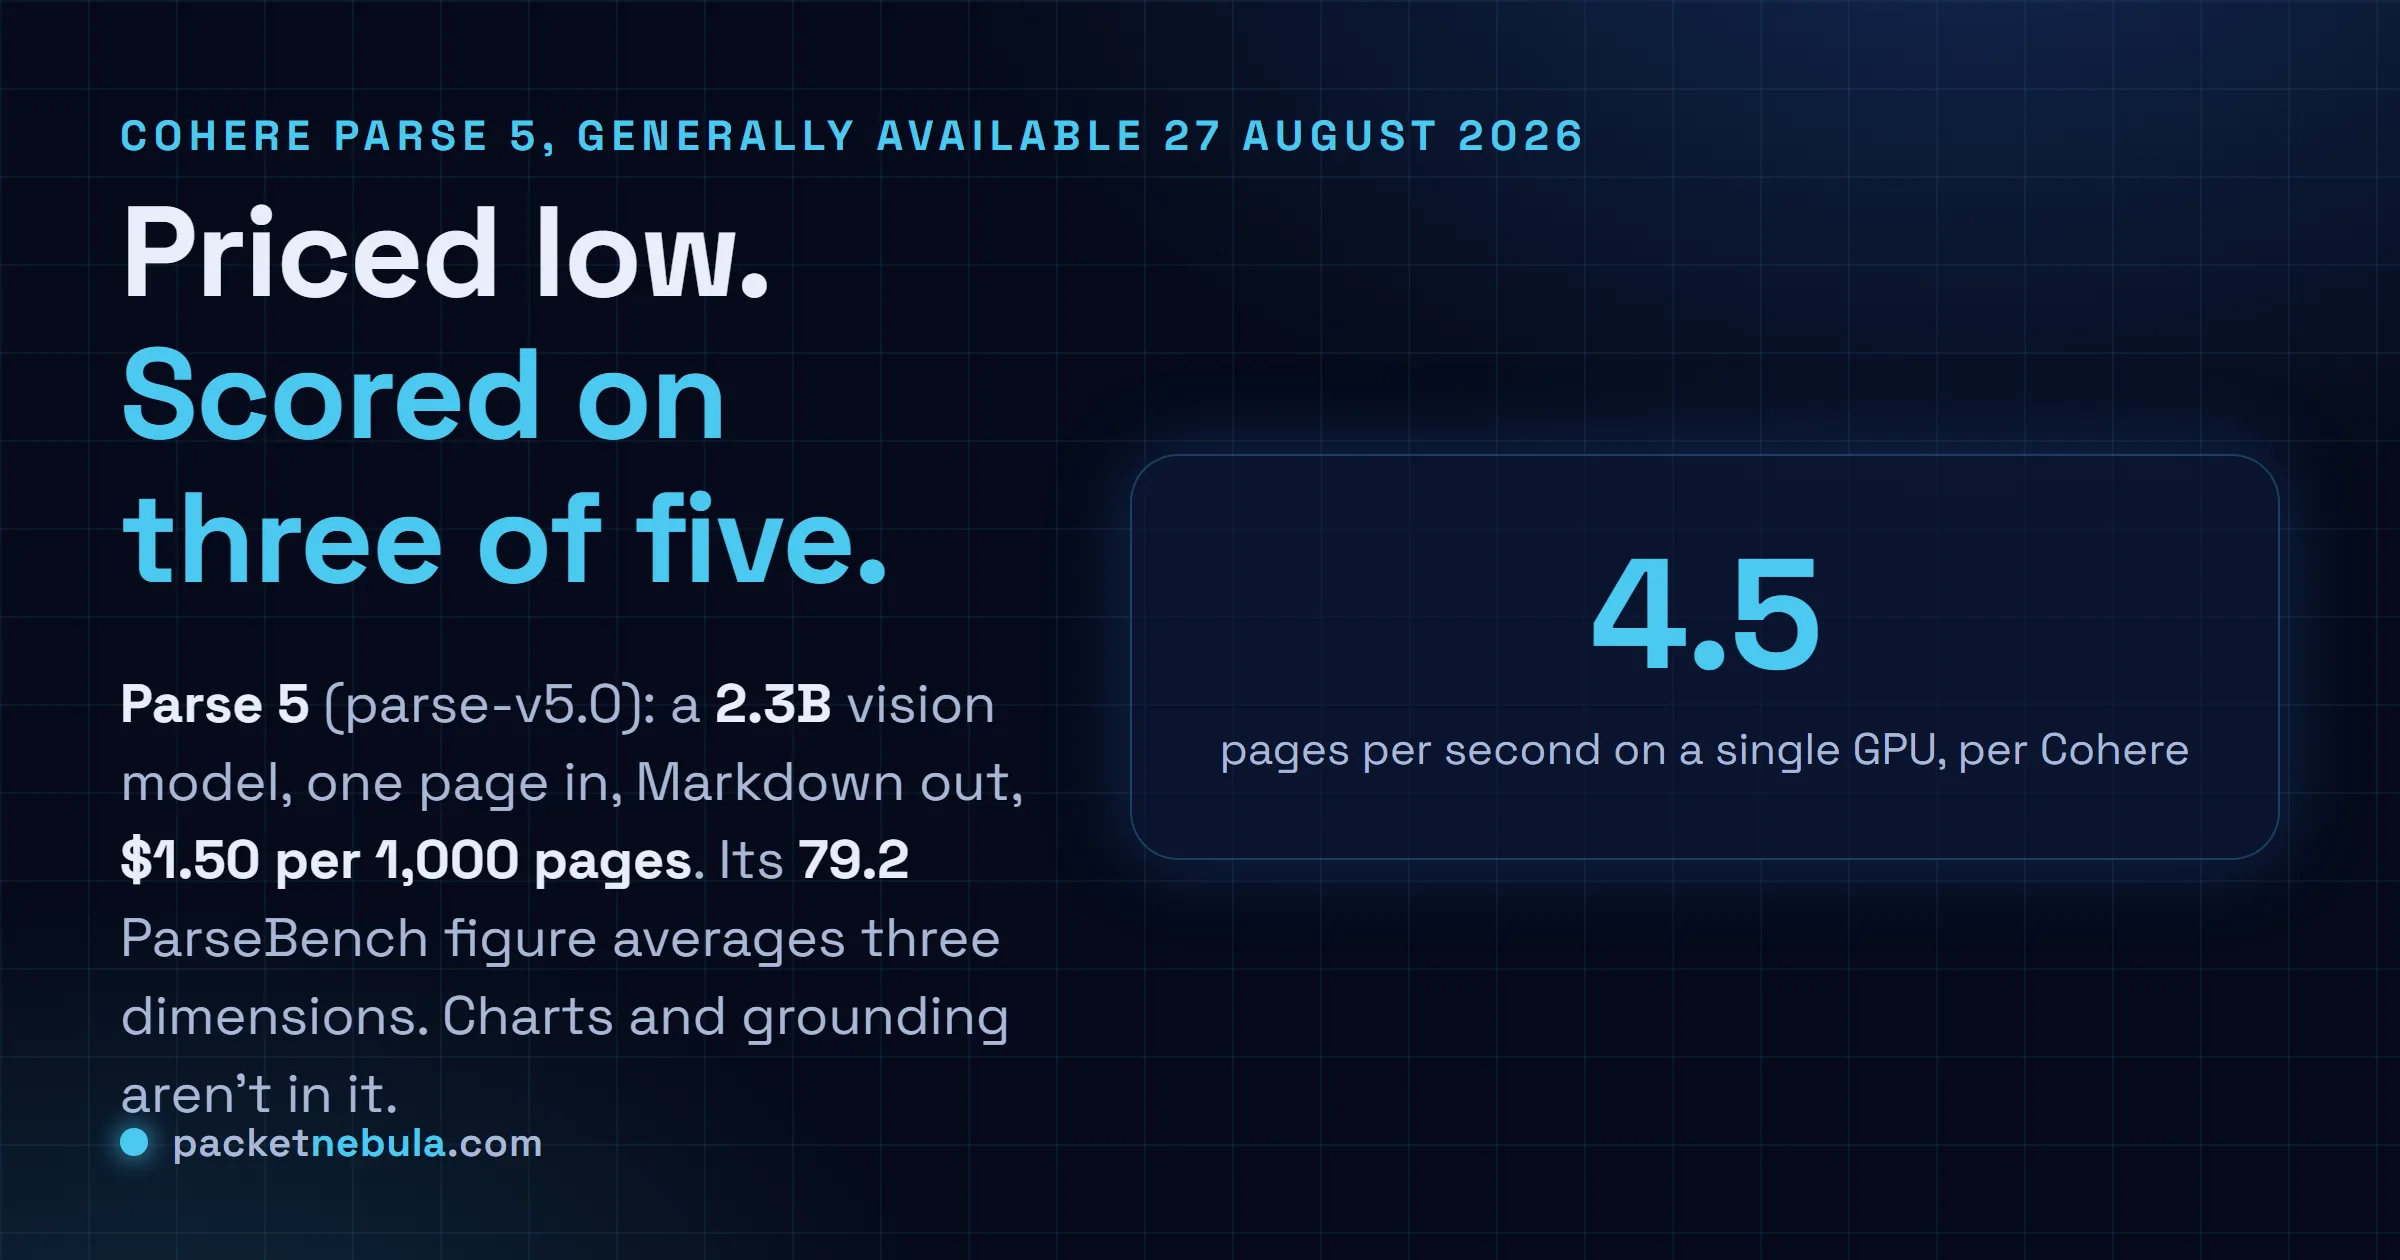
$1.50per 1,000 pages on the Cohere API
2.3Bparameters, about 4.6 GB
3 of 5ParseBench dimensions in the headline score
Answer card: Cohere Parse 5, model id parse-v5.0, generally available 27 August 2026, a 2.3 billion parameter vision language model that turns one PDF, PowerPoint or JPEG page into Markdown with bounding boxes at 1.50 dollars per 1,000 pages, with a quoted ParseBench score of 79.2 that averages three of the benchmark's five dimensions and leaves out charts and visual grounding, and a throughput figure of 4.5 pages per second on a single GPU.
The price, the size, and the asterisk on the score.

The number, and what is missing from it

Cohere leads with 79.2 on ParseBench and puts the component scores right there in the post: 87.0 on tables, 86.6 on content faithfulness, 64.0 on semantic formatting. Add those and divide by three and you get 79.2 exactly. That is how you know the other two dimensions are not in the average.

ParseBench has five. The two absent ones are charts and visual grounding, and they are not decorative. The benchmark’s own paper, arXiv 2604.08538 from the LlamaIndex team, is fairly blunt that grounding is where vision language models come apart: it reports GPT-5 Mini and Haiku below 8% on that dimension while older layout-detection parsers land somewhere in the 55 to 80 band. Grounding is the thing that lets an auditor trace an extracted figure back to a spot on a page. In regulated workflows that is not a nice-to-have.

Cohere does advertise bounding boxes as a feature, so the capability exists. It just is not in the number on the poster. Honestly, I do not read that as dishonest so much as normal launch behaviour, and Cohere published the breakdown that lets you catch it, which is more than most do.
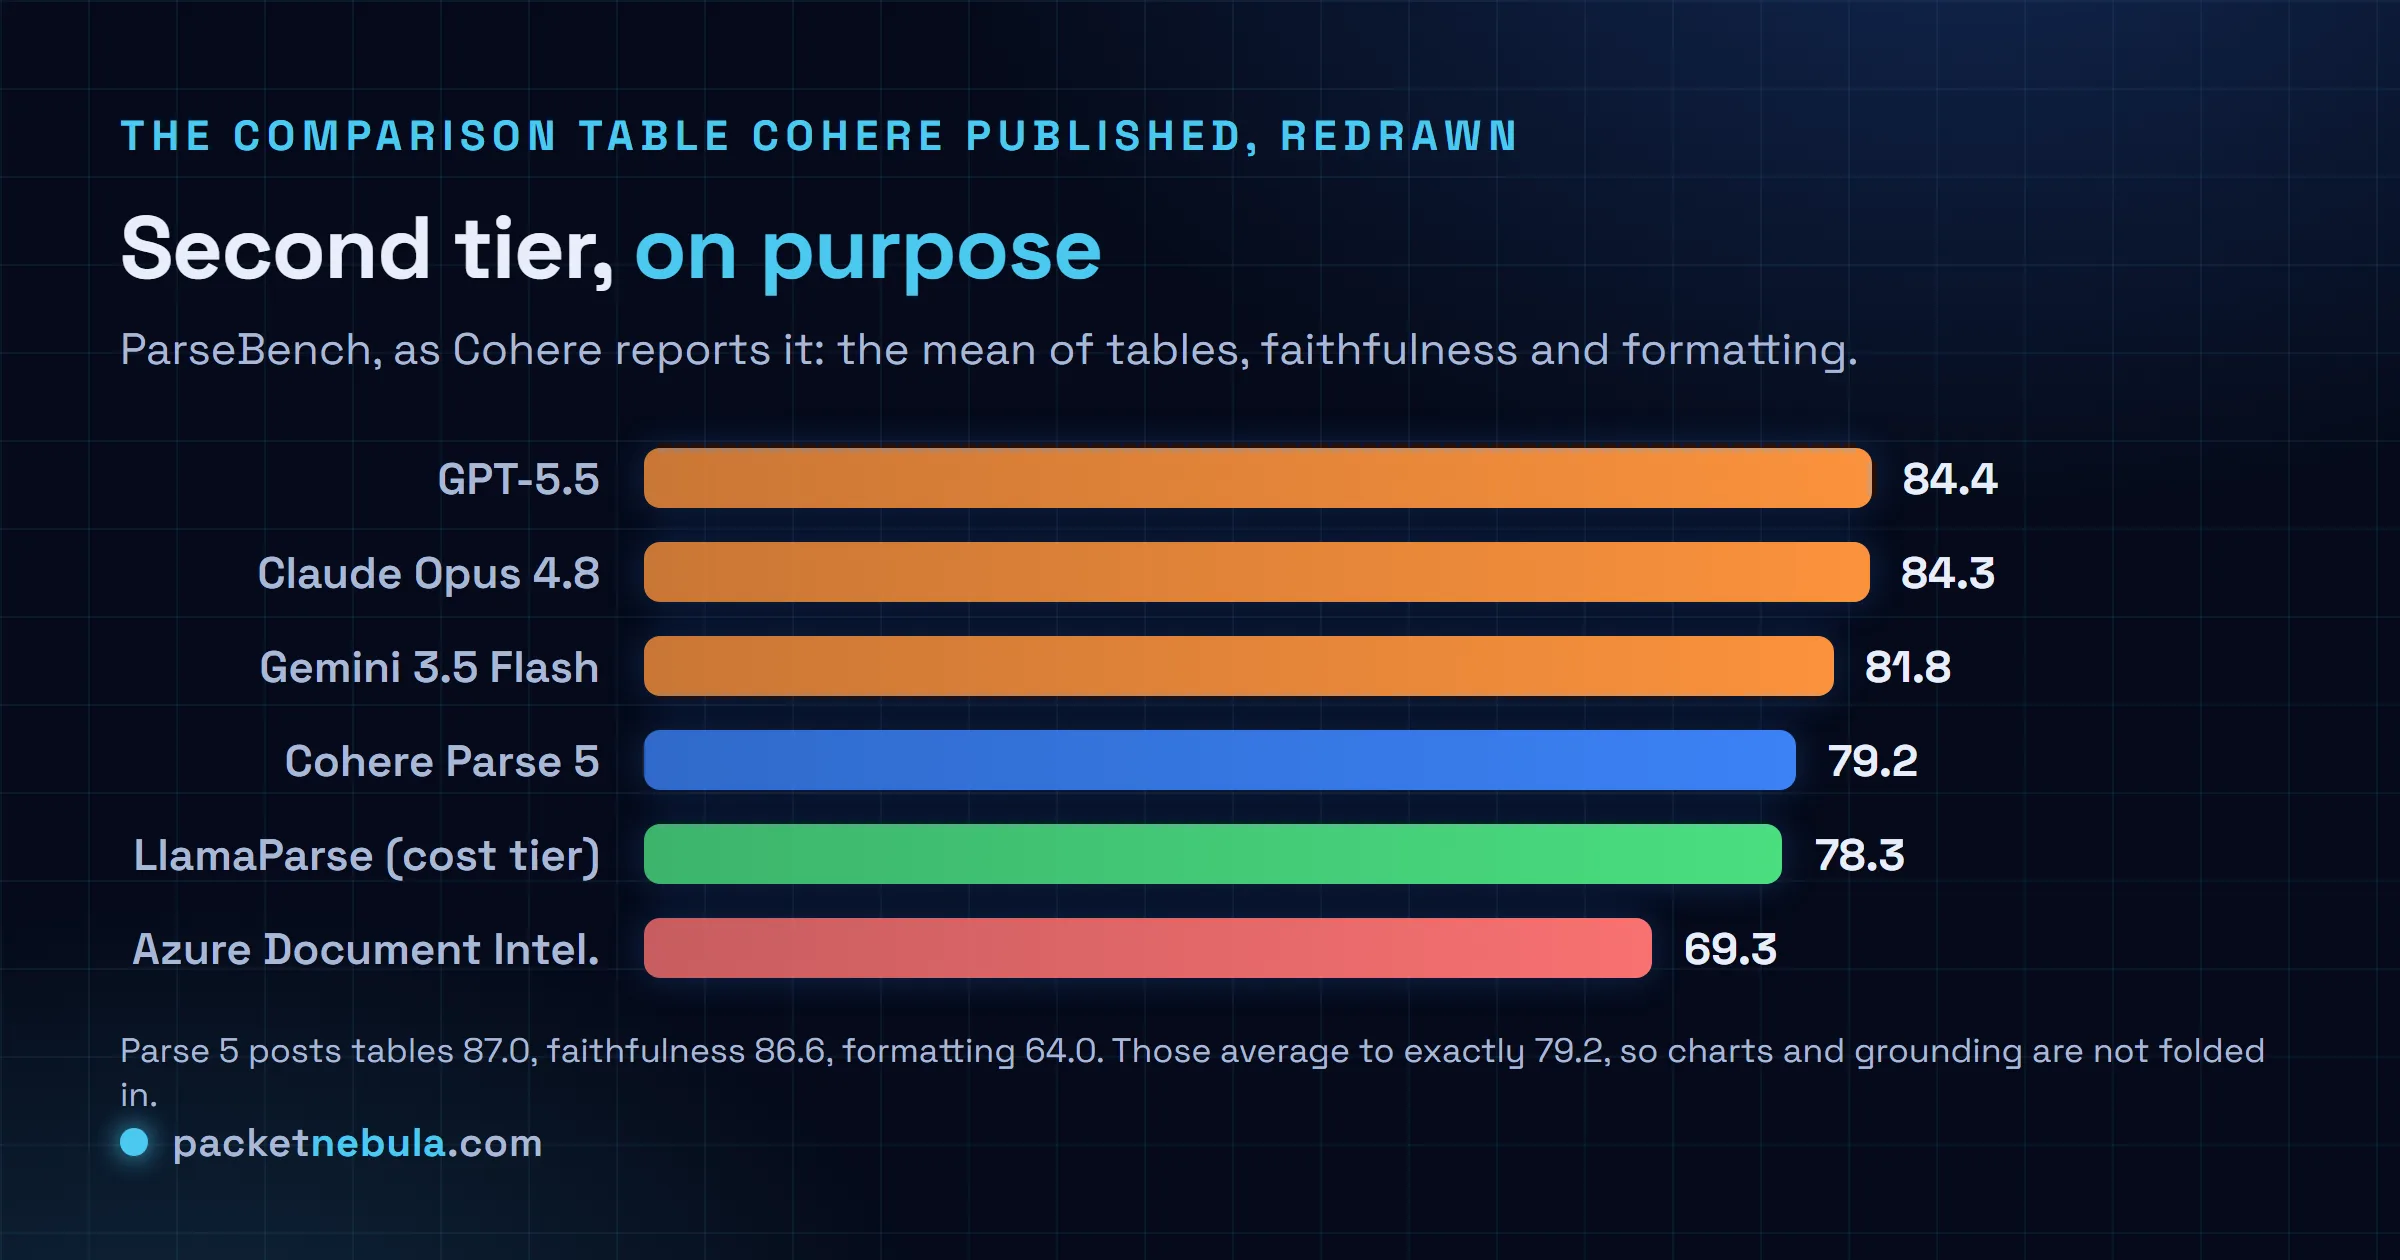
Bar chart of the ParseBench scores Cohere published beside Parse 5: GPT-5.5 at 84.4, Claude Opus 4.8 at 84.3, Gemini 3.5 Flash at 81.8, Cohere Parse 5 at 79.2, the LlamaParse cost tier at 78.3 and Azure Document Intelligence at 69.3, all on the three dimension average Cohere reports.
Cohere put the models that beat it in its own table. Credit where it is due.
Official Cohere key art for the Parse 5 launch: the Cohere mark and the wordmark Parse with a superscript 5 in white, centred on a soft out of focus gradient of deep blue, violet and amber curves.

Image: Cohere, from the Parse 5 announcement

The price is the actual product

$1.50 per 1,000 pages works out to $0.0015 a page. That is the whole pitch, and it is a good one, because document conversion is the least glamorous part of any retrieval pipeline and the one that quietly eats the budget.

Cohere’s own worked example is a company running 13 million pages a month. We checked the arithmetic and it holds together: 13 million pages at $0.0015 is $19,500 a month, so $234,000 a year on the API. Cohere says Model Vault saves that customer about $144,000 a year, which puts the single-tenant deployment near $90,000. Against hyperscaler document services at $10 per 1,000 pages, the same 156 million pages a year would run $1.56 million, and $1.56 million minus $90,000 is the $1.47 million saving Cohere quotes. The numbers are internally consistent, which is not always true of vendor cost slides.

The comparison against GPT-5.5 is a different animal. Cohere models a financial services workflow at 750 million documents a year and claims more than 98% cost reduction. Treat that as an estimate rather than a measurement, because it depends entirely on how many tokens a page turns into, and nobody publishes that number honestly.

What it is, mechanically

2.3 billion parameters, roughly 4.6 GB, built on Cohere Labs’ North-Micro-Vision-Instruct. Context window is 8,192 tokens. You hand it one page at a time as a base64-encoded data URI (our Base64 encoder is right here if you want to eyeball what your client is actually sending) and it returns Markdown: text in reading order, tables as HTML, lists, form key-value pairs, image descriptions, box coordinates.

That 8,192 figure matters more than it looks. This is a per-page tool. Whatever stitches pages back into a document, dedupes headers, or works out that a table runs across a page break, you are writing.

Throughput is 4.5 pages a second on one GPU, or 36 a second on an eight-card H100 node, which Cohere frames as 1.4x faster than dots.mocr and 2.2x faster than Chandra OCR 2. Nine languages hold accuracy. Everything else is zero-shot at lower accuracy, which is Cohere’s phrasing and we appreciate it being said out loud.
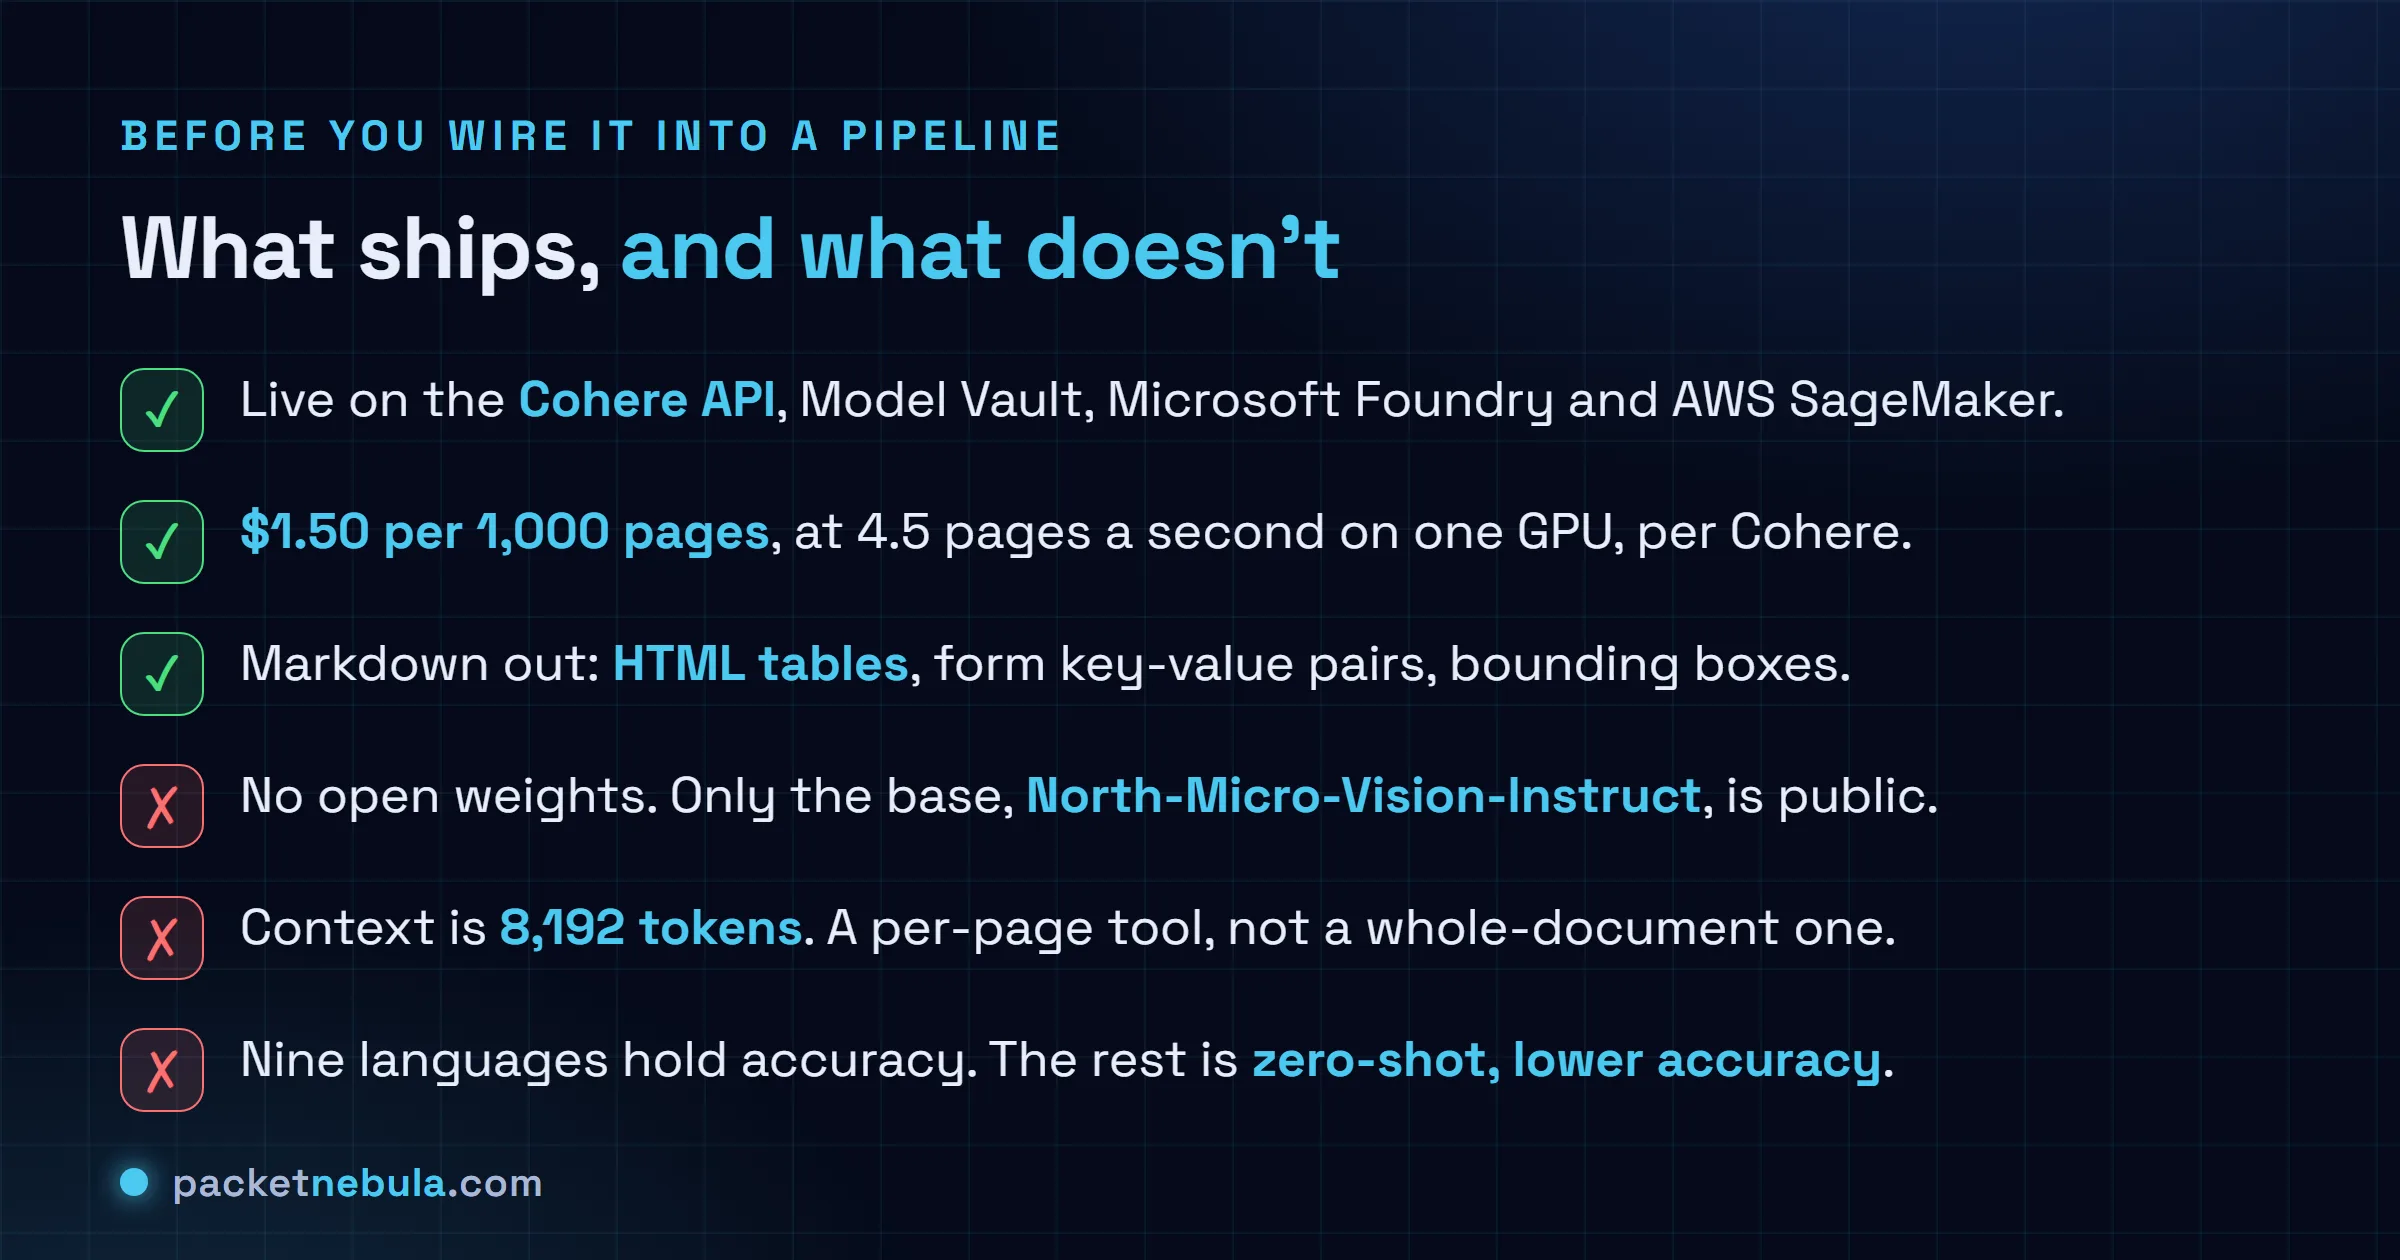
Checklist of what Cohere Parse 5 ships: available on the Cohere API, Model Vault, Microsoft Foundry and AWS SageMaker at 1.50 dollars per 1,000 pages and 4.5 pages a second on one GPU, with Markdown output carrying HTML tables and form key-value pairs and bounding boxes, but no open weights beyond the North-Micro-Vision-Instruct base, an 8,192 token context window, and only nine languages holding accuracy.
Three things to like, three to plan around.

When we would reach for it

If you are already paying frontier token rates to turn PDFs into text for a RAG index, run a bake-off. That is the case Parse 5 was built for, and a five point gap on a partial benchmark is cheap next to the invoice difference. Same shape of argument as Gemini 3.5 Transcribe, which also came fifth on quality and won on price.

If your documents are mostly charts, or an auditor needs every number traceable to a coordinate, do not take 79.2 as the answer. Test the two dimensions Cohere left out, on your own pages.

And if you needed open weights, this is not that release. The base architecture is on Hugging Face. The parser is a service.

Nils Reimers, who runs AI Search at Cohere, put the framing in one line that we think is right even if the launch numbers are selective:

Document parsing isn’t solved because the hard part isn’t reading text, it’s preserving structure and meaning.

Sources

Official announcement: Introducing Parse: Enterprise document intelligence at scale and the Parse product page. Independent coverage and the Reimers quote: VentureBeat and MarkTechPost. Benchmark definition and the grounding figures: ParseBench: A Document Parsing Benchmark for AI Agents and the run-llama/ParseBench repository. Availability on Azure: Microsoft Foundry. The cost arithmetic is our own, worked from Cohere’s published per-page price and its 13 million page example, on 31 August 2026.

Frequently asked questions

How much does Cohere Parse 5 cost?

$1.50 per 1,000 pages through the Cohere API, which is $0.0015 a page. Cohere also sells it through Model Vault, its single-tenant deployment, where it claims 23% savings against the API at 50% GPU utilisation and up to 61% at full hourly utilisation. Parse 5 is on Microsoft Foundry and AWS SageMaker too, and Cohere will deploy it in a private cloud or on-premises.

What is the ParseBench score of Parse 5?

Cohere reports 79.2, broken down as 87.0 on tables, 86.6 on content faithfulness and 64.0 on semantic formatting. Those three average to exactly 79.2, so the charts and visual grounding dimensions are not folded into that number. ParseBench itself is a five dimension benchmark from LlamaIndex, published as arXiv 2604.08538, built on roughly 2,000 human-verified pages from insurance, finance and government documents.

Is Parse 5 better than GPT-5.5 or Claude Opus at reading documents?

No, and Cohere's own table says so. On the three dimensions Cohere reports, GPT-5.5 scores 84.4 and Claude Opus 4.8 scores 84.3 against 79.2 for Parse 5. Gemini 3.5 Flash sits at 81.8. The pitch is not that Parse 5 wins, it is that you pay a per-page rate for a 2.3B model instead of frontier token pricing for a job that is mostly mechanical.

Are the Parse 5 weights open?

No. Parse 5 is served through the Cohere API, Model Vault, Microsoft Foundry and AWS SageMaker. The architecture it is built on, CohereLabs/North-Micro-Vision-Instruct, is published on Hugging Face, and there is a demo space, but the parse-v5.0 checkpoint itself is not a download.

What formats and languages does Parse 5 handle?

You send a PDF, PPT or JPEG page as a base64-encoded data URI and get back Markdown: text in reading order, tables rendered as HTML, lists, form key-value pairs, image descriptions and bounding box coordinates. Nine languages hold their accuracy (Arabic, English, French, German, Italian, Japanese, Korean, Portuguese, Spanish) with zero-shot support elsewhere at lower accuracy, in Cohere's own words. The context window is 8,192 tokens.

Tags: aicoheredocumentsllmnewsocr
Share198Tweet124
stephane

stephane

  • Trending
  • Comments
  • Latest
Answer card: Proton Lumo 2.0 is private by policy, not by locality. Saved history is locked so even Proton cannot read it, but the prompt is decrypted on a Proton EU server to answer it, then forgotten.

Proton Lumo 2.0 review: how private is it, really?

3 September 2026
The Agentic Coding section of the official Hy4 preview benchmark appendix published by Tencent, a table comparing Hy3 and Hy4 preview against DeepSeek V4 Pro 0813, Qwen 3.8 Max, GLM 5.3, Kimi K3, GPT 5.6 Sol and Claude Opus 5 across SWE-bench Multilingual, SWE-bench Pro, DeepSWE, three SWE Atlas tasks, SWE-Marathon, Terminal-Bench 2.1, NL2Repo-Bench, CyberGym, ProgramBench, PostTrainBench and Harbor-Index.

Tencent’s 770B Hy4 tops one benchmark row in 46

3 September 2026
Answer card: Qwen 3.7 Max is API-only and cannot run locally yet; the open Qwen models (Qwen 3.6 27B, qwen3:8b to 32b) run offline via Ollama.

Qwen 3.7 local: what you can actually run offline

22 June 2026
Answer card: JWTs are not encrypted, anyone can read them; the signature proves who issued the token, not who may read it.

Are JWTs encrypted? No, and the difference will bite you

0
Answer card: a random 8 character password falls in under 2 hours offline, while 16 random characters hold for 1.4 trillion years at the same speed.

How long does it take to crack a password in 2026?

0
Answer card: three DNS records decide if your mail lands or bounces; SPF lists allowed senders, DKIM signs messages, DMARC sets the failure policy.

SPF, DKIM and DMARC explained: the records your email needs

0
The official xAI announcement card for Grok 4.7, white type on a dark grey and navy gradient.

Grok 4.7 keeps $2 and $6, and its gains over 4.6 are xhigh versus high

22 September 2026
Answer card stating that Qwen-Image-2.1, released on 20 September 2026, ships open weights with a 7 billion parameter diffusion transformer, a Qwen3-VL 8B text encoder and an RGBA VAE totalling about 33 gigabytes in BF16, under the Qwen Research License that limits use to research or evaluation and requires a separate commercial licence, unlike the Apache 2.0 licence of Qwen-Image 1.0.

Qwen-Image-2.1 brings the weights back, but not the Apache licence

21 September 2026
Answer card stating that Ternary Bonsai 2 27B, released by PrismML on 17 September 2026 under Apache 2.0, packs Qwen3.8 27B into 5.95 gigabytes at 1.72 bits per weight, keeps 98.2 percent of the 14-benchmark average, about 75 percent on SWE-bench Verified and Terminal-Bench 2.1, and needs PrismML's llama.cpp fork to run.

Does Bonsai 2 27B really keep 98% of Qwen3.8 in 5.95 GB?

20 September 2026
  • About
  • Contact
  • Privacy
  • Legal

Copyright © 2026 Stephane Cardon.

Welcome Back!

Login to your account below

Forgotten Password?

Retrieve your password

Please enter your username or email address to reset your password.

Log In
No Result
View All Result
  • Home
  • Articles
    • Security
    • Network
    • Dev
    • Sysadmin
    • SEO
    • Email & DNS
  • Tools
    • Network tools: free, fast, no signup
    • Security tools: free, fast, no signup
    • Developer tools: free, fast, no signup
    • Sysadmin tools: free, fast, no signup
    • SEO tools: free, fast, no signup
    • Email & DNS tools: free, fast, no signup
  • Download
  • About

Copyright © 2026 Stephane Cardon.