Short version. A Hugging Face community post says you can speed up offline batch inference on mixture-of-experts models by 2% to 17% just by sorting the prompts before you call generate(). The numbers come from the authors' own runs on AMD MI300X with vLLM 0.27.1. It's cheap to try, it does nothing for dense models, and the repo's claim that outputs stay identical doesn't match the blog's own caveat.
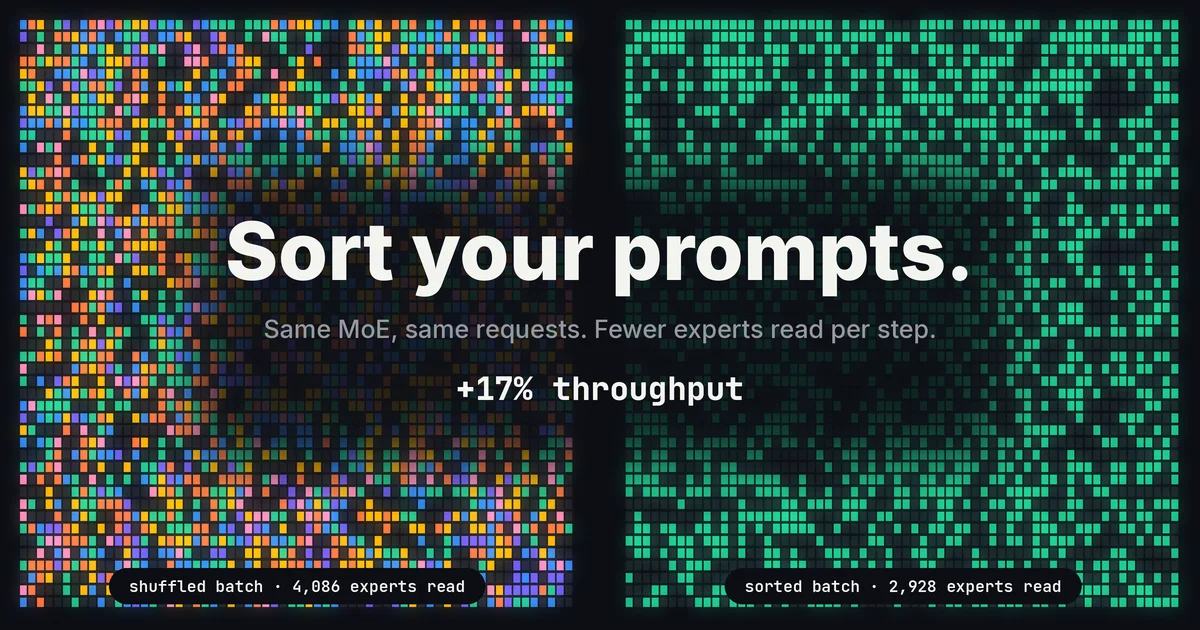
You've got 50,000 mixed prompts queued for an overnight job on a MoE model, and you feed them in whatever order the file happens to be in. That's probably leaving throughput on the table. According to a post published on 19 October by Abdennacer Badaoui and co-authors, grouping similar prompts into the same batch cuts the number of experts each decode step has to read, and that alone moved Qwen3-30B-A3B from 1,949 to 2,286 output tokens per second at batch 32. No new kernel, no model change.
Why sorting helps
A MoE decode step loads the weights of every expert that any token in the batch routes to. Mix code and French in one batch and you touch most of the model. The authors report that a mixed batch of Qwen3-30B-A3B hits about 94 of its 128 experts per layer, while a single-domain batch reads roughly 19% to 25% fewer. They put the cost at about 2.9 microseconds of kernel time per extra expert, and the relationship looked linear in their data.
The recipe is one line: compute an order, run argsort() over the prompt indices, generate, then put the outputs back in the original order. They tried three ways to build that order. True domain labels (code, math, prose, French, Arabic, Chinese) work best. Router fingerprints taken from prefill come next. Plain text embeddings from Qwen3-Embedding-0.6B plus k-means need no access to the model at all, and that's the one most of us would actually have.
What the numbers say, and what they don't
With true labels on vLLM 0.27, Qwen3-30B-A3B gained 13.5% at batch 16 (1,154 to 1,310 tok/s), 17.3% at batch 32, 12.6% at batch 64 and 11.6% at batch 128. gpt-oss-120b, which has only 32 experts, gained less: 6.9%, 12.2%, 10.6% and 9.1% over the same batch sizes. Swap the labels for embedding clusters and you're down to about 5% on Qwen3 and 2% to 4% on gpt-oss-120b, with next to nothing left at batch 128.
So the headline 17% is the best case: labeled data, one model, one batch size. The realistic figure for unlabeled production prompts is closer to 5%. That's still free, but it's not a reason to rebuild a pipeline.
A few more results matter if you can't sort the whole dataset. Reordering inside a window of 128 prompts gave +11.7%, a window of 256 gave +14.8%, and a full sort of 768 prompts gave +17.3%. The authors say a reorder window of four to eight batches keeps most of the gain. And two GPUs in expert-parallel mode still showed +12.9% at batch 64.
Here's what I'd flag. Everything ran on one hardware family (AMD Instinct MI300X) and one serving stack (vLLM 0.27.1, ROCm 10, PyTorch 2.12). We haven't seen anyone reproduce it on NVIDIA GPUs yet, and I wouldn't assume the same percentages carry over. Memory-bound decode is the mechanism, so I expect the direction to hold. I might be wrong about the size.
Where it bites, and one mismatch
This is for offline jobs. If you hold live requests back to group them, you're adding queueing delay to buy throughput, and the authors say so themselves. Prefill-heavy work gets little, because thousands of prompt tokens light up nearly every expert whatever the order. Dense models get nothing.
Now the mismatch. The repository README says outputs remain identical. The blog says sorting changes batch composition, and roughly 8% to 10% of outputs differ in fp16 or bf16 because of rounding, which the authors compare to the gap between two shuffled runs. Both can be true in a loose sense (the differences are numerical noise, not a quality loss), but they're not the same statement. If you diff outputs between runs for regression testing, expect noise and don't trust "identical".
Two housekeeping notes. The repo showed three commits and no clear license when we looked, so check before you copy the Triton kernel into anything shipped. And if you're choosing which open model to run in a batch job, our open-weight models tracker lists licenses, sizes and hardware needs row by row. Our guess is that most teams will try the embedding-cluster version first, see 5%, and decide it's worth an afternoon.
FAQ
Do I need to change my model or my inference server?
No. The post describes a change to the order of prompts before they reach vLLM's generate(). The repo also ships a Triton MoE kernel and a replay simulator, but the headline results don't depend on either.
Will it speed up a dense model?
No. A dense model reads all its weights on every step, so batch composition doesn't change the memory traffic. The authors list this as a limit.
Is this safe for live serving?
Not as described. Grouping requests means making some of them wait. The authors say it fits offline batch work best, and a small reorder window is the compromise if you need one.
Are the sorted outputs identical to the unsorted ones?
The repo says yes, the blog says about 8% to 10% differ in fp16 and bf16 because of rounding. We'd plan for the blog's version.
Sources. Badaoui et al., Sort your prompts: a free speed-up for MoE batch inference, Hugging Face (19 October 2026); sort-your-prompts repository, GitHub.


